

How to Fix Acrobat Crashing During OCR of Scanned Documents

Question details
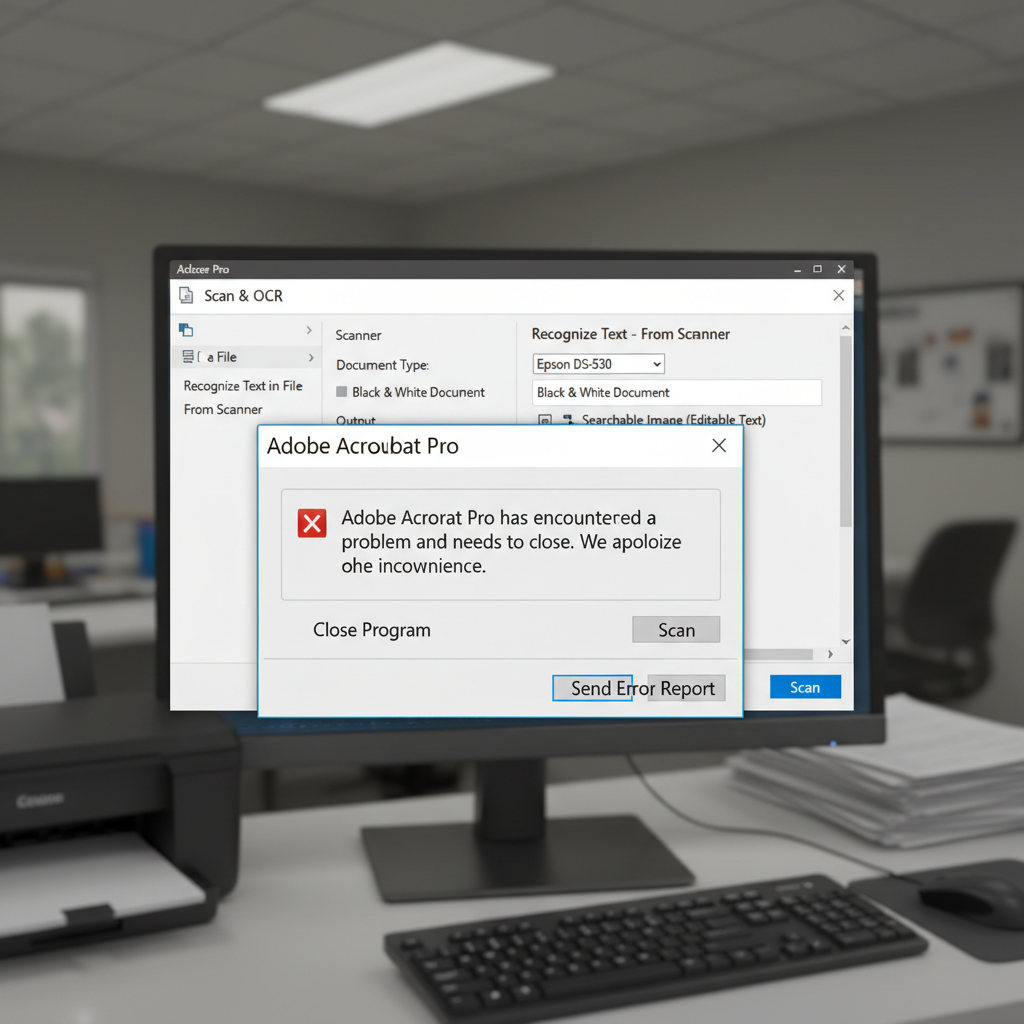
The user experiences unpredictable software crashes in Adobe Acrobat while attempting to perform Optical Character Recognition (OCR) directly on scanned documents.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to scan physical documents and immediately run OCR directly through the Adobe Acrobat scanning interface.
- Observed behavior
- Adobe Acrobat crashes unexpectedly during the scanning or OCR process, likely due to conflicts between the scanner's TWAIN driver, the operating system, and the software's direct scanning interface.
Before attempting to process your documents again, ensure that your scanner drivers are fully up to date and check that the physical documents are free from smudges or severe skewing.
Scan Documents Externally and Combine in Acrobat
Bypassing Acrobat's direct TWAIN scanning interface often resolves unexpected crashes by separating the scanning and OCR processes.
Acrobat relies on a TWAIN plug-in to access your scanner software. If there is a communication failure between the operating system, the scanner driver, and Acrobat, the program may crash without warning. Scanning your files externally avoids this complex interaction.
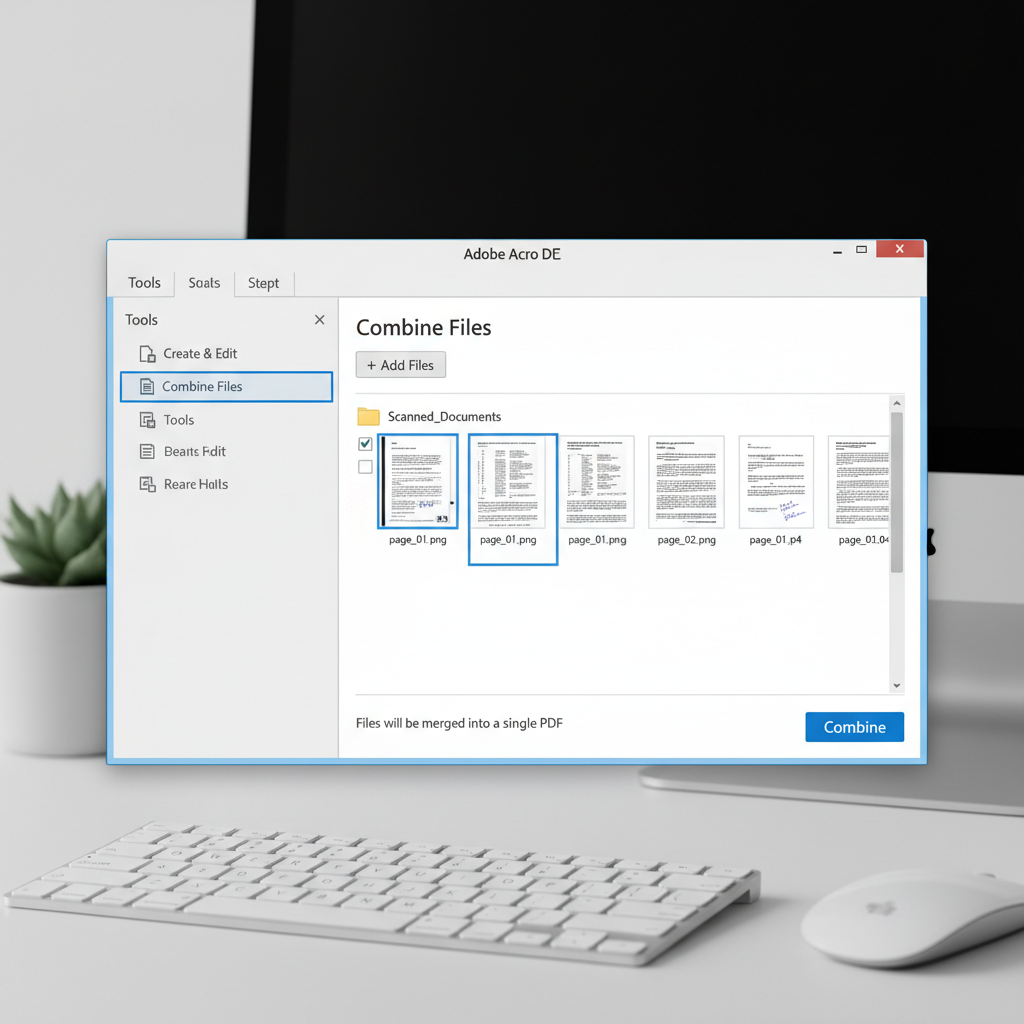
Open your scanner's native desktop application and scan your document pages directly into a dedicated folder on your computer as high-quality image files (such as PNG or JPEG).
Launch Adobe Acrobat, go to the 'Tools' menu, select 'Combine Files', and import all the newly scanned images to merge them into a single PDF document.
Save the combined PDF, then navigate to 'Scan & OCR' in the Tools menu and click 'Recognize Text' to process the entire document safely.
Improve Original Image Quality for Better OCR Processing
Low-quality, skewed, or low-contrast images can overload the OCR engine, resulting in processing failures or software crashes.
Extract Text from Scanned PDFs with WPS Office OCR
Avoid unexpected crashes and streamline your document workflow by using the highly stable OCR feature in WPS PDF. It accurately recognizes text from scanned images and converts them into editable, searchable formats seamlessly.
- 1. Open WPS PDF: Launch WPS Office and click on 'PDF' in the home interface to open the dedicated PDF viewer and editor.
- 2. Load your scanned document: Click 'Open' to load your scanned PDF document or image file into the workspace.
- 3. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button to launch the optical character recognition interface.
- 4. Extract and save: Choose your desired extraction format, such as 'Extract Text' or 'Convert to Word', and click the confirmation button to process and save your fully editable document.

Frequently Asked Questions
Why does my PDF software crash when running OCR?
Crashes during OCR are typically caused by conflicts between the scanning TWAIN driver, your operating system, and the PDF software. They can also occur if the software engine is overloaded by attempting to process overly complex, skewed, or extremely low-resolution images.
How can I improve OCR accuracy on scanned documents?
To improve accuracy, ensure your scans are captured at a minimum of 300 DPI. Increase the contrast so the text stands out from the background, keep the document perfectly aligned to avoid skewing, and ensure the original font is clean and legible.
Can I perform OCR on a scanned PDF without Adobe Acrobat?
Yes, many robust alternative PDF editors, including WPS PDF, feature built-in OCR capabilities. These alternatives can reliably convert scanned images into editable text formats without relying on Adobe Acrobat.


