

How to Fix Acrobat Creating Empty PDF Tags in Reading Order Tool

Question details
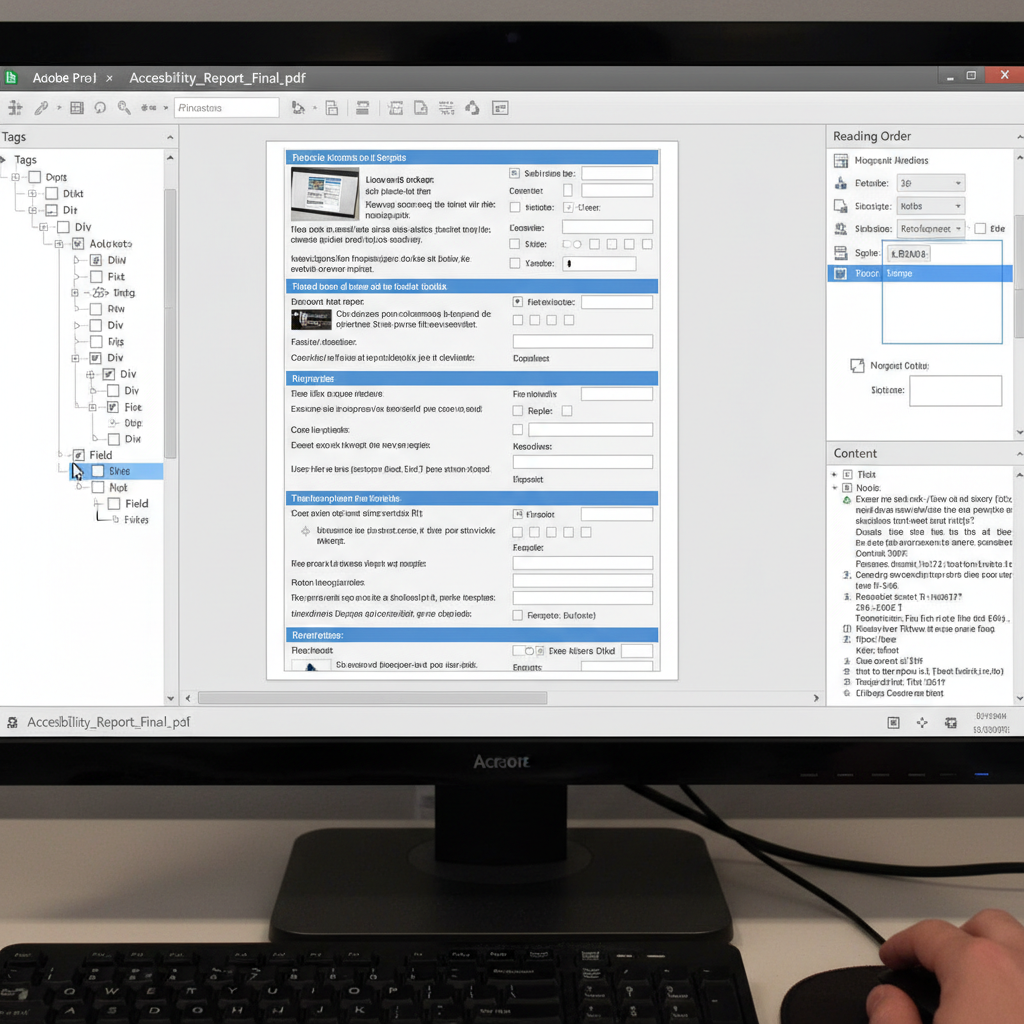
The user is experiencing issues in Adobe Acrobat where using the Reading Order tool creates empty PDF tags, leaving the actual text elsewhere in the Content pane, and preventing form fields from being tagged correctly.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Tagging a PDF document for accessibility using the Reading Order tool.
- Observed behavior
- The system generates empty tags instead of encompassing the selected text, and form fields fail to be tagged as expected.
Ensure that your PDF is fully searchable and has been properly processed with OCR (Optical Character Recognition) before applying tags, as scanned images without underlying text data cannot be tagged correctly.
Create a Clean PDF and Verify Tags with Highlight Content
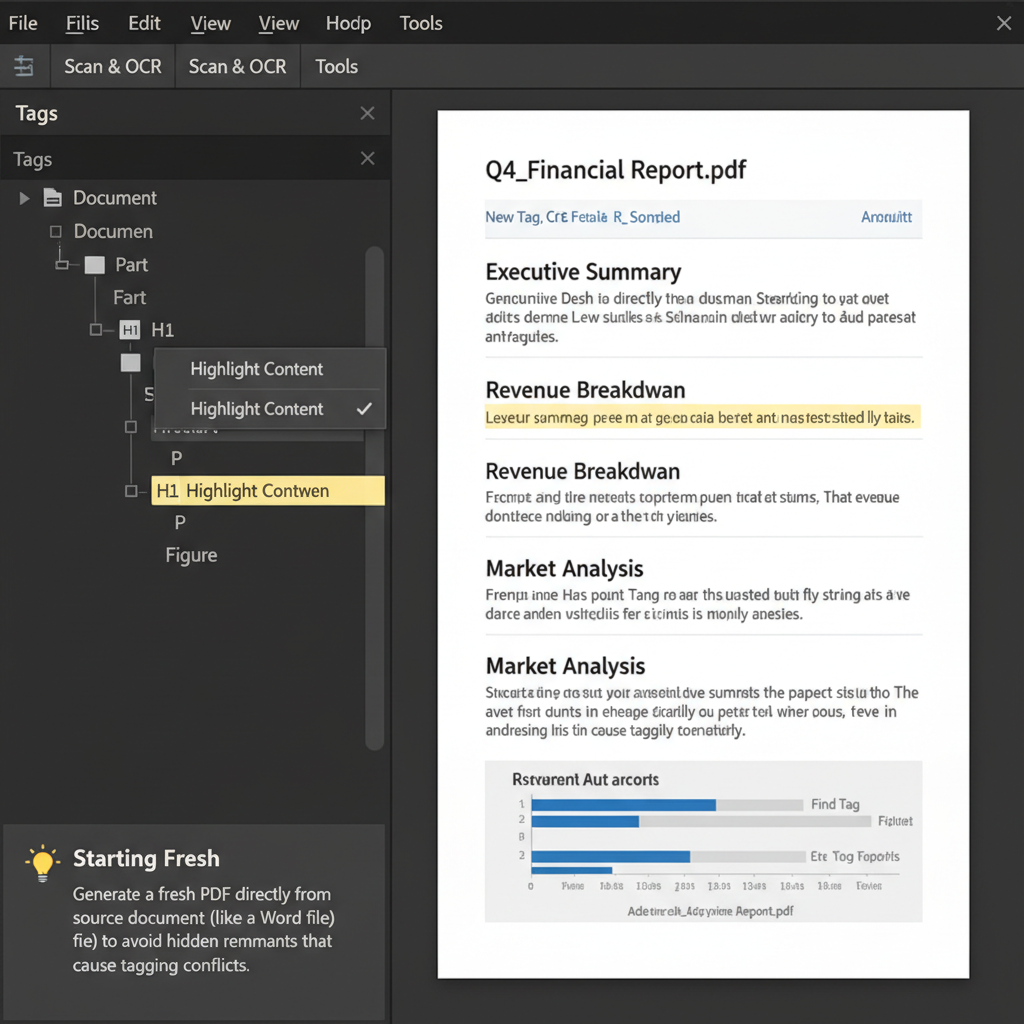
Starting with a clean, searchable PDF and using the Highlight Content feature helps identify if tags are correctly capturing text instead of generating empty containers.
A common cause of empty tags is an improperly recognized document. If the document has underlying corruption or hidden remnants from a previous format, the Reading Order tool struggles to associate the text with the newly created tag container.
If your PDF is a scanned image, navigate to the 'Scan & OCR' tool in Acrobat to recognize text fully before attempting to tag.
Open the 'Tags' panel on the left navigation pane. Click the Options menu (often represented by a small gear or list icon) and select 'Highlight Content'.
Click on individual tags in the tree. The corresponding text in the document should highlight on the screen, confirming it is linked properly and is not an empty tag.
Assign Elements to Specific Tags Using the Find Tool
When using 'Find Element' for unmarked annotations or form fields, you must select the destination tag first to prevent elements from being placed in an empty tag.
Create Clean, Searchable PDFs Easily with WPS Office
Avoid complex tagging issues by ensuring your PDF files are clean and fully searchable from the start. WPS Office provides powerful PDF editing and OCR (Optical Character Recognition) features to help you manage text and forms flawlessly.
- 1. Open your PDF: Launch WPS Office and open your PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and click on the 'OCR' button.
- 3. Convert to Searchable Text: Choose the extraction mode to convert scanned images into a clean, searchable PDF document.
- 4. Save the Document: Save your new document, which is now optimized for accurate text selection and processing.

Frequently Asked Questions
Why does the Reading Order tool create empty tags?
This usually happens if the PDF is not properly recognized via OCR, or if the underlying content structure is corrupted, causing the tool to create a tag container without successfully linking the text objects.
How do I ensure form fields are tagged properly in a PDF?
Use the Find tool in the Tags panel to locate 'Unmarked Annotations'. Ensure you select the target tag in the Tags tree before clicking 'Tag Element' so the form field is placed correctly.
Does 'Highlight Content' help fix tagging errors?
It doesn't fix them automatically, but enabling 'Highlight Content' in the Tags panel visually confirms whether a tag actually contains the correct text or if it is an empty tag.


