

How to Add Alternative Text to OCR Images in Adobe Acrobat

Question details
The user needs to correctly assign a figure tag and add alternative text to an image in a PDF document after running OCR.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Making a scanned PDF document accessible by adding descriptive alternative text to images after performing Optical Character Recognition (OCR).
- Observed behavior
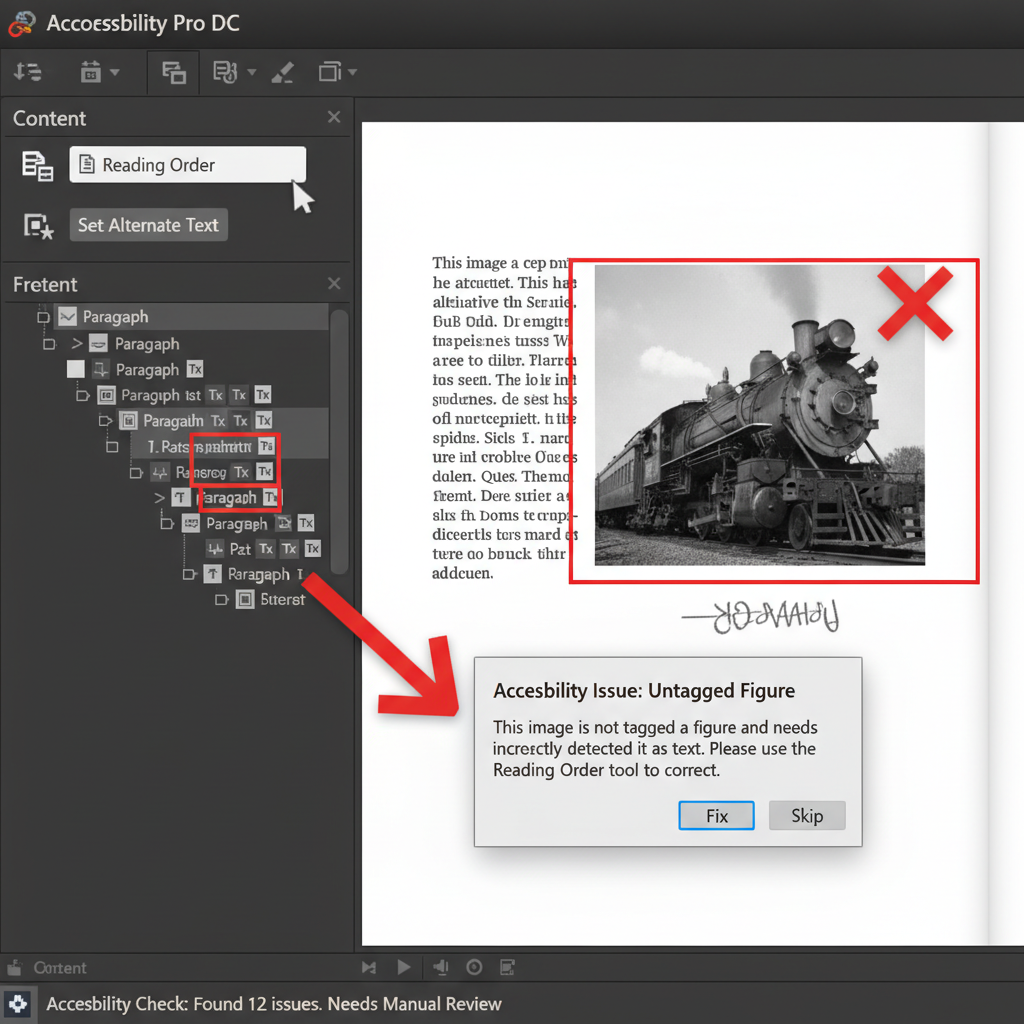
- Acrobat incorrectly tags images as text fragments and merges them with surrounding text lines in the Content panel, making it difficult to isolate the image to assign a figure tag and alternative text.
Ensure you have access to the Tags and Content navigation panes in Adobe Acrobat, and save a backup copy of your PDF before making manual adjustments to the document's tag tree.
Fix Image Tagging and Add Alt Text via the Tags Panel
Use the Tags panel and Reading Order tool to manually isolate the image object from the text and apply the correct Figure tag.
When Acrobat's OCR engine merges images and text, the Content panel may group them together. By navigating through the Tags panel or using the Reading Order tool, you can override these automatic groupings and properly designate figures.
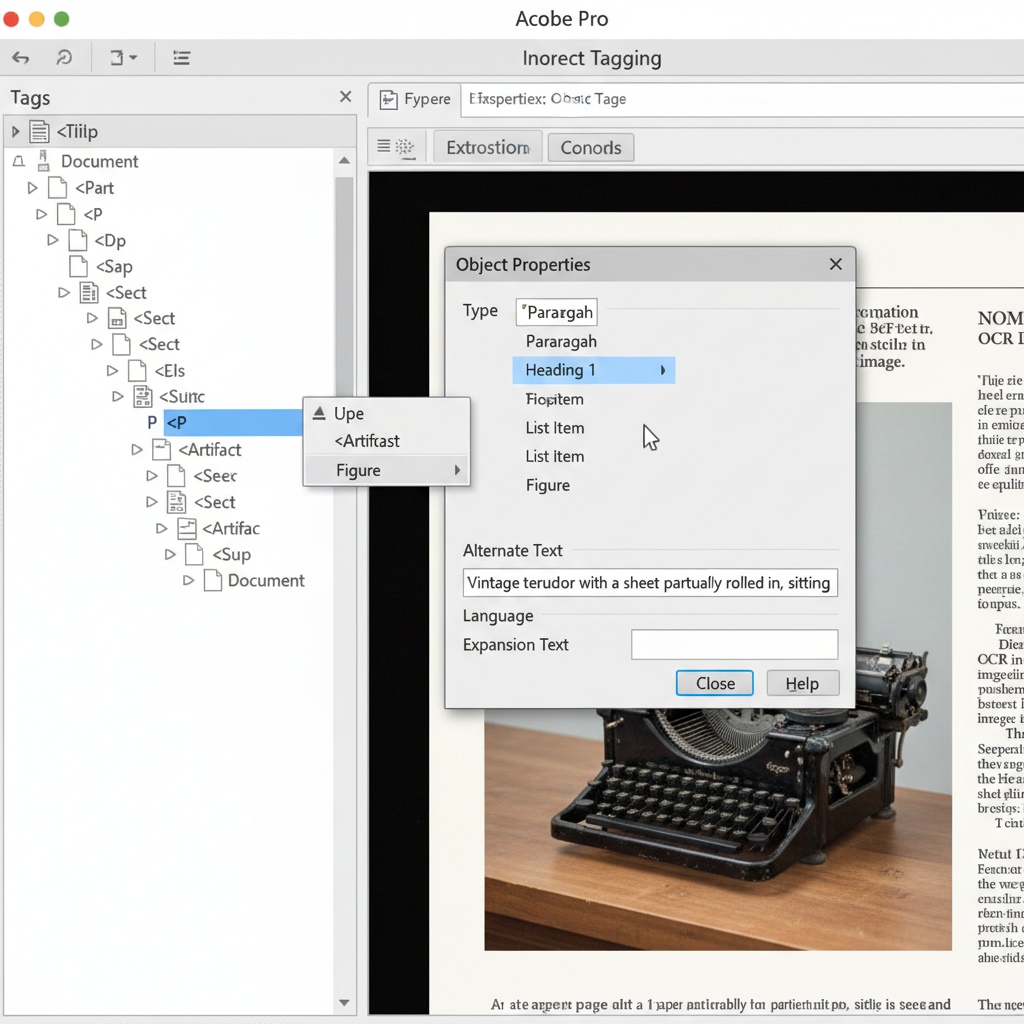
Navigate to View > Show/Hide > Navigation Panes > Tags to display the document's tag tree on the left side of the screen.
Expand the tags corresponding to the page where the issue occurs. Find the actual image object within the tree, rather than selecting the combined OCR text line.
Right-click the isolated image object, select 'Properties', and change the 'Type' dropdown in the Tag tab to 'Figure'.
In the same Object Properties dialog box, locate the 'Alternate Text' field, type in your descriptive text for the image, and click 'Close'.
Alternatively, open the Accessibility tools, select 'Reading Order', draw a rectangle specifically around the image area, click 'Figure', and then right-click the new figure to select 'Edit Alternate Text'.
Rerun OCR with Adjusted Page Layout Settings
If the tag tree is too complex to edit manually, rerunning OCR with different output settings can help Acrobat correctly separate images from text.
Edit PDFs and Perform OCR Easily with WPS Office
WPS Office provides a powerful, user-friendly PDF editor that allows you to perform highly accurate OCR, edit text, and manage PDF elements without the complex tagging issues often found in other software.
- 1. Open your scanned PDF: Launch WPS Office and open your scanned document in the WPS PDF editor.
- 2. Access the OCR tool: Navigate to the 'Tools' tab and click on the 'OCR' button.
- 3. Choose your output format: Select whether you want to extract the text only or convert the scanned document into a fully editable format, then run the process.
- 4. Edit images and text: Once converted, simply click on any image or text block to replace, modify, or format it directly within the editor.

Frequently Asked Questions
Why does Acrobat tag my images as text after running OCR?
During the OCR process, Acrobat attempts to recognize all visual elements on the page. If an image contains text-like patterns or is positioned very closely to text, the OCR engine may misinterpret it as a text fragment and merge it into a single text block.
How do I view the Tags panel in Adobe Acrobat?
You can open the Tags panel by going to View > Show/Hide > Navigation Panes > Tags. If the Tags option is not listed, you may need to right-click the empty space in the left navigation pane and select 'Tags' to make the icon visible.
Can I add alternative text without manually editing the Tags panel?
Yes, you can use the Set Alternate Text tool by going to Tools > Accessibility > Set Alternate Text. Acrobat will scan the document for figures and prompt you to enter alt text for each one. However, this relies on the images being correctly tagged as figures by the OCR process beforehand.
What is the Reading Order tool used for in Acrobat?
The Reading Order tool allows you to visually correct the reading order and structural tagging of a PDF. You can draw rectangles around page content and explicitly define them as Text, Figure, Table, or other structural elements, which is especially useful for quickly fixing OCR tagging errors.


