

How to Fix Acrobat Exporting Corrupted PDF Text to Excel
Question details
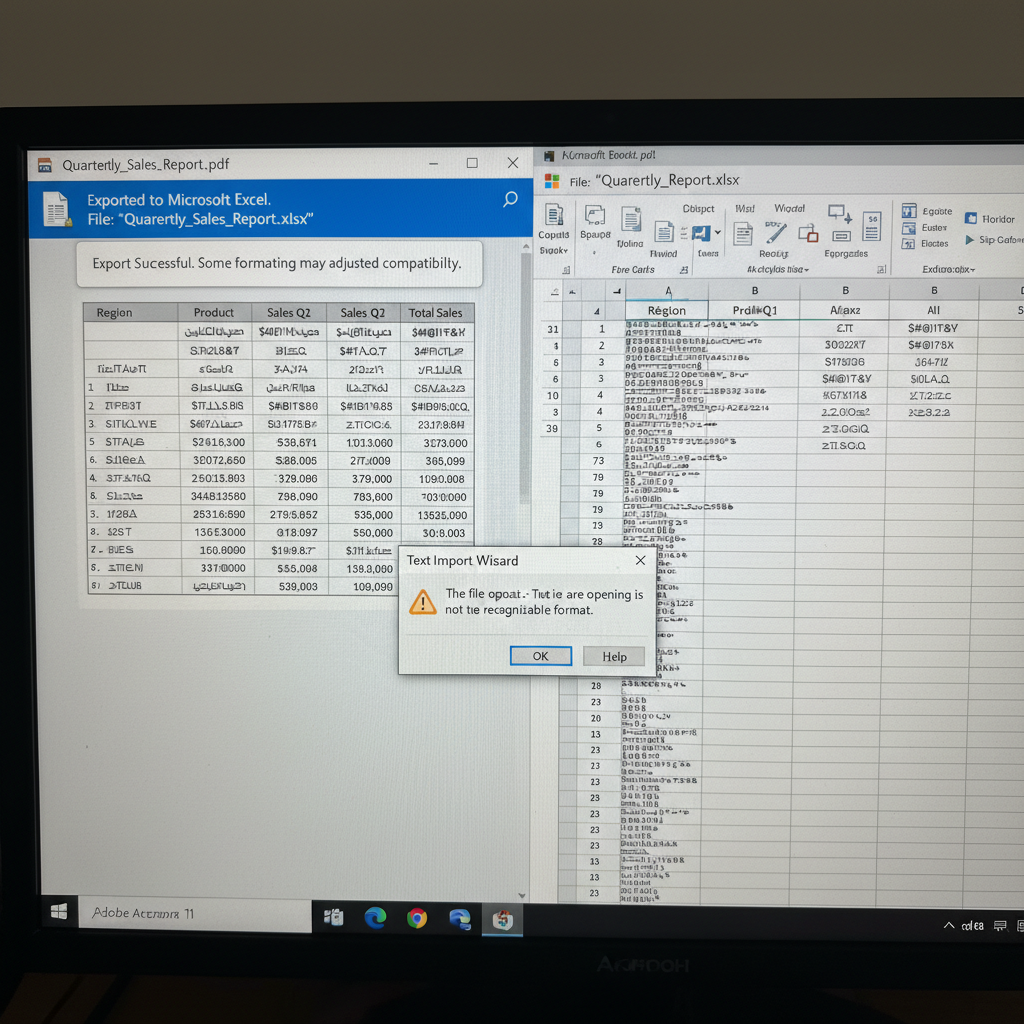
The user is experiencing an issue where a PDF exported to an Excel spreadsheet results in corrupted, garbled, or unreadable characters.
- Product
- Adobe Acrobat, Microsoft Excel
- Device & OS
- not provided
- Scenario
- Exporting a PDF document containing data or tables into Microsoft Excel to analyze or edit the data.
- Observed behavior
- The resulting Excel file displays unreadable gibberish instead of the original text, indicating a failure in interpreting the PDF's text layer.
Before attempting conversion fixes, copy a small snippet of text directly from the PDF and paste it into a plain-text editor like Notepad to see if the underlying text encoding is already broken.
Diagnose and Bypass Damaged Text Encoding
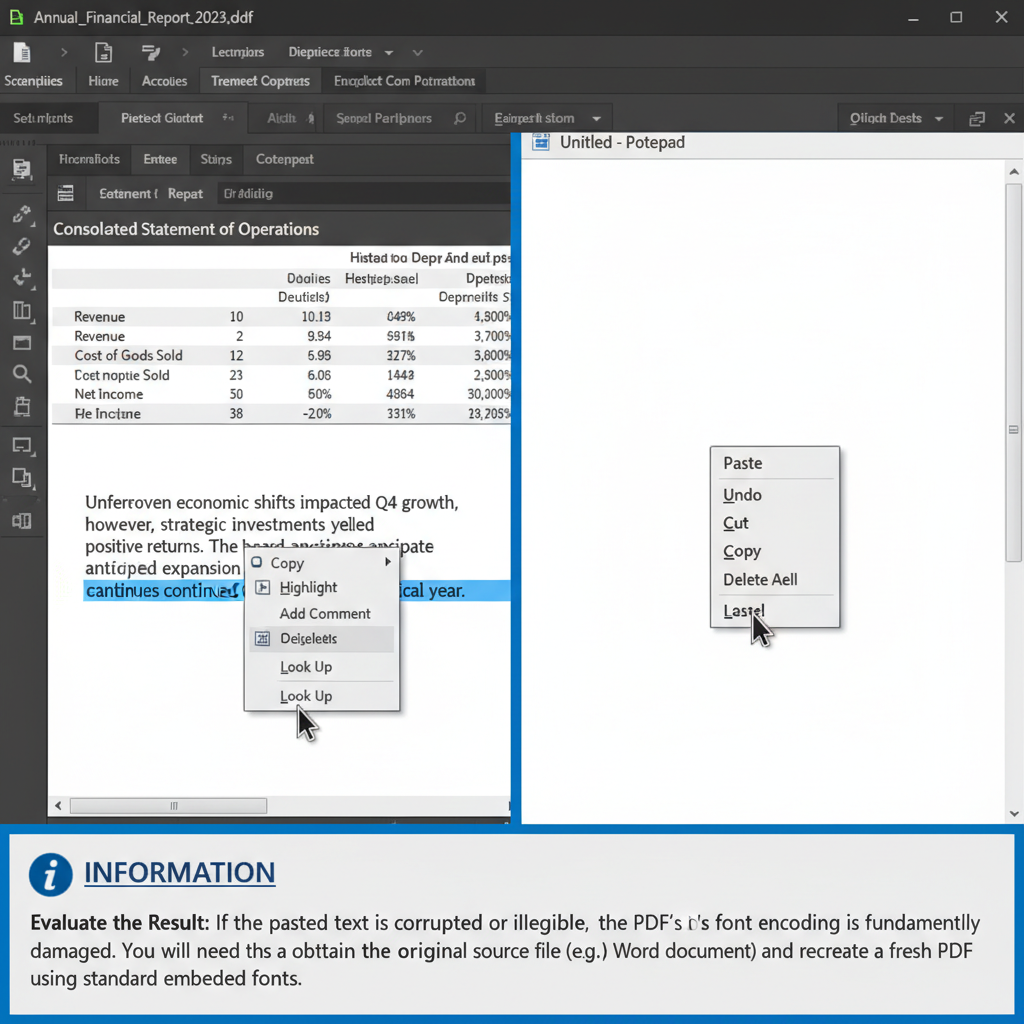
Use a plain-text editor to determine if the PDF's internal font mapping is corrupted. If the text pastes as gibberish in Notepad, the issue is with the file's encoding, not the export process.
Unreadable characters during an Excel export usually indicate damaged text encoding or unusual subsetted fonts. When software cannot properly map the visible characters to their Unicode values, it outputs garbled text.
Open the problematic PDF in Adobe Acrobat, highlight a few sentences or table rows, right-click, and select 'Copy'.
Open Notepad (or any plain-text editor) on your computer, right-click in the blank document, and select 'Paste'.
If the pasted text is corrupted or illegible, the PDF's font encoding is fundamentally damaged. You will need to obtain the original source file (e.g., Word document) and recreate a fresh PDF using standard embedded fonts.
Run Optical Character Recognition (OCR) on Scanned PDFs
If the PDF is an image-based scan lacking a usable text layer, running OCR will generate readable text that can be successfully exported to Excel.
Convert PDF to Excel Flawlessly with WPS Office
Bypass complex Acrobat errors by using the robust PDF to Excel converter built into WPS Office. It features powerful, highly accurate OCR capabilities that seamlessly extract data from both standard and scanned PDFs directly into editable spreadsheets.
- 1. Open PDF in WPS Office: Launch WPS Office, click on 'PDF' in the home screen, and open your target document.
- 2. Select PDF to Excel: Navigate to the 'Tools' tab on the top ribbon and click on the 'PDF to Excel' button.
- 3. Configure OCR Settings: In the conversion dialog box, ensure that OCR is enabled if you are converting a scanned or image-based PDF, and select the correct document language.
- 4. Convert and Edit: Click 'Convert' to instantly generate a clean, editable Excel spreadsheet without corrupted characters.

Frequently Asked Questions
Why does my PDF look perfectly fine on screen but export as gibberish?
This happens when the PDF uses custom or subsetted fonts without proper Unicode mapping. The visual shapes (glyphs) tell the screen how to display the letters, but the underlying text data needed for exporting or copying is missing or corrupted.
Can I permanently fix a PDF that has severely damaged text encoding?
Usually, no. If the text encoding is fundamentally broken (which you can verify by pasting it into Notepad), the data cannot be reverse-engineered by conversion software. You will need to request the original source document and export a new PDF.
How do I check if my PDF is an image rather than text?
Try to click and drag your cursor to select individual words or characters. If the highlight selects the entire page as one large block, or if you cannot select text at all, the document is an image-based scan.
Does using OCR guarantee perfect text conversion to Excel?
While OCR drastically improves data extraction from scanned documents, its accuracy relies heavily on the quality, contrast, and resolution of the original image. Always review the final Excel file for minor typographical errors.


