

How to Fix Unreadable Text When Converting PDF Tables to Excel
Question details
Users experience garbled, unreadable, or missing text when converting PDF documents containing tables into Excel format.
- Product
- PDF Converters and Spreadsheets
- Device & OS
- not provided
- Scenario
- Extracting tabular data from a PDF file into an Excel spreadsheet for editing and analysis.
- Observed behavior
- The resulting Excel file displays unreadable characters, broken formatting, or empty cells instead of the original text.
Check if your original PDF contains selectable text by trying to highlight the words. If you cannot select the text, the document is likely a scanned image that will require Optical Character Recognition (OCR).
Apply OCR to Extract Text from Scanned PDFs
If your PDF is an image or scanned document, standard conversion will fail. Using an OCR tool recognizes and extracts the actual text.
Standard PDF converters simply attempt to map embedded font characters to Excel cells. When a document is scanned, there are no actual text characters to map—only an image of a table. Running Optical Character Recognition (OCR) analyzes the shapes in the image and translates them back into selectable text before conversion.
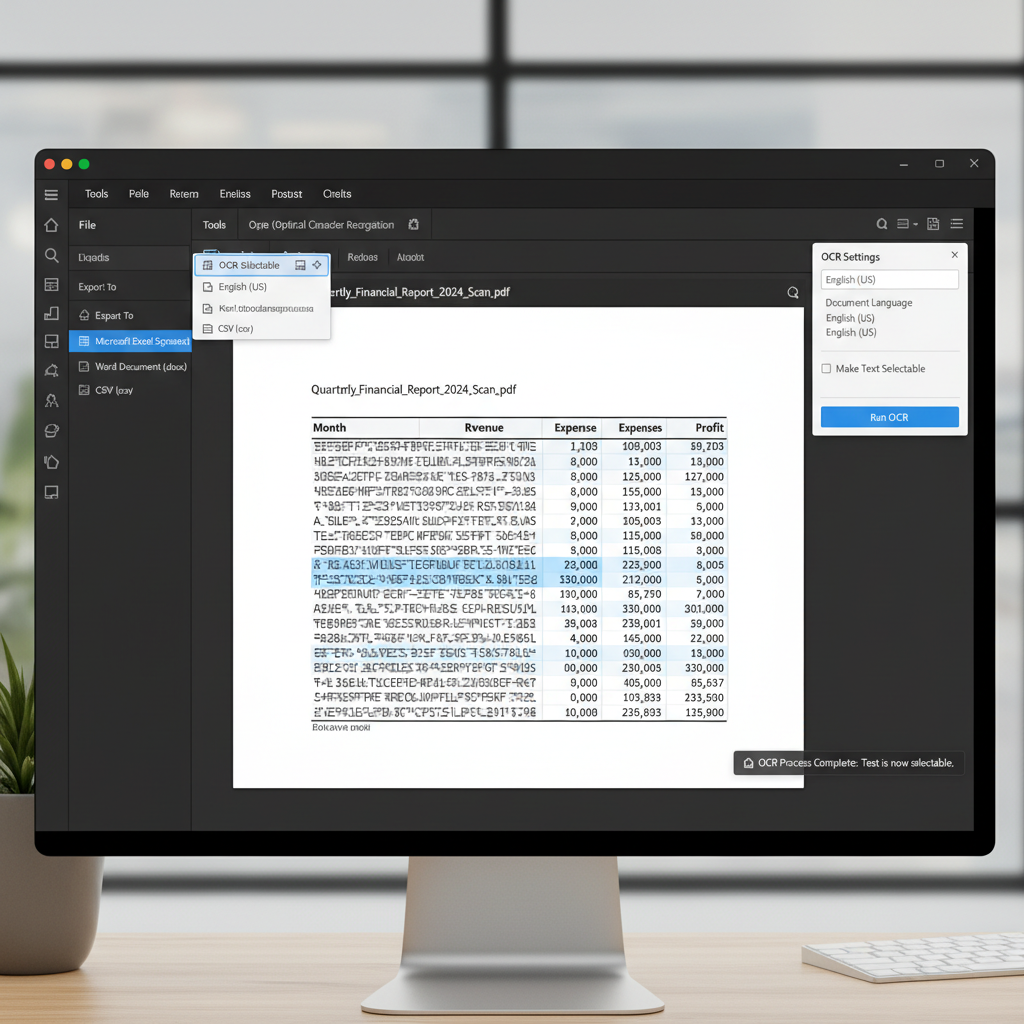
Launch your advanced PDF editor and open the scanned PDF document that contains the table.
Navigate to the Tools menu and select the OCR (Optical Character Recognition) feature. Choose the correct document language to ensure accurate text recognition.
Once the OCR process is complete and the text becomes selectable, proceed to the 'Convert to Excel' or 'Export to Spreadsheet' option in your software.
Address Font Issues and Manually Clean Up Tabular Data
Unreadable text can also be caused by missing source fonts or highly complex table structures in the original document.
Use WPS Office to Extract Unreadable PDF Tables Perfectly
WPS Office provides a highly accurate, built-in PDF to Excel converter powered by advanced OCR technology. It easily recognizes scanned text, preserves complex table structures, and eliminates formatting errors.
- 1. Open PDF in WPS Office: Launch WPS Office and open your unreadable or scanned PDF file directly in the application.
- 2. Select PDF to Excel: Go to the 'Tools' tab on the top ribbon and click on the 'PDF to Excel' conversion button.
- 3. Enable OCR: Check the prompt to enable the OCR function and verify the document language matches your table's contents.
- 4. Export and Edit: Click 'Convert' to save the file as an .xlsx document. The file will automatically open in WPS Spreadsheet for immediate formatting and editing.
Frequently Asked Questions
Why do some PDF tables turn into weird symbols in Excel?
This usually happens when the original PDF was created with custom or un-embedded fonts. When converted, the software cannot map the original characters, resulting in wingdings or garbled symbols. Requesting a PDF with embedded fonts or using a premium OCR tool can bypass this.
Can I convert a scanned PDF to Excel without paying for expensive software?
Yes, modern all-in-one office suites like WPS Office offer built-in PDF to Excel conversion with OCR capabilities that can accurately extract tabular data from scanned documents, eliminating the need for expensive standalone converters.
How do I fix merged columns after converting a PDF to Excel?
If the conversion merges your columns due to complex PDF layouts, you can use the 'Text to Columns' feature found under the Data tab in Excel. This allows you to manually split the combined text back into separate cells based on spacing or delimiters.
Does OCR work for handwritten tables in a PDF?
OCR accuracy drops significantly for handwritten text compared to printed text. While advanced OCR tools might capture some clearer words, you will likely need to perform substantial manual data entry and cleanup in Excel.


