

How to Fix Acrobat Selecting Vertical Blocks Instead of Text After OCR

Question details
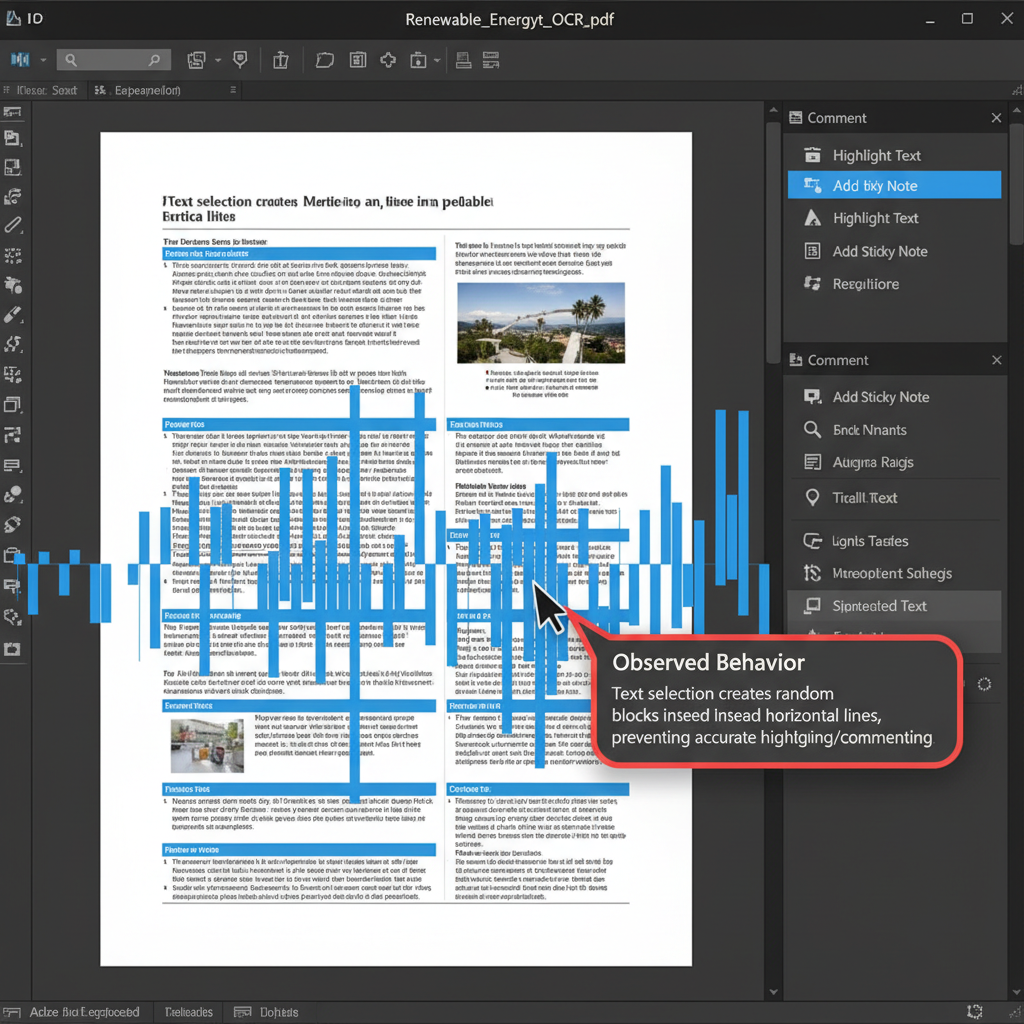
The user is unable to select horizontal text lines for highlighting or commenting after running OCR, as the cursor selects random vertical blocks instead.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Attempting to highlight, copy, or add comments to text in a PDF document after applying OCR text recognition.
- Observed behavior
- Selecting text produces erratic, random vertical blocks instead of standard horizontal lines of text, preventing accurate annotations.
Ensure your Adobe Acrobat Pro DC is updated to the latest version and verify that the original scanned document is properly aligned and legible, as tilted pages often cause text recognition errors.
Rerun the OCR (Recognize Text) Process
Re-processing the document can overwrite poorly generated text layers that cause erratic vertical selection blocks.
Sometimes the OCR engine creates overlapping or misaligned bounding boxes for words, especially if the document is complex or the initial process was interrupted. Running the OCR recognition again can force the software to rebuild the invisible text layer accurately.
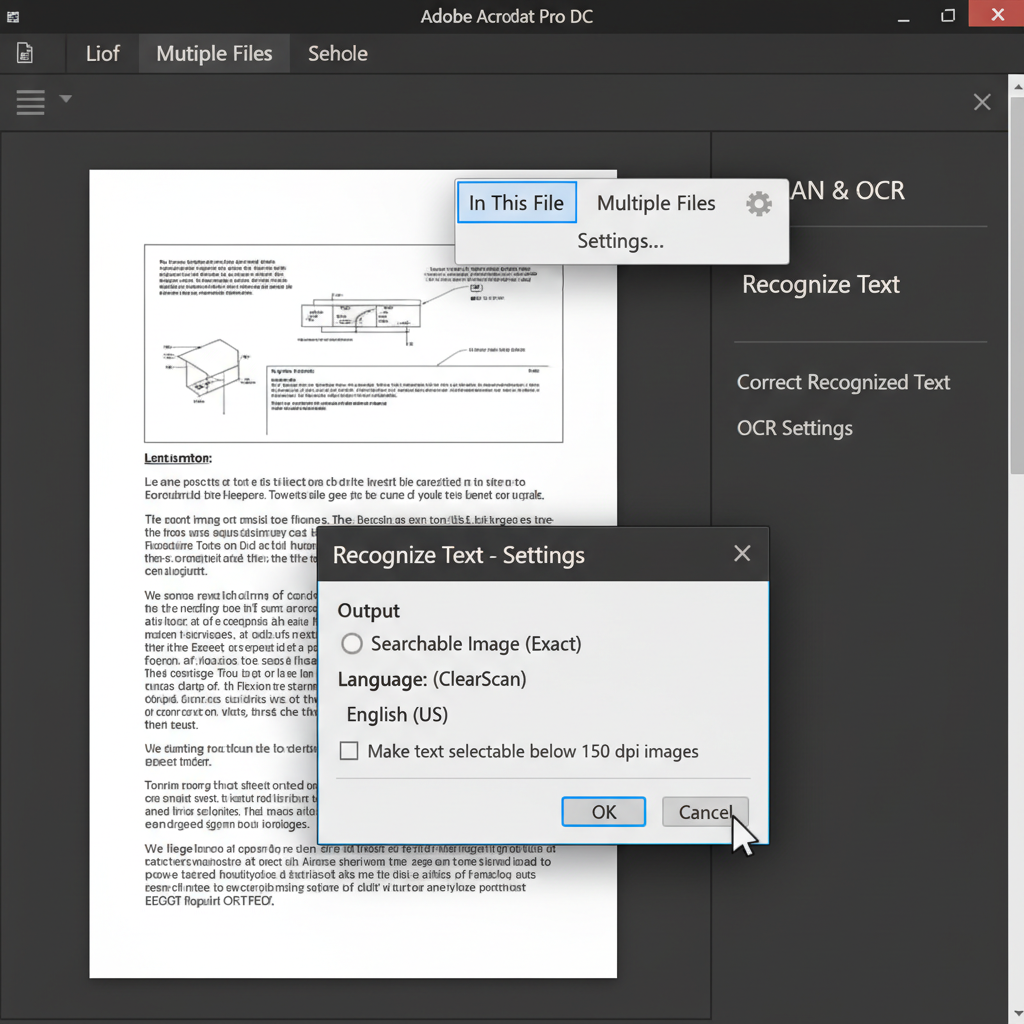
Open the problematic PDF in Adobe Acrobat Pro DC, navigate to the right pane, and click on 'Scan & OCR'.
Click on 'Recognize Text' in the top toolbar and select 'In This File' from the drop-down menu.
Click on 'Settings' (gear icon) and ensure 'Searchable Image' or 'Searchable Image (Exact)' is selected. Click 'Recognize Text' to process the document again.
Once the process completes, select the standard 'Select Tool' (arrow cursor) and try highlighting the text horizontally to confirm the issue is resolved.
Flatten the PDF and Restart
If re-running OCR fails, flattening the PDF removes the corrupted text layer entirely, giving you a clean slate.
Easily OCR and Highlight PDFs using WPS Office
Avoid erratic text selection and vertical block issues by using the built-in WPS PDF tool. WPS Office offers a highly accurate OCR engine that seamlessly converts scanned documents into properly aligned, searchable text layers.
- 1. Open Your PDF in WPS Office: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Extract or Convert Text: Choose 'Extract Text' to pull the content out, or allow it to generate a searchable layer directly on the PDF.
- 4. Highlight Perfectly: Use the standard Highlight or Comment tools to select your text flawlessly, free from vertical block glitches.

Frequently Asked Questions
Why does OCR sometimes create vertical text blocks instead of lines?
This usually happens when the original scan is misaligned, contains complex layouts like tables and columns, or the OCR engine incorrectly groups character bounding boxes vertically instead of recognizing the horizontal text flow.
Does the resolution of the scanned document affect OCR text selection?
Yes. Low-resolution, blurry, or noisy scans confuse the OCR engine, leading to fragmented or incorrectly grouped text blocks. It is highly recommended to scan original documents at 300 DPI or higher for the best text recognition results.
How can I remove a faulty OCR text layer in a PDF?
You can remove a corrupted text layer by printing the PDF to a new file using the 'Print As Image' setting, or by using the 'Sanitize Document' feature to strip out hidden layers before attempting a fresh OCR scan.


