

How to Fix Acrobat Selecting Areas Instead of Text in a PDF

Question details
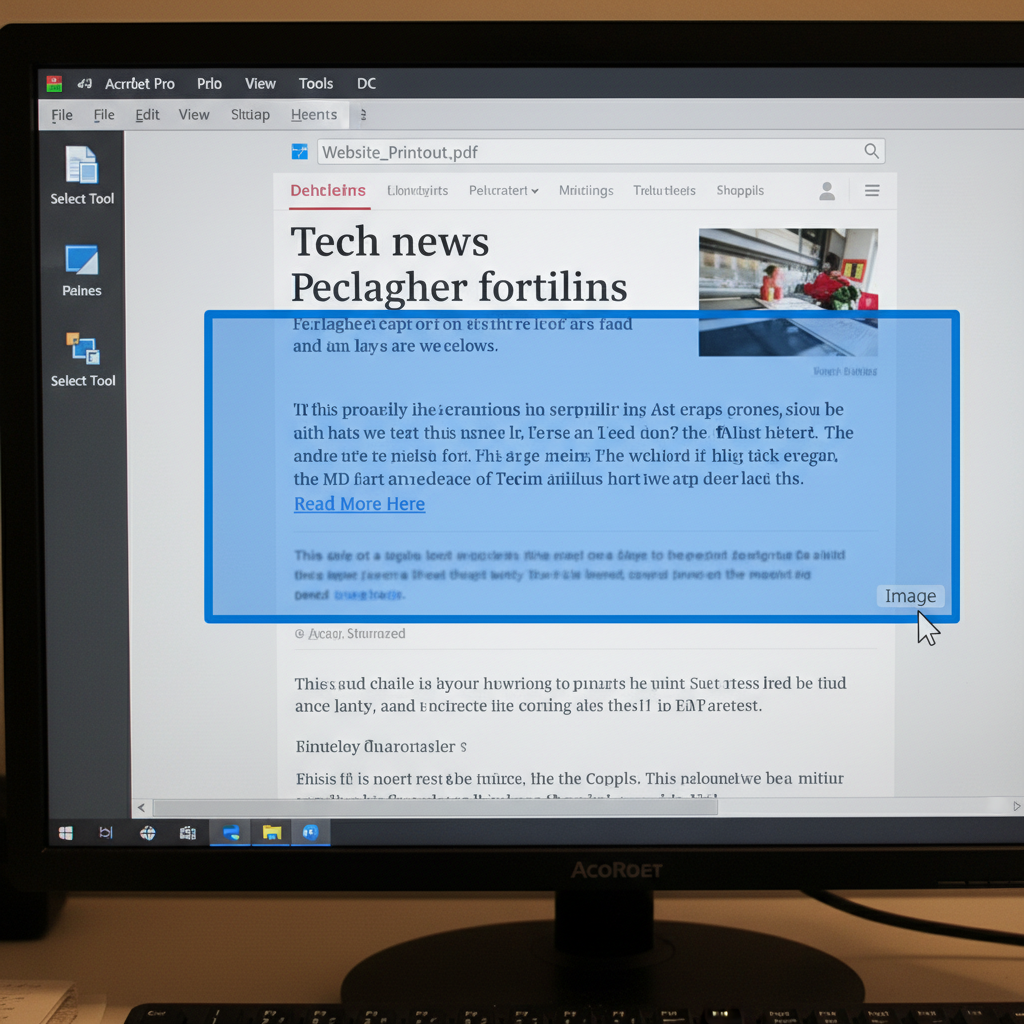
The user is unable to select individual text or copy hyperlinks in a PDF printed from a website; instead, a rectangular block is selected.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Trying to select, copy text, or click hyperlinks in a PDF document generated by printing a webpage.
- Observed behavior
- Acrobat selects a rectangular area as if it is an image instead of recognizing individual words or paragraphs, preventing text and hyperlink copying.
Verify that your PDF document is not secured with permission restrictions that explicitly prevent content copying or editing.
Use the Scan & OCR Tool to Recognize Text
Running Optical Character Recognition (OCR) converts image-based text blocks back into selectable and copyable words.
When a webpage is 'printed' to PDF, the resulting file often saves the visual layout as a flat image or lacks proper text encoding. This prevents standard cursor text selection.
Applying the OCR tool forces the software to identify individual letters and words within that image layer, converting them into interactive text.
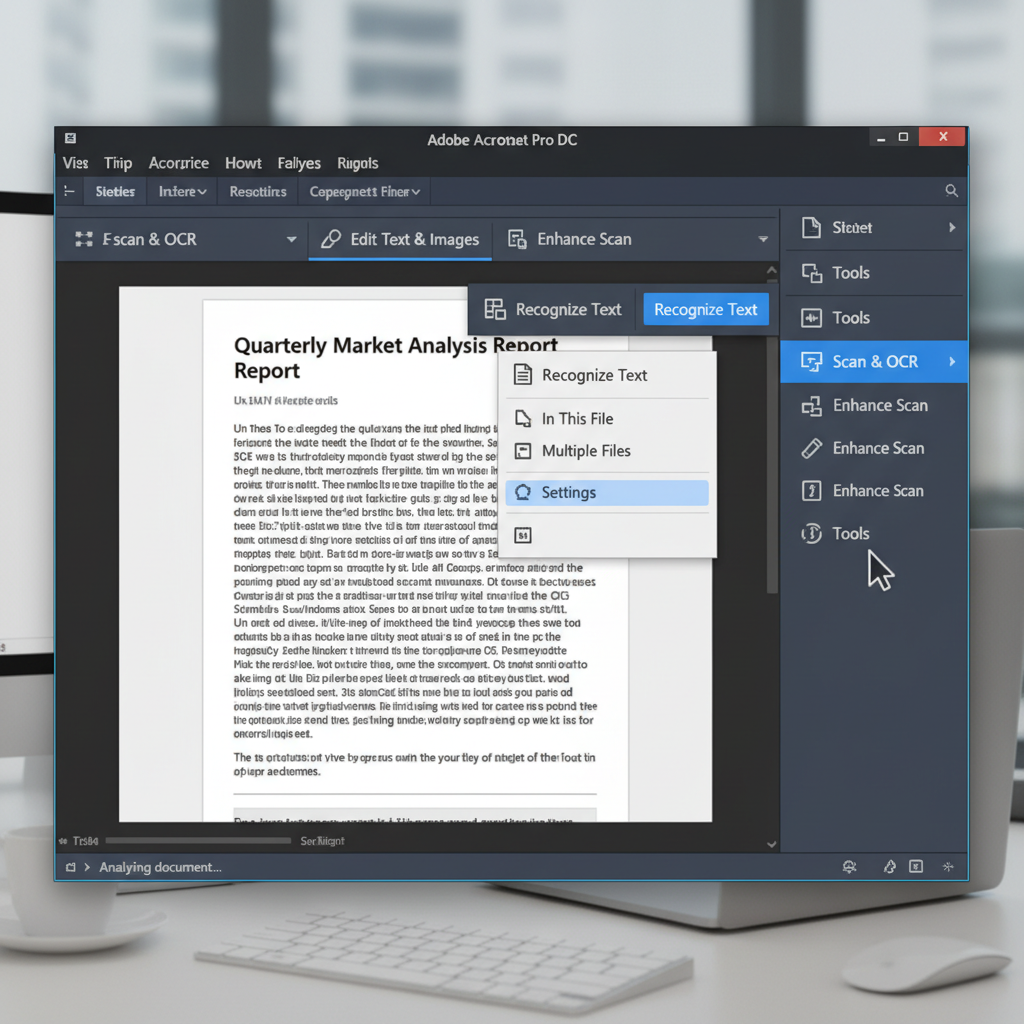
Launch Adobe Acrobat and open the problematic PDF. Go to the 'Tools' menu or the right-hand pane and select 'Scan & OCR'.
Click on 'Recognize Text' in the toolbar and choose 'In This File' from the dropdown menu.
Click the 'Recognize Text' button to start the process. Wait for Acrobat to analyze the document.
Once the OCR process is complete, use the selection tool to highlight individual words and test copying the text.
Extract and Select Text Easily with WPS PDF
WPS Office includes a powerful PDF editor equipped with advanced OCR technology. It can effortlessly convert image-based or printed web PDFs into fully selectable, searchable, and editable text.
- 1. Open the PDF: Launch WPS Office and open your downloaded or printed PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Choose Extraction Method: Select 'Extract text' or 'Convert to Word' depending on whether you just want to copy the content or edit the whole file.
- 4. Process and Select: Wait for the OCR engine to process the image layer. Once finished, you can freely select, copy, and edit the text.

Frequently Asked Questions
Why does my PDF select like an image instead of text?
This happens because the PDF was created as a flattened image, which is common when scanning a document or using 'Print to PDF' from certain web browsers. Because it lacks proper text encoding, the software reads the entire page as a single picture.
How can I make hyperlinks work in a printed PDF?
If a webpage was printed to PDF as an image, the underlying hyperlink data is permanently lost. You must use an OCR tool to recognize the text, or ideally, save the original page using a 'Save as PDF' browser extension that preserves active web links.
Is there a way to edit the text without using OCR?
No. If the text is embedded as a flat image, it cannot be edited or selected directly with a text cursor. You must either perform OCR to convert the image to text or recreate the PDF using a method that retains text encoding.


