

How to Make PDF OCR Recognize Text Line by Line Instead of Columns

Question details
The user wants to configure OCR software to recognize widely spaced text on a single page as continuous horizontal lines rather than splitting it into separate vertical columns.
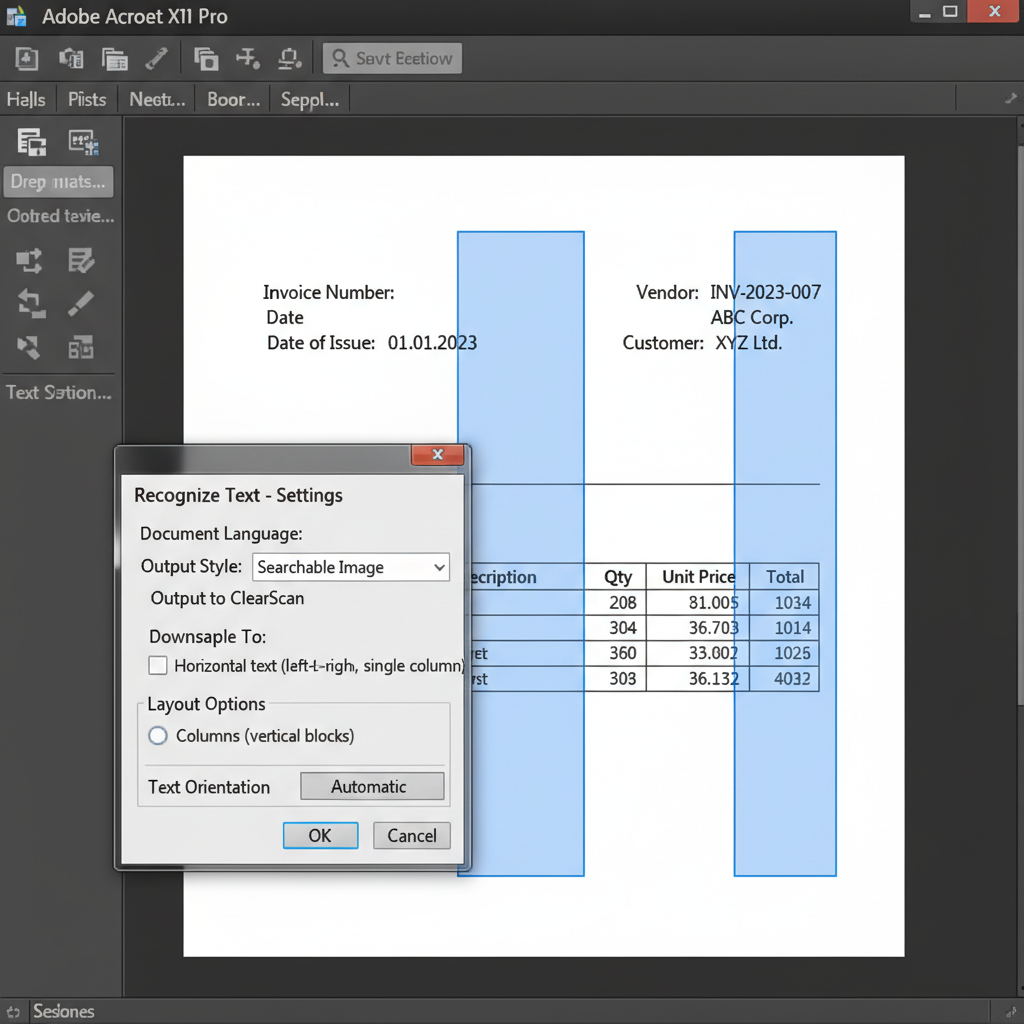
- Product
- Adobe Acrobat XI Pro
- Device & OS
- not provided
- Scenario
- Scanning documents like invoices or forms where text labels (e.g., 'Date of issue:') and their corresponding values (e.g., '01.01.2020') are spaced far apart on the same horizontal line.
- Observed behavior
- The OCR engine interprets the wide blank spaces as column dividers, recognizing the text column-by-column instead of preserving the complete line-by-line structure.
Before troubleshooting OCR text layout issues, ensure your scanned document is saved at a high resolution (at least 300 DPI) and the page is perfectly aligned, as tilted or low-quality scans often cause OCR engines to misinterpret page layouts.
Adjust Scan Quality and Document Layout
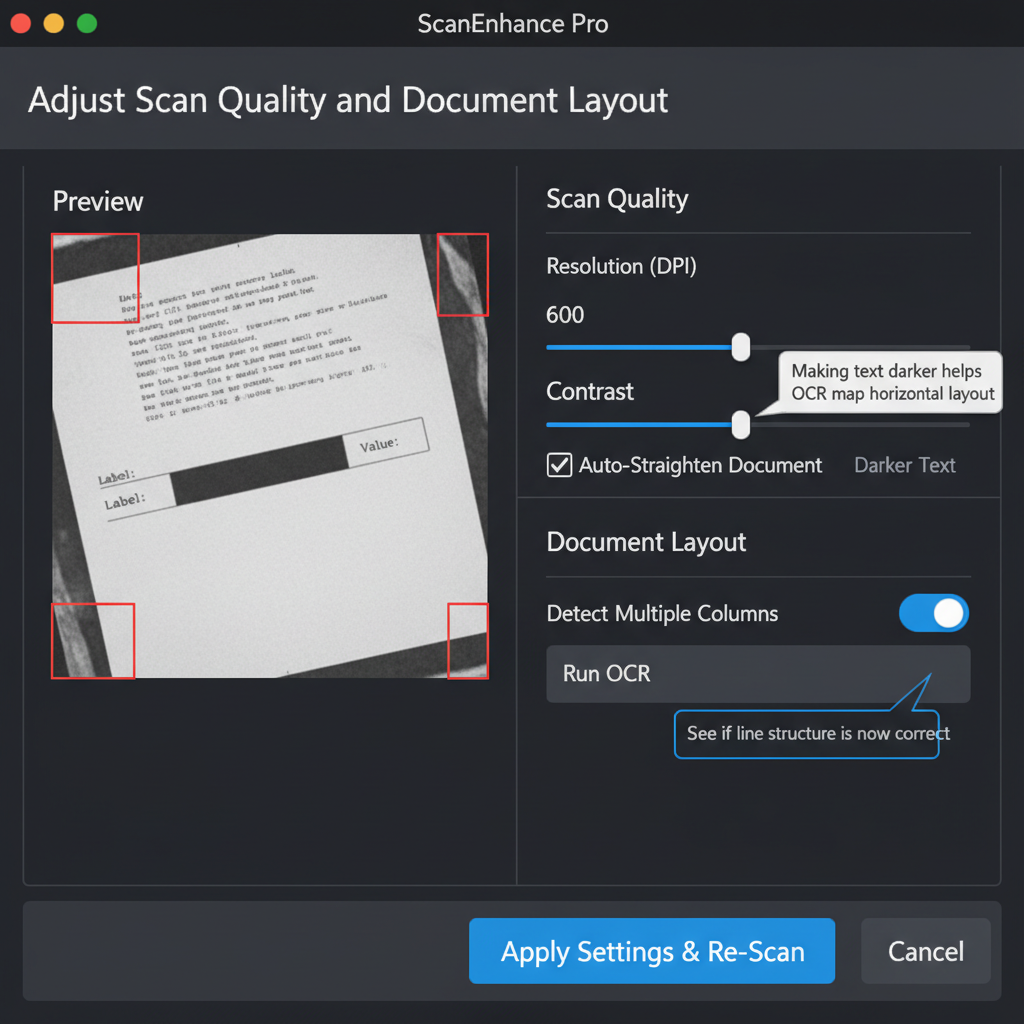
Improve the source document's physical scan quality to help the OCR engine better identify continuous text lines without confusing gaps for column dividers.
Many OCR engines, including Adobe Acrobat, rely heavily on blank space to determine columns. If the gap between a label and its value is too wide, the engine automatically assumes a column break. Improving scan clarity is often the most effective workaround when software settings are limited.
Re-scan the original document using a scanner setting of 300 DPI to 600 DPI to ensure all text characters are crisp and properly defined.
Ensure the physical page is perfectly straight on the scanner bed. Skewed text lines easily confuse OCR software into breaking lines inappropriately.
Use your scanning software to increase the contrast. Making the text darker and the background whiter helps the OCR engine map the horizontal layout more accurately.
Open the newly scanned, high-quality PDF in your OCR software and run the text recognition process to see if the line structure is now correctly preserved.
Manually Correct Text in a Word Processor
Since some OCR tools cannot be forced to ignore large spatial gaps, exporting the recognized text and manually adjusting the formatting is often required.
Extract Text Accurately with WPS Office OCR
If your current PDF software struggles with wide spaces and forces text into columns, WPS Office offers a robust built-in OCR feature. It intelligently recognizes complex document layouts and helps maintain the original line-by-line formatting when converting scanned PDFs into editable Word documents.
- 1. Open the Scanned PDF: Launch WPS Office and open your scanned PDF document containing the widely spaced text.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button, or select 'PDF to Word' if you want to export the entire document.
- 3. Select Layout Settings: In the extraction settings prompt, choose to preserve the original formatting and layout to ensure the engine attempts to keep lines intact.
- 4. Extract and Save: Click 'Start' to begin the OCR process. Once completed, you can edit the text directly or save it as a perfectly formatted Word document.

Frequently Asked Questions
Why does my OCR software read my document in columns instead of continuous lines?
OCR engines analyze the blank space on a page to determine its layout. If the horizontal gap between a label (like a date field) and its corresponding value is unusually wide, the software interprets that empty space as a column divider, splitting what should be one line into two vertical columns.
Can I force Adobe Acrobat to recognize text exactly line by line?
Adobe Acrobat does not currently offer a specific manual setting to force strictly line-by-line recognition when text elements are placed very far apart. You generally have to rely on improving the scan layout, manually correcting the output, or using an alternative OCR tool with different layout parsing logic.
How can I prevent OCR layout errors on scanned invoices and forms?
To minimize layout errors, ensure your invoices are scanned perfectly straight at a high resolution (minimum 300 DPI). Additionally, using specialized data extraction tools designed for invoices can help, as they are specifically trained to link widely spaced key-value pairs.
Does WPS Office include an OCR feature for scanned PDFs?
Yes, WPS Office includes a powerful built-in OCR tool within its PDF editor. It allows you to extract text from scanned images and PDFs, and offers excellent layout retention when converting those files into editable Microsoft Word documents.


