

Fix PDF to Word Conversion Showing Thin Horizontal Lines

Question details
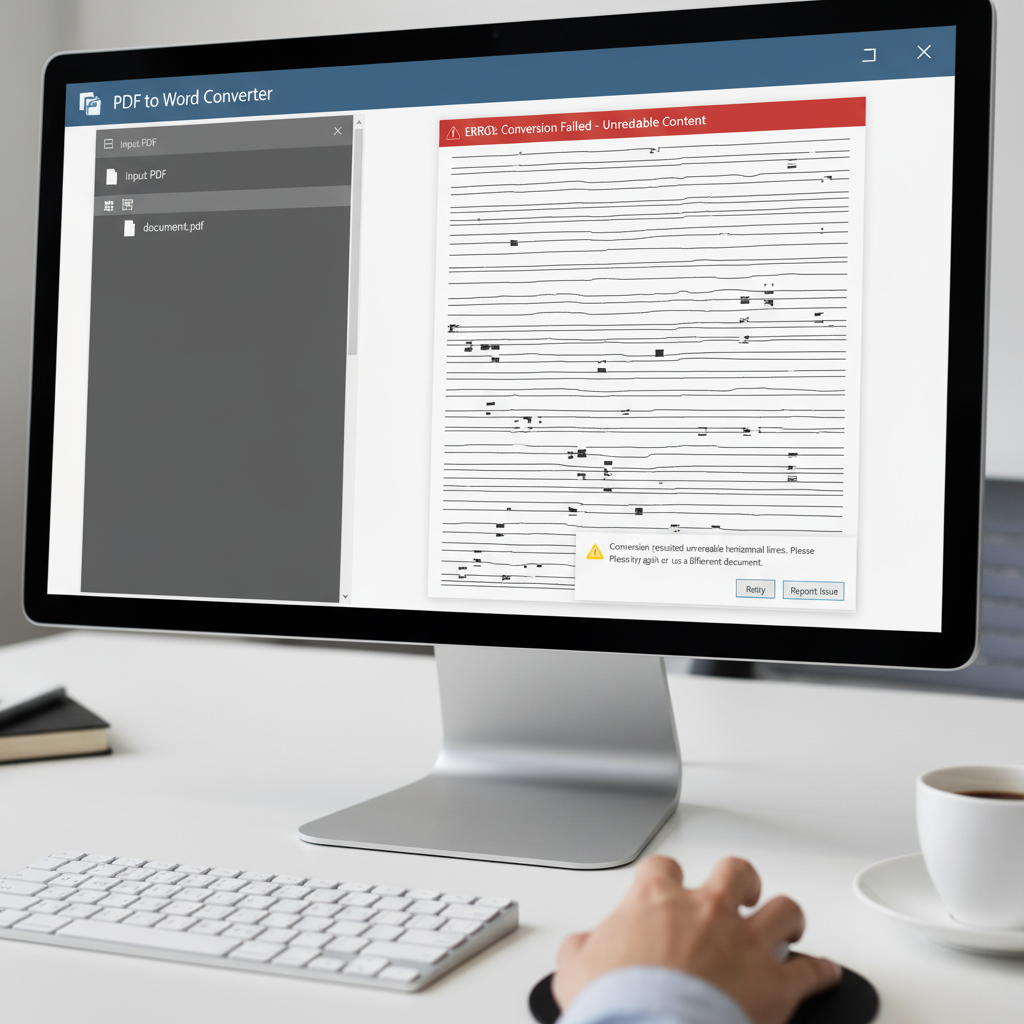
The user needs to resolve an issue where converting a PDF document into a Word file results in unreadable horizontal lines instead of text.
- Product
- PDF to Word Converter
- Device & OS
- not provided
- Scenario
- Attempting to convert a PDF document to an editable Word format.
- Observed behavior
- The resulting Word document displays thin horizontal lines and image artifacts rather than the expected recognizable text.
Verify if the original PDF is a scanned document by trying to select the text with your cursor; if you cannot highlight individual words, the document is an image and requires OCR technology to convert properly.
Use OCR (Optical Character Recognition) to Extract Text
This is the necessary solution when your original PDF is an image or a scanned document, which causes standard converters to fail and output visual artifacts instead of text.
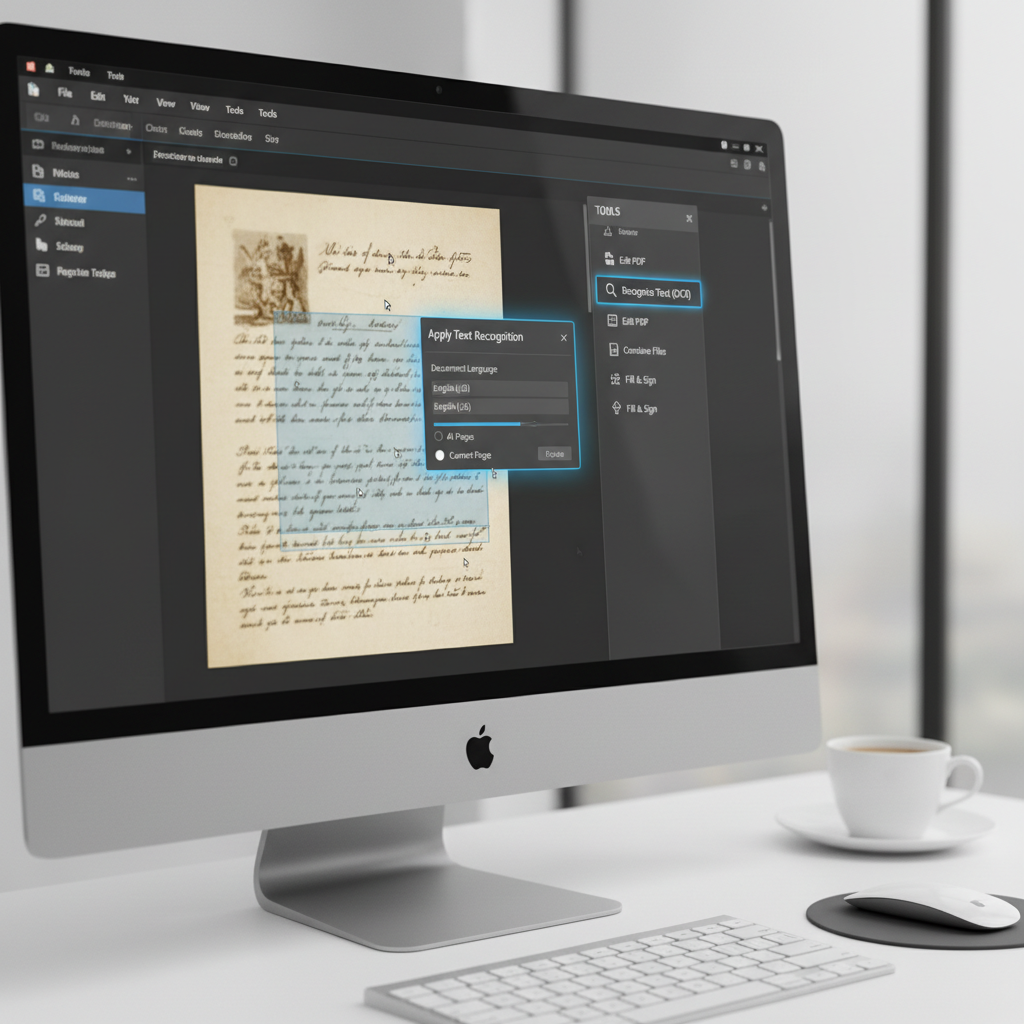
Standard PDF to Word converters attempt to extract embedded text data. When a PDF is created from a scanner, it only contains an image layer without embedded text. Using an OCR-enabled converter forces the software to 'read' the image and generate editable characters.
Launch your advanced PDF editing software and open the problematic scanned PDF file.
Navigate to the 'Tools' or 'Edit' tab and select the 'OCR' or 'Recognize Text' option.
Choose the primary language of your document in the settings menu and run the OCR process to extract readable text from the scanned image layer.
Once the text has been recognized and is selectable, click on 'Convert to Word' to export the document into an editable .docx format.
Convert Image-Based PDFs to Word Effortlessly with WPS Office
WPS Office features a powerful built-in OCR engine that accurately recognizes text in scanned PDFs, preventing issues like thin lines or missing characters during Word conversion.
- 1. Open Your PDF in WPS Office: Launch WPS Office and open the scanned PDF file that you wish to convert.
- 2. Select PDF to Word: Navigate to the 'Tools' tab on the top ribbon and click the 'PDF to Word' option.
- 3. Enable OCR Conversion: In the conversion dialog box, ensure the OCR (Optical Character Recognition) option is toggled on to extract text.
- 4. Start Conversion: Click 'Start' to process the file; the newly created and editable Word document will open automatically.

Frequently Asked Questions
How do I know if my PDF requires OCR for conversion?
Open the PDF in any standard viewer and try to highlight a specific word or sentence. If the entire page highlights as a single block or if you cannot select text at all, the PDF is a scanned image and requires OCR.
Why do some fonts turn into weird symbols or lines when converting?
This occurs when the original PDF was created with non-standard or custom embedded fonts that the converter cannot map to your system's fonts. Using an OCR tool or 'Print to PDF' to flatten the file before conversion can bypass this issue.
Can I fix the horizontal lines in Word after the conversion is done?
No, the horizontal lines indicate that the text was not correctly parsed during the conversion process and is now just image data. You will need to reconvert the original PDF using an OCR-enabled tool to properly extract the text.


