

How to Fix OCR Failing When Converting a Scanned PDF to Word

Question details
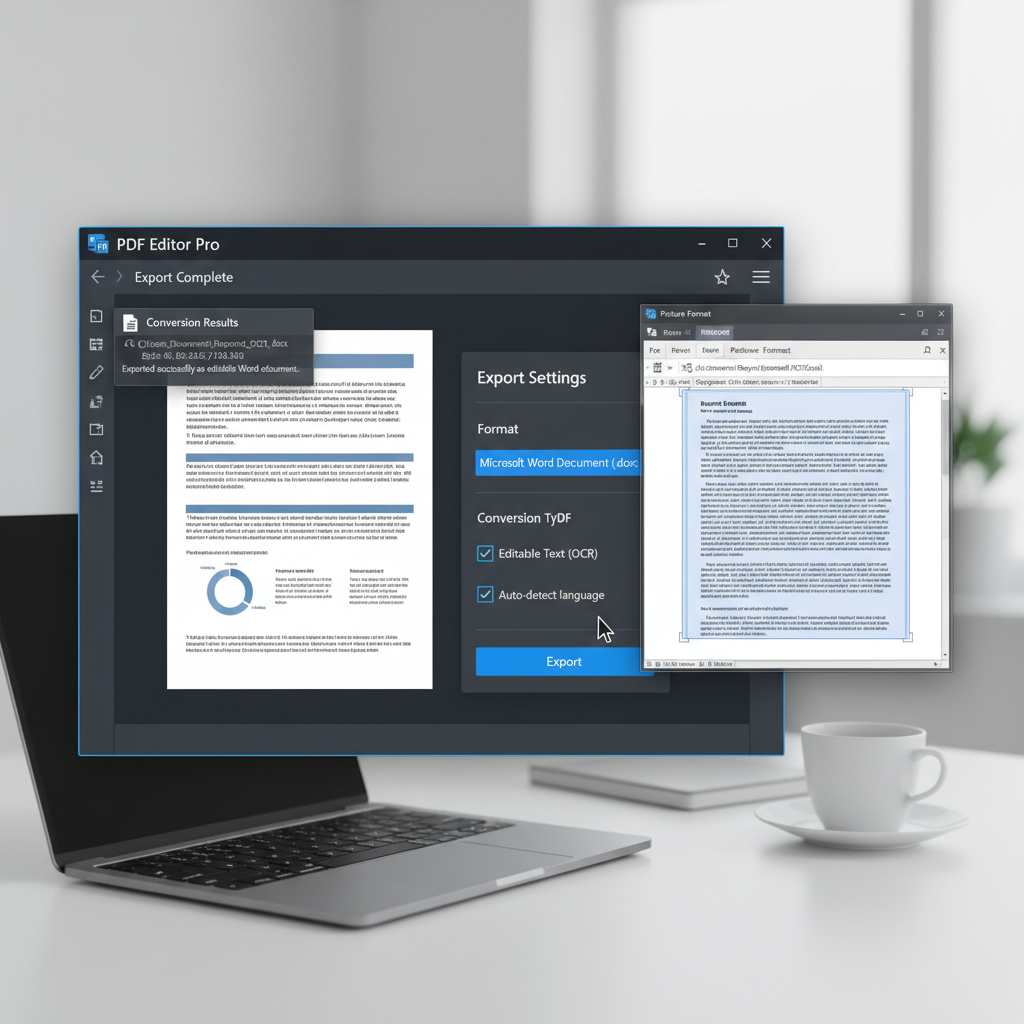
The user needs to resolve an issue where exporting a scanned PDF to a Word document using OCR results in an uneditable image instead of selectable text.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Converting a scanned PDF file to an editable Microsoft Word document with the OCR (Optical Character Recognition) feature enabled.
- Observed behavior
- The conversion completes, but the resulting Word file contains only a flat image without selectable text, even though OCR was turned on and works for other documents.
Verify that your original scanned PDF is clear, readable, and does not have security restrictions preventing text extraction or content copying.
Verify Permissions and Use Advanced Selection Methods
Check if the PDF security settings allow text extraction and try specific text selection techniques in the converted file.
Sometimes the OCR process actually succeeds, but the resulting text is placed within heavily structured text boxes that mimic the original layout, making standard text selection difficult.
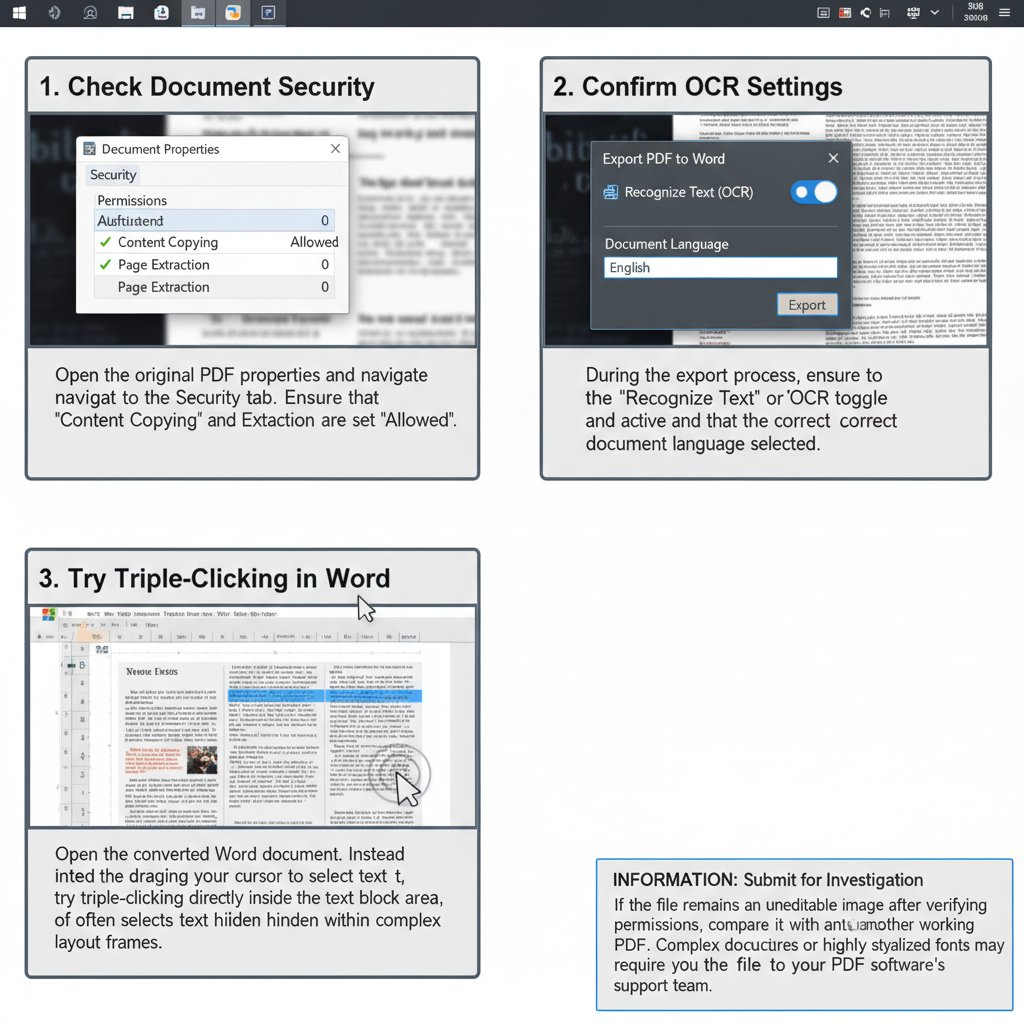
Open the original PDF properties and navigate to the Security tab. Ensure that 'Content Copying' and 'Page Extraction' are set to 'Allowed'.
During the export process, ensure the 'Recognize Text' or 'OCR' toggle is active and that the correct document language is selected.
Open the converted Word document. Instead of dragging your cursor to select text, try triple-clicking directly inside the text block area. This often selects the text hidden within complex layout frames.
Enhance the Scanned PDF Quality Before Conversion
Low-resolution scans or skewed pages can prevent the OCR engine from recognizing text, resulting in an image-only output.
Convert Scanned PDFs to Editable Word Documents Using WPS Office
WPS Office features a powerful, highly accurate built-in OCR engine that easily extracts text from scanned PDFs and images, converting them into fully editable Word documents without losing the original layout.
- 1. Open PDF to Word: Launch WPS Office, navigate to the 'PDF' tab, and click on the 'PDF to Word' tool.
- 2. Add Your Scanned PDF: Drag and drop your scanned PDF file into the conversion window.
- 3. Enable OCR: In the conversion settings prompt, make sure the 'OCR' option is selected to extract text from the scanned images.
- 4. Convert and Edit: Click 'Convert'. Once finished, the editable Word document will open automatically in WPS Office.

Frequently Asked Questions
Why does my converted Word document only show an image?
This happens when the OCR engine fails to process the text. Common reasons include low image resolution, incorrect language settings, highly stylized fonts, or PDF security restrictions preventing text extraction.
How can I improve OCR accuracy for scanned PDFs?
Ensure your original scan is captured at a minimum of 300 DPI. Improving the contrast between the text and background, and ensuring the pages are straight (not skewed) will significantly help the OCR engine read the document.
Can OCR extract text from a password-protected PDF?
If the PDF has a permissions password that restricts content copying or page extraction, the OCR tool cannot read the text. You must unlock these permissions with the appropriate password before converting.
Does the document language affect OCR conversion?
Yes. OCR engines use language dictionaries to predict and recognize characters. If the wrong language is selected in your OCR settings, the software may fail to convert the scan into text and output an image instead.


