

How to Fix Adobe Acrobat Crashing or Taking Too Long During OCR

Question details
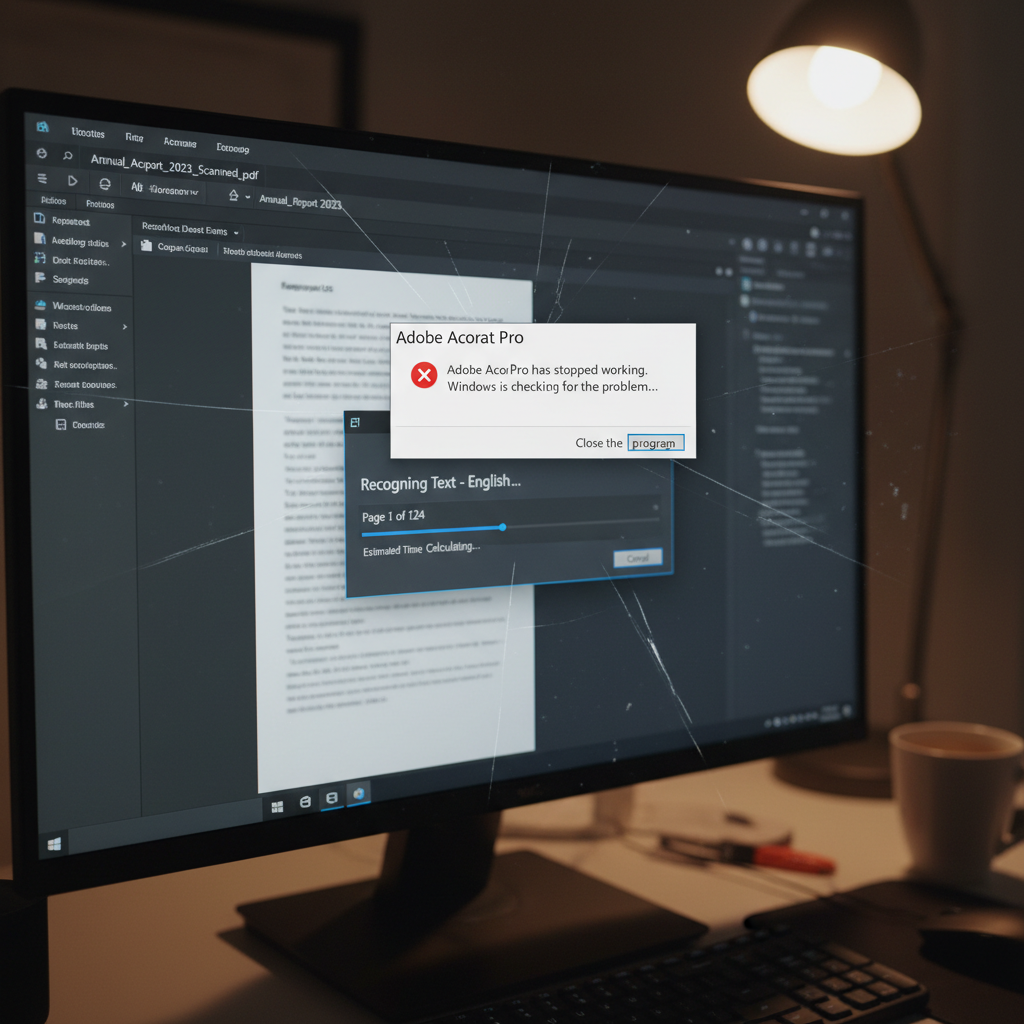
Adobe Acrobat crashes unexpectedly or takes an excessive amount of time (over 10 seconds per page) when performing OCR on scanned documents across multiple computers.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running Optical Character Recognition (OCR) on scanned PDF documents to make them editable or searchable.
- Observed behavior
- The application crashes completely without displaying any error message, and the text recognition processing time is unusually slow.
Before troubleshooting, ensure you have saved a backup copy of your original scanned PDF documents and verify that your system has sufficient available RAM to handle image processing tasks.
Update and Repair Acrobat Installation
Fix software corruption or outdated bugs by installing the latest updates and running the built-in repair tool.
Software bugs or corrupted installation files frequently cause random crashes during resource-intensive tasks like OCR. Updating and repairing the software restores essential components.
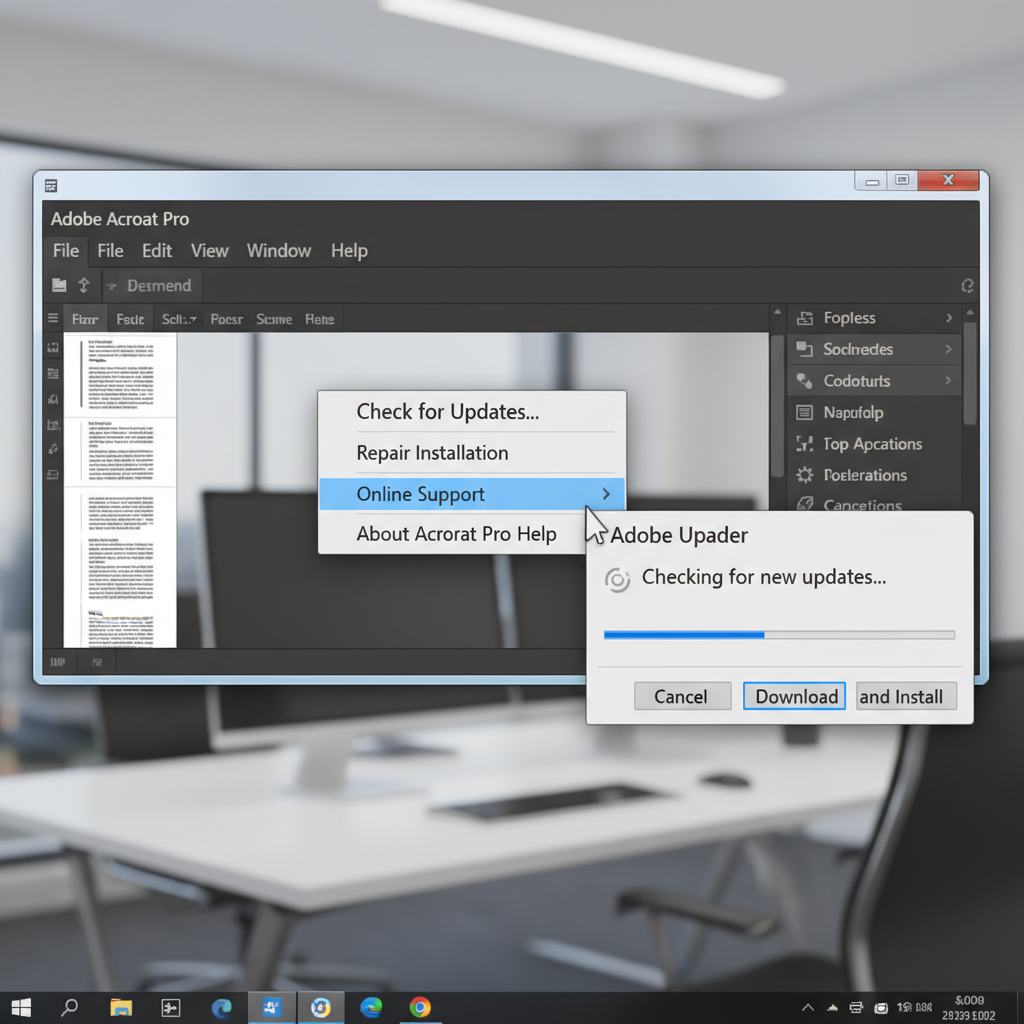
Open Adobe Acrobat, click on the 'Help' menu at the top, and select 'Check for Updates'. Follow the on-screen prompts to download and install available patches.
Navigate to the 'Help' menu again and click on 'Repair Installation'. Wait for the progress bar to complete as it fixes missing or corrupted program files.
Once the updates and repairs are finished, restart your computer to ensure all background services and registry changes are fully applied.
Clear Temporary Files and Disable Plug-ins
Improve processing speed and stability by removing bloated temporary files and preventing third-party plugins from interfering with the OCR engine.
Optimize Source Scans and Local Network Resources
Ensure the issue isn't caused by network lag, insufficient memory, or overly complex source images.
Use WPS Office for Reliable PDF OCR Processing
If your current PDF software keeps freezing or crashing during text recognition, switch to WPS Office. The built-in WPS PDF tool offers a lightweight, highly accurate OCR engine that quickly extracts text from scanned documents without bogging down your computer.
- 1. Open PDF in WPS: Launch WPS Office and open your scanned PDF document using the WPS PDF interface.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to launch the text recognition panel.
- 3. Choose Output Options: Select your desired output format (such as exporting to a Word document or making the PDF searchable) and confirm the document language.
- 4. Start Recognition: Click 'Start' to begin processing. The text will be extracted quickly and accurately without application crashes.

Frequently Asked Questions
Why is Adobe Acrobat taking so long to recognize text on my PDF?
Slow OCR processing usually occurs when the source PDF has a very high resolution (over 600 DPI), the file is being accessed over a slow network connection, or your computer lacks the available RAM needed to process complex images efficiently.
Does clearing temporary files really prevent OCR crashes?
Yes. When your system's temporary folder becomes full or contains corrupted cached files from previous crashed sessions, it can prevent PDF software from allocating the memory needed for OCR, leading to immediate application failure.
Can third-party plugins interfere with PDF text recognition?
Absolutely. Certain third-party workflow or security plug-ins actively monitor file modifications. This can conflict with the internal text recognition engine during processing, resulting in unexpected crashes or infinite loading loops.


