

How to Fix Adobe Acrobat OCR Memory Errors on Large PDFs

Question details
Users are encountering a memory error and service failure when attempting to run OCR on large vector PDF files.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running Optical Character Recognition (OCR) on exceptionally large vector PDF files.
- Observed behavior
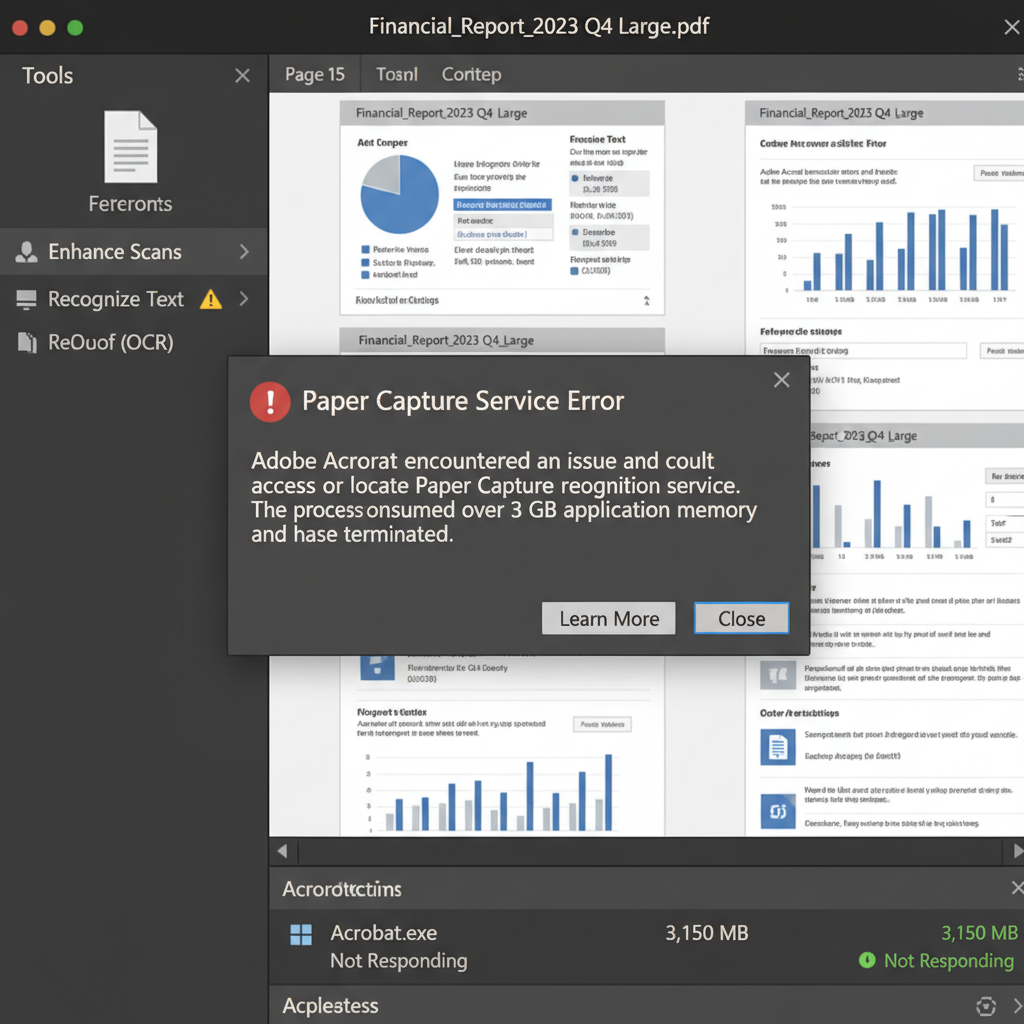
- Acrobat consumes over 3 GB of memory during the OCR process and displays an error stating it could not access or locate the Paper Capture recognition service.
Before troubleshooting, open your system's task manager to monitor current memory usage and close unnecessary background applications to free up system RAM for the OCR process.
Split the Large PDF into Smaller Sections
Dividing the large vector PDF into smaller files reduces the memory load required for the OCR engine, bypassing the 3 GB limitation that triggers the service crash.
The Paper Capture recognition service has a known memory threshold. When a complex vector document pushes Acrobat's memory footprint above 3 GB, the OCR service fails to process the pages.
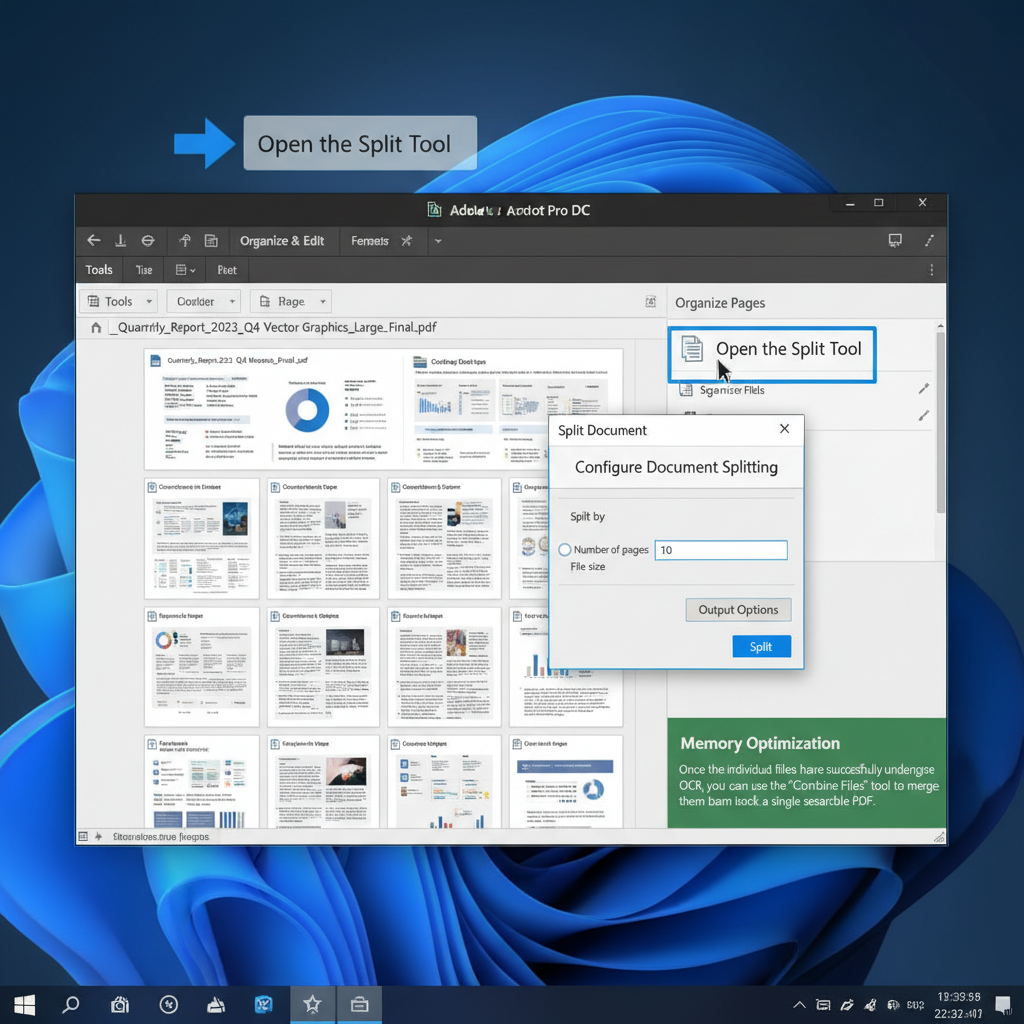
Open your large PDF in Adobe Acrobat, navigate to the 'Tools' menu, and select 'Organize Pages'.
Click the 'Split' button on the top toolbar. Choose to split the document by 'Number of pages' or 'File size' to ensure each section remains small.
Click 'Output Options' to choose a destination folder, then click 'Split'. Open each newly created smaller PDF file and run the 'Recognize Text' (OCR) tool individually.
Repair the Adobe Acrobat Installation
Running a built-in software repair can fix corrupted components of the Paper Capture recognition service that may be contributing to the failure.
Easily Perform OCR on Large PDFs with WPS Office
Avoid memory limitations and complex troubleshooting by using WPS Office's built-in PDF tools. WPS PDF offers a highly efficient OCR feature that quickly converts scanned documents and large vector PDFs into editable text with minimal system resource consumption.
- 1. Open Your PDF in WPS: Launch WPS Office and open your large or complex PDF document in the WPS PDF editor.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Select Output Options: Choose whether you want to extract the text to a plain document or convert the entire PDF into an editable Word document.
- 4. Extract the Text: Select the correct document language to ensure accuracy, then click 'Extract' or 'Convert' to finish the process.

Frequently Asked Questions
What causes the 'unable to locate the Paper Capture recognition service' error in Acrobat?
This error generally occurs when Acrobat processes highly complex or large vector PDFs, causing the application to exceed its 3 GB memory limit. When the memory threshold is breached, the background OCR service crashes and becomes unreachable.
Can I fix the Acrobat OCR memory error without splitting the document?
Sometimes running a repair on the Acrobat installation or updating the software to the latest patch can resolve minor service glitches. However, for exceptionally large vector files, splitting the document is the most reliable and official workaround.
Does WPS PDF support OCR for scanned documents and large files?
Yes, WPS PDF includes a dedicated, lightweight OCR feature designed to easily extract text from scanned images and large PDF documents without consuming excessive system memory.


