

How to Fix Cannot Select or Copy Text in Adobe Acrobat (Blue Frames)

Question details
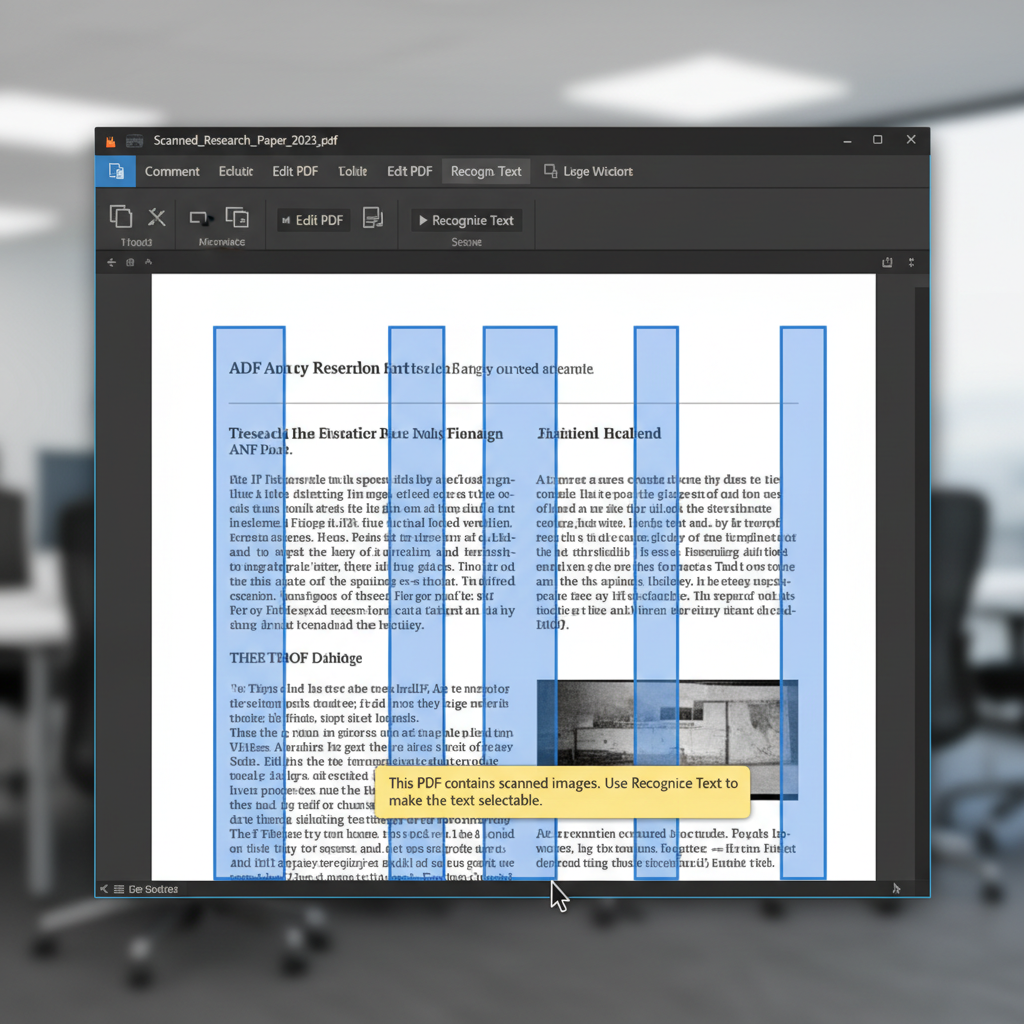
The user is unable to select, copy, or paste text within a PDF document, and blue vertical frames appear when trying to interact with the content.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to select, highlight, or copy specific text segments from a scanned PDF document.
- Observed behavior
- Text selection fails entirely, and the software displays blue vertical frames, indicating that the PDF is composed of flat images rather than digital text layers.
Verify that your PDF is not restricted by security permissions that block copying, though the presence of blue frames almost always indicates you are dealing with a scanned, image-based PDF.
Run Text Recognition (OCR) in Acrobat
Use the built-in OCR feature to scan the image-based PDF and convert its contents into selectable and copyable digital text.
When a document is scanned, it is often saved as a single flat image. Even though it looks like text, the PDF reader only sees a picture, which is why clicking on it selects the whole image block (showing a blue frame). Running Optical Character Recognition (OCR) analyzes the image and overlays an invisible layer of real text.
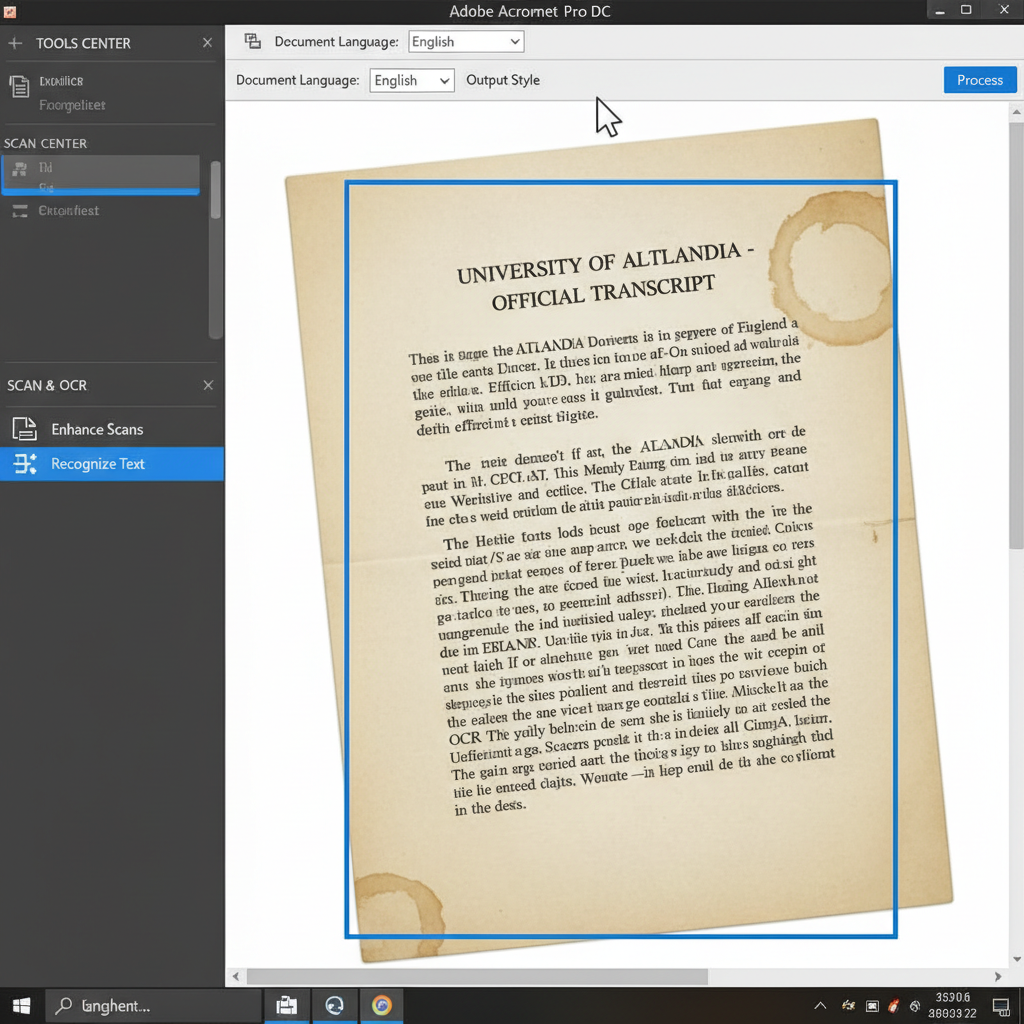
Open your scanned PDF in Adobe Acrobat. Navigate to the 'Tools' menu and select either 'Scan & OCR' or 'Recognize Text', depending on your specific version.
In the OCR settings toolbar, verify and select the correct language that matches the text in your document to ensure optimal recognition accuracy.
Click the button to process the document. Acrobat will analyze the images and generate digital text layers.
Once the text recognition process finishes, choose the standard selection cursor tool. You should now be able to highlight, select, and copy the text normally.
Extract Text from Scanned PDFs Easily with WPS Office
WPS Office offers a powerful, built-in PDF reader and editor featuring advanced OCR technology. You can quickly and accurately convert flat, scanned image PDFs into selectable, editable, and copyable text formats without needing heavy or expensive software.
- 1. Open the PDF: Launch WPS Office and open your scanned image-based PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on 'OCR' (or 'Picture to Text').
- 3. Set Conversion Preferences: Choose whether to extract text from the current page or the entire document, and select the corresponding document language.
- 4. Extract and Copy: Click 'Extract'. WPS Office will process the image, allowing you to instantly select, copy, or export the recognized text into a new Word document.

Frequently Asked Questions
Why do blue frames appear when I try to select text in a PDF?
Blue frames indicate that you are clicking on an image block rather than text. This happens because the PDF page was saved as a flat image (like a photograph of a document) without digital text layers, so the software selects the entire picture.
Does running OCR change the layout of my original PDF?
No, standard OCR typically adds an invisible layer of recognized text over the original scanned image. This allows you to highlight and copy words while preserving the exact visual appearance of the original scan.
Why is the copied text full of spelling mistakes after OCR?
OCR relies heavily on the visual clarity of the original file. If the scanned document is blurry, has low resolution, features low contrast, or contains complex handwriting, the OCR engine may misinterpret certain letters and produce errors.


