

How to Fix Copied PDF Text Appearing as Symbols Instead of Letters

Question details
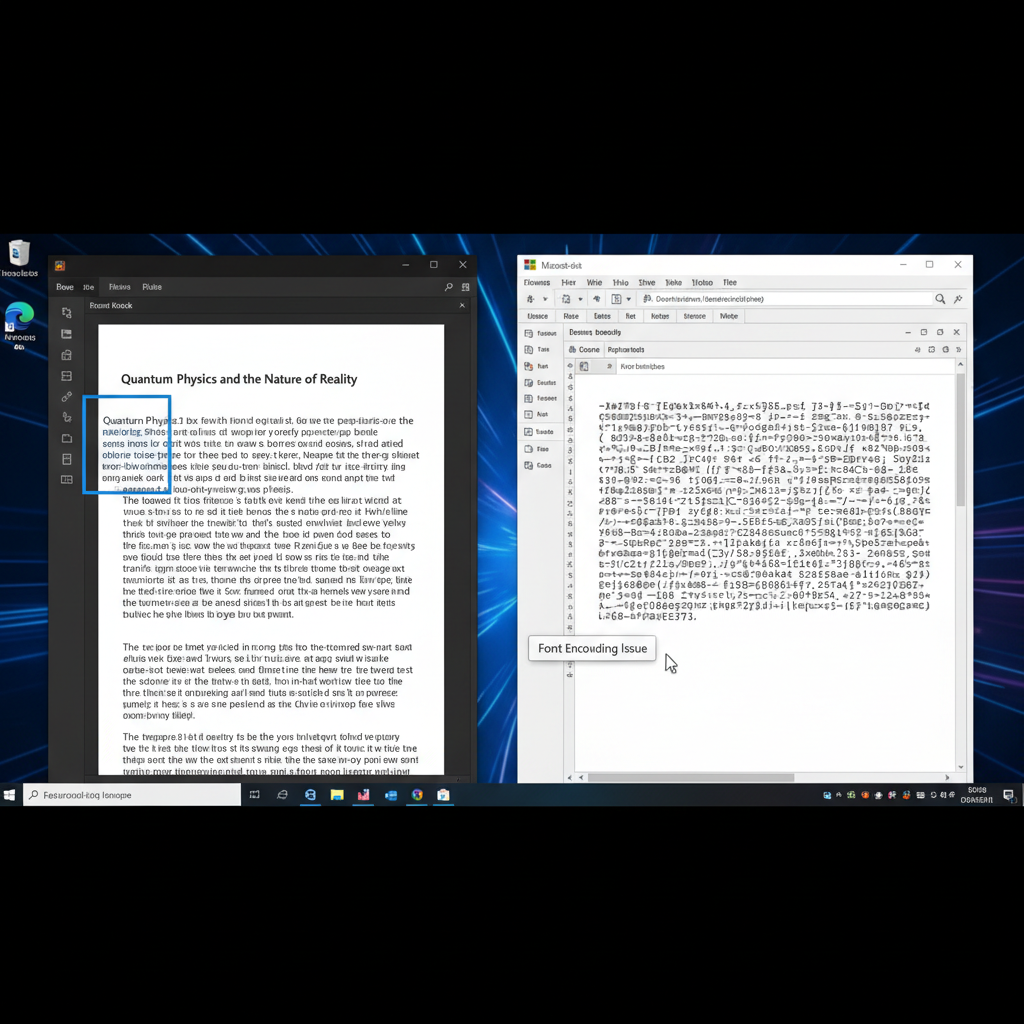
The user is experiencing an issue where text copied from a PDF document turns into unreadable symbols or gibberish when pasted into another application.
- Product
- Device & OS
- not provided
- Scenario
- Copying text from a PDF document and pasting it into a word processor like Microsoft Word.
- Observed behavior
- The pasted text appears as different, weird symbols instead of the expected English letters. This typically indicates missing character mappings, incorrect font encoding, or a PDF exported with unusual, non-embedded fonts.
Before attempting advanced troubleshooting, try copying text from a different PDF file to confirm whether the issue is isolated to a single document or affects your PDF reader as a whole.
Use OCR (Optical Character Recognition) to Extract Text
When a PDF lacks proper underlying character mapping, OCR software can bypass the broken encoding by visually reading the letters and converting them into fully editable text.
If the PDF's internal font data is corrupted, your computer cannot translate the shapes on the screen into standard letters. OCR treats the document like an image, accurately recognizing the visual text and outputting correct Unicode characters.
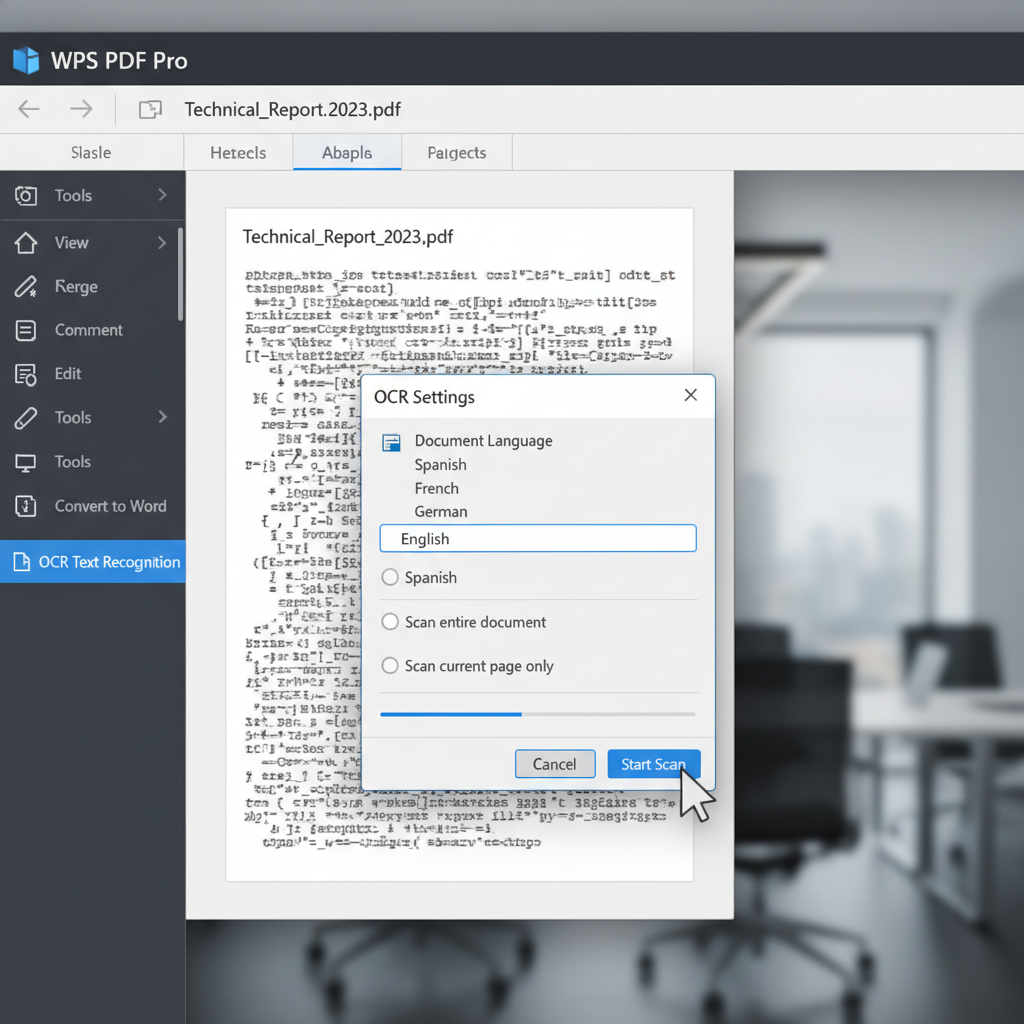
Launch a PDF editor that features Optical Character Recognition, such as WPS PDF or Adobe Acrobat, and open the problematic file.
Navigate to the 'Tools' or 'Edit' tab and click on the 'OCR' or 'Recognize Text' option.
Select the primary language of the document to ensure high accuracy, then start the scanning process.
Once the document is converted, highlight the newly generated text, copy it, and paste it into Microsoft Word. It should now appear as normal letters.
Request a Newly Exported PDF with Embedded Fonts
Since this error is usually caused during the initial creation of the PDF, re-exporting the file with the correct settings is the most permanent fix.
Print to PDF to Flatten the Document
Re-printing the problematic file as a new PDF can sometimes restructure the metadata and flatten the document, allowing subsequent OCR processes to work flawlessly.
Extract PDF Text Effortlessly with WPS Office's OCR
WPS Office features an advanced, built-in PDF toolset equipped with high-accuracy Optical Character Recognition (OCR). This allows you to easily bypass broken font encoding issues and accurately extract perfectly readable text from any problematic PDF directly into an editable document.
- 1. Install WPS Office: Download and install WPS Office, then open your problematic PDF file using the WPS PDF viewer.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on 'OCR'.
- 3. Extract the Text: Select 'Extract Text' to pull the characters from the page, or choose 'Convert to Word' if you want to export the entire document.
- 4. Copy and Paste: Highlight the recognized text, copy it, and paste it into your desired application without any gibberish symbols.

Frequently Asked Questions
Why does copied PDF text paste as weird symbols?
This happens when the original PDF was created without proper Unicode character mapping or utilized custom, non-standard fonts that were not fully embedded. The text looks correct to the human eye, but the computer reads the underlying, broken metadata and translates it into random symbols when you try to paste it.
Can I fix the font encoding of a PDF I didn't create?
You cannot easily fix the internal font encoding of an existing PDF file without the source document. However, you can effectively bypass this issue by using OCR (Optical Character Recognition) software to read the visual text and create a newly encoded, editable version.
Does pasting as 'Plain Text' fix the symbol issue?
No. Pasting as plain text removes visual formatting (like bolding or font size), but because the underlying character data is what's actually corrupted in the PDF, plain text pasting will still output the same unreadable symbols.


