

How to Fix PDF Chinese and Japanese Text Copying as Strange Symbols on Mac

Question details
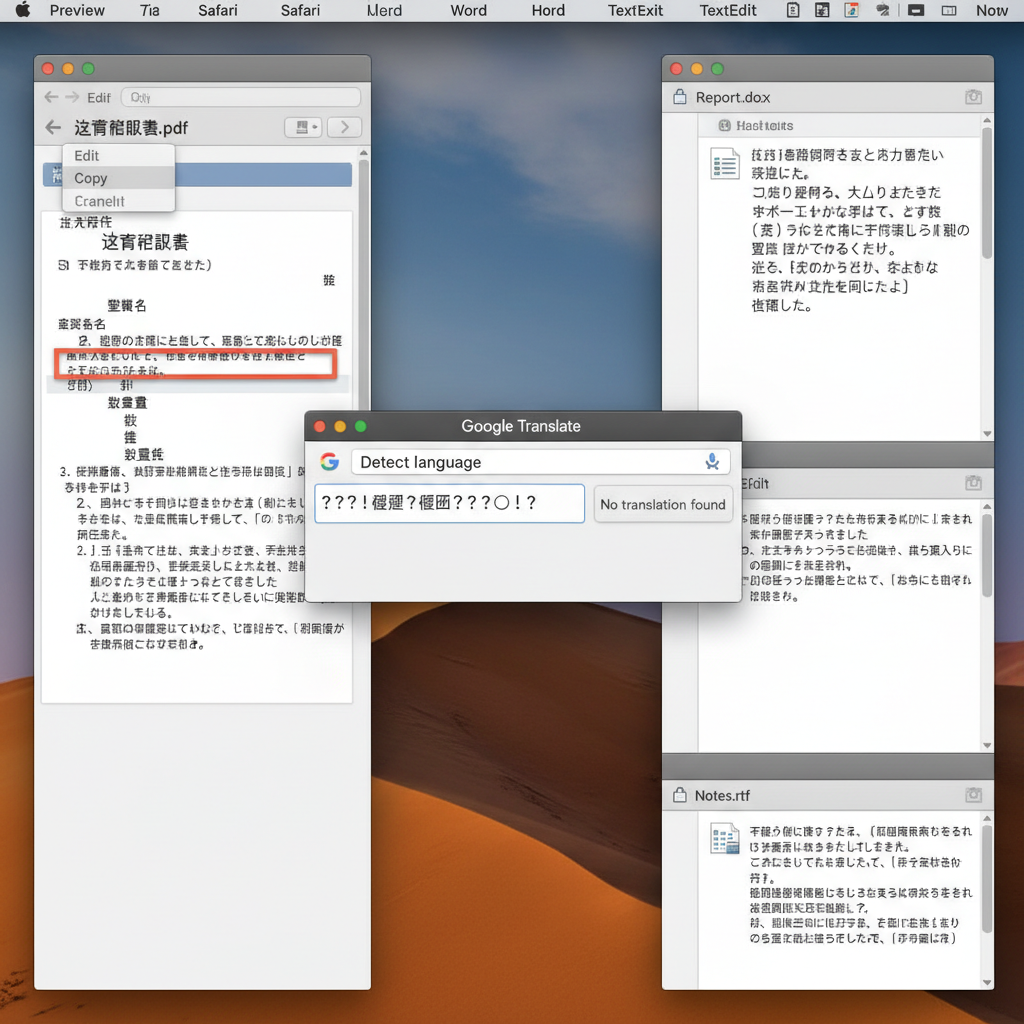
The user is experiencing an issue where copying Chinese or Japanese text from a PDF results in gibberish or strange symbols when pasted.
- Product
- Device & OS
- macOS Mojave
- Scenario
- Copying text from email-based PDFs into applications like Google Translate, Word, or TextEdit.
- Observed behavior
- The pasted text appears as strange symbols instead of the original Chinese or Japanese characters, regardless of the paste method used.
Determine if the issue occurs with all PDFs or just this specific document, as the problem is almost always caused by missing embedded fonts or incorrect character mapping within the source file itself.
Extract Text Using OCR with Asian Language Settings
Bypass the corrupted font encoding by using Optical Character Recognition (OCR) to visually read and extract the Chinese or Japanese text.
When a PDF uses custom embedded fonts or has incorrect character mapping, the system does not know what Unicode characters to output to your clipboard. OCR solves this by reading the visual shapes of the characters on the page instead of relying on the underlying broken code.
Open the problematic PDF in a PDF editor that supports OCR, such as Adobe Acrobat or WPS PDF.
Navigate to the 'Tools' menu and select 'Recognize Text' or 'OCR'.
In the OCR settings, ensure the recognition language is explicitly set to Chinese (Simplified/Traditional) or Japanese. This is crucial for accurate Asian character detection.
Start the OCR process. Once completed, select the newly recognized text, copy it, and paste it into your desired application. It should now paste as standard readable text.
Recreate the PDF or Request the Original Source
If you have access to the original email or document, re-exporting the PDF with correct font embedding can resolve the issue permanently.
Use WPS Office to OCR and Extract Chinese or Japanese Text
WPS PDF includes a powerful built-in OCR engine that supports multiple languages, including Chinese and Japanese. It can easily convert PDFs with broken font encoding into selectable, editable text without requiring expensive third-party software.
- 1. Open the PDF in WPS Office: Launch WPS Office on your Mac and open the PDF file containing the uncopyable text.
- 2. Activate the OCR tool: Go to the 'Tools' tab on the top ribbon and click on the 'OCR' or 'Picture to Text' button.
- 3. Select the target language: Choose Chinese or Japanese from the language dropdown menu to ensure accurate character recognition.
- 4. Extract and Copy: Run the OCR process. You can then copy the correctly recognized text and paste it into Word, TextEdit, or your browser without getting strange symbols.

Frequently Asked Questions
Why does copied PDF text paste as gibberish or squares?
This happens when the PDF is created without a proper unicode mapping (ToUnicode table) or uses custom subset fonts. The PDF viewer knows how to draw the graphical shapes on the screen, but it does not know which actual text characters they correspond to when you try to copy them.
Can I fix the font encoding in the existing PDF directly?
Fixing the underlying encoding of an existing PDF is generally very difficult without advanced, professional PDF editing software. The most effective workarounds are either using OCR to read the text visually or re-exporting the original source file to PDF properly.
Does Apple's Preview app have an OCR feature for Asian languages?
macOS offers Live Text in newer versions (macOS Monterey and later) which can recognize text in images directly in Preview. However, for older systems like macOS Mojave, you will need dedicated third-party software with an OCR engine, such as WPS PDF, to extract Chinese or Japanese characters from a corrupted PDF.
Why do 'Paste without formatting' methods fail to fix this?
Methods like 'Paste without formatting' only strip out styling such as bold, italics, or font size. They cannot fix the source text if the underlying characters copied to your clipboard are already scrambled symbols due to the PDF's broken encoding.


