

How to Fix Junk Characters Created by OCR in Acrobat Pro 2017

Question details
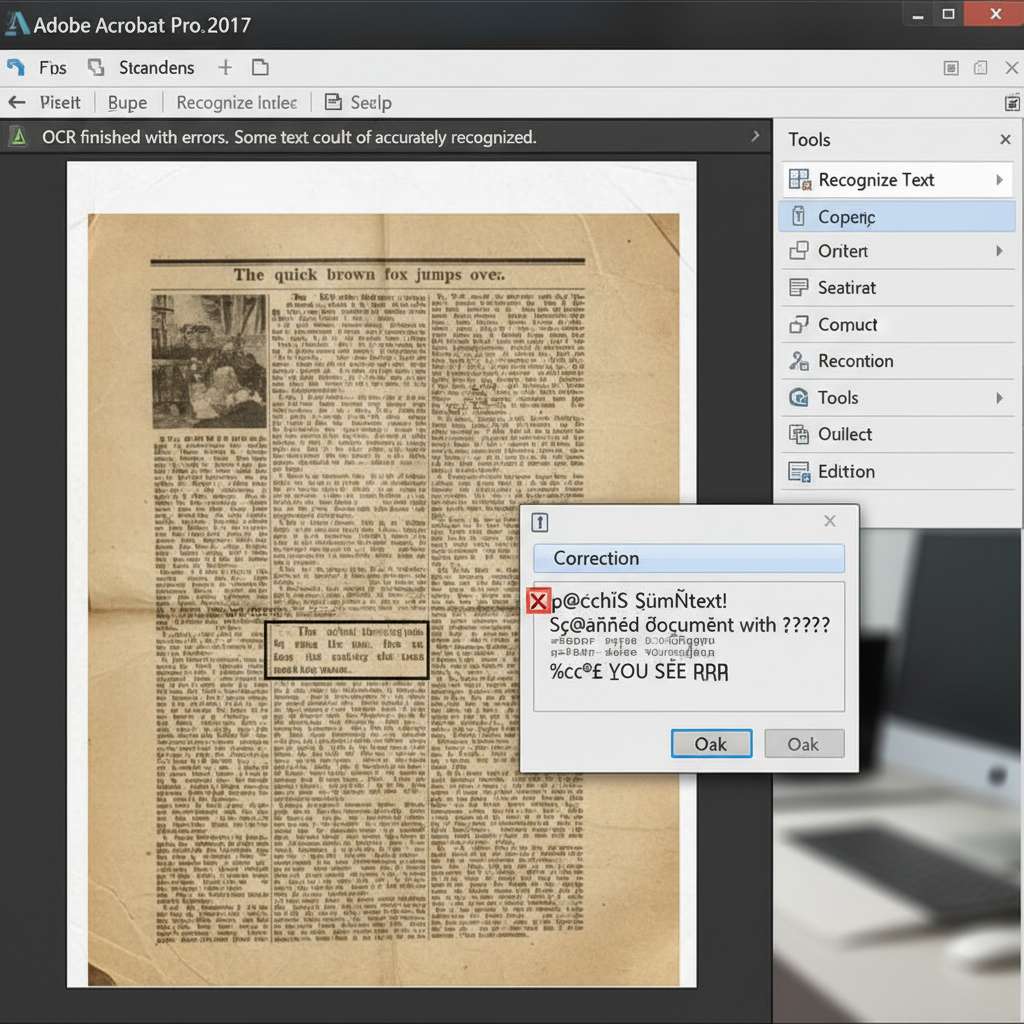
The user needs to resolve an issue where the OCR function generates incorrect or unusual characters when processing documents.
- Product
- Adobe Acrobat Pro 2017
- Device & OS
- not provided
- Scenario
- Running OCR on scanned documents with degraded quality, unusual fonts, or complex layouts like newspapers.
- Observed behavior
- The OCR process outputs junk, gibberish, or incorrect text characters instead of accurately recognizing the original text.
Ensure your scanned document is as clear as possible, as OCR accuracy heavily depends on the contrast, alignment, and resolution of the original image.
Adjust OCR Language Settings and Improve Scan Quality
Configuring the correct OCR language and optimizing the initial scan can significantly reduce junk character generation.
Acrobat Pro 2017 relies on specific language models. If the document contains complex layouts or degraded text, setting the precise language and enhancing the image beforehand is crucial.
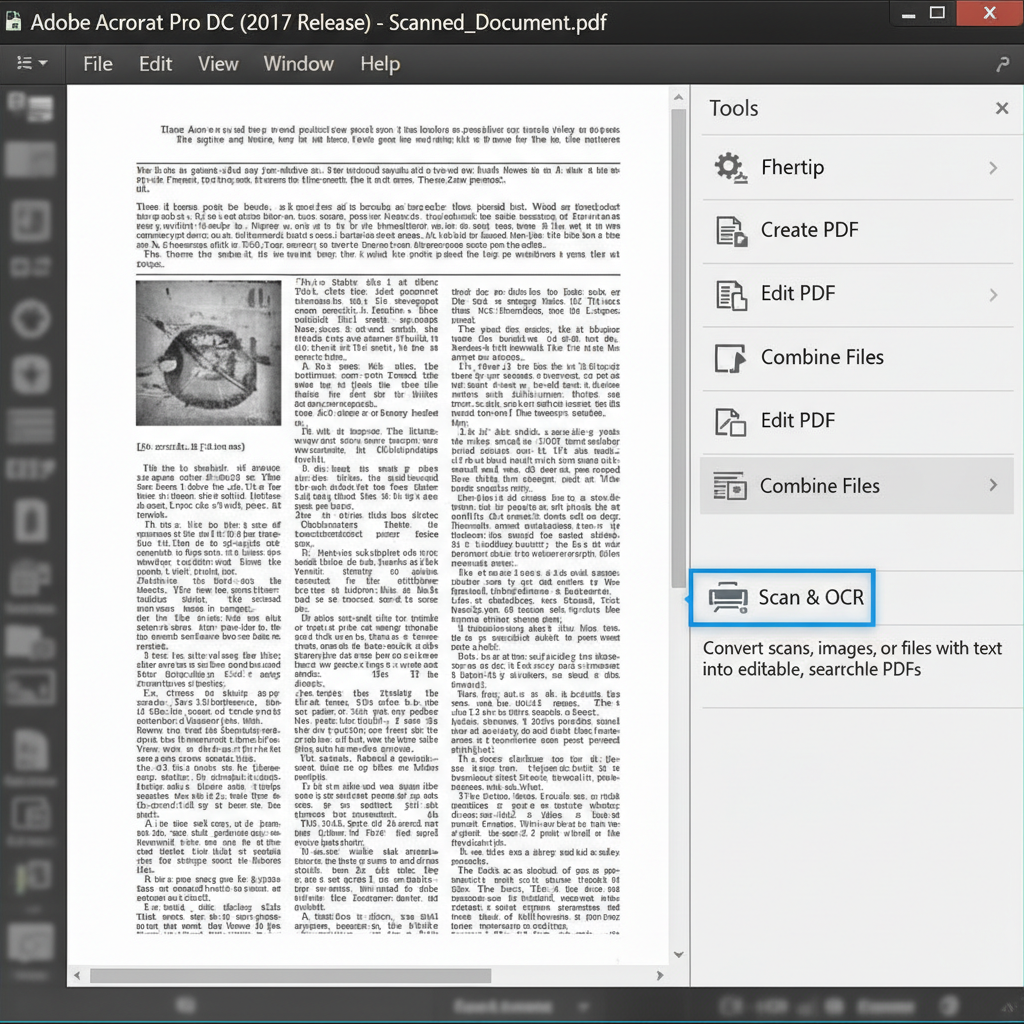
Open the scanned PDF in Adobe Acrobat Pro 2017. Go to the 'Tools' pane and select 'Scan & OCR'.
Click on 'Enhance' and select 'Scanned Document'. Use this tool to deskew pages, remove background noise, and adjust image contrast.
Click on 'Recognize Text' and choose 'In This File'. Click 'Settings' and ensure the 'Document Language' exactly matches the language of your text (e.g., English).
Click 'Recognize Text' to process the document again. Check if the junk characters have been resolved.
Bypass Renderable Text Errors by Recreating the PDF
If you encounter errors about renderable text overlapping with junk characters, recreating a flattened PDF can help the OCR engine read the document cleanly.
Extract Text Accurately Using WPS Office's Built-in OCR
WPS Office provides an advanced, highly accurate OCR feature within its PDF tool, allowing you to seamlessly convert scanned documents and images into editable text without the junk character issues found in older software.
- 1. Open PDF in WPS: Download and launch WPS Office, then open your scanned PDF file in the WPS PDF viewer.
- 2. Access OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' (Picture to Text) button.
- 3. Configure Output Options: Choose your desired output format (such as Extract Text or Convert to Word) and select the correct document language.
- 4. Recognize Text: Click 'Confirm' to initiate the OCR process and obtain highly accurate, editable text.

Frequently Asked Questions
Why does OCR produce junk or gibberish characters?
OCR relies on recognizing visual patterns in an image. If the original document has low resolution, unusual fonts, fading text, or complex layouts (like newspapers), the OCR engine may misinterpret the shapes, resulting in junk or incorrect characters.
Can updating my PDF software improve OCR accuracy?
Yes. Newer versions of PDF software generally include updated OCR language models and improved machine learning algorithms that handle degraded scans and complex fonts much better than older versions like Acrobat Pro 2017.
What is the best resolution for scanning documents for OCR?
For optimal OCR accuracy, it is highly recommended to scan text documents at 300 DPI (dots per inch). Scanning below this can result in pixelated text, while excessively high resolutions create massive file sizes without significantly improving accuracy.
How do I fix the 'renderable text' error when running OCR?
The 'renderable text' error occurs when a PDF already contains hidden text layers or vector objects. You can usually bypass this by flattening the PDF—such as by printing it to a new PDF file using a virtual printer—and then running the OCR process on the newly generated document.


