

How to Fix PDF Pages Turning Blank After OCR in Adobe Acrobat

Question details
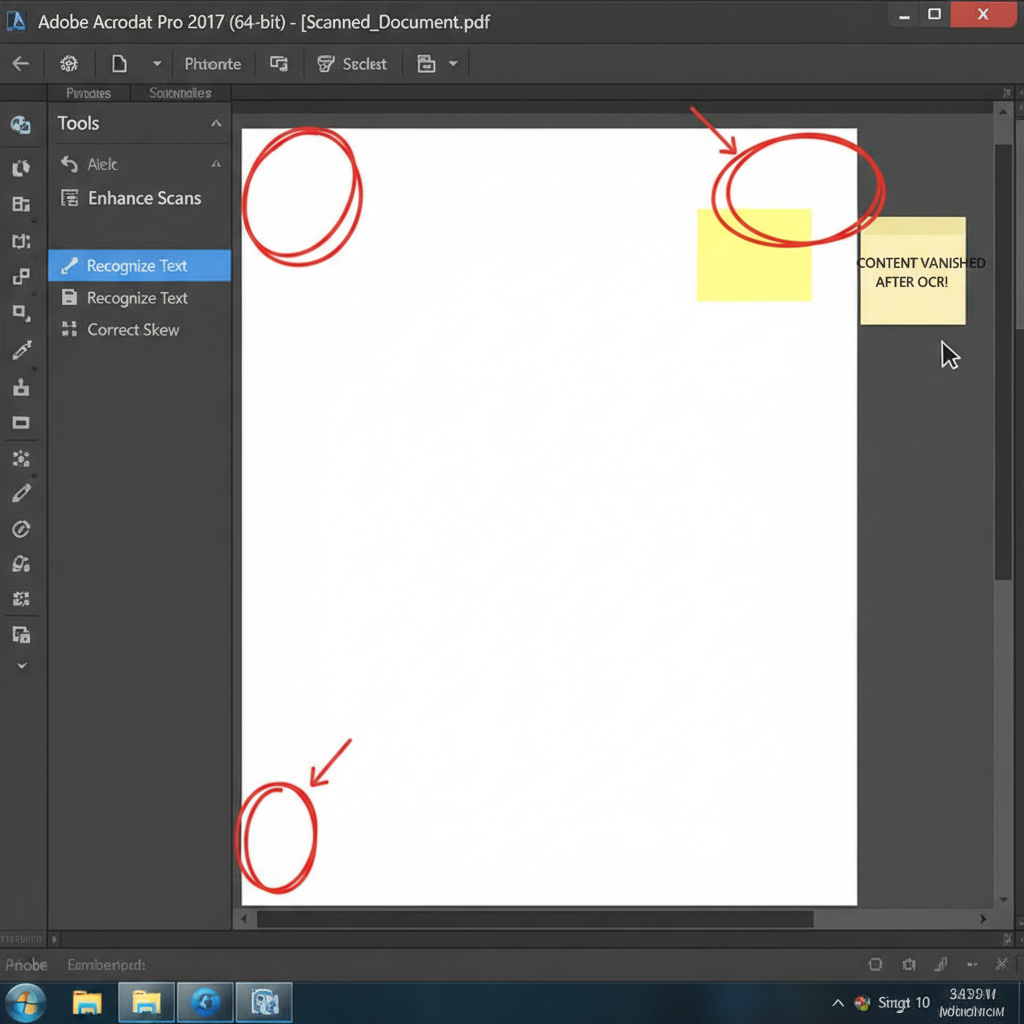
The user needs to resolve an issue where document pages become completely blank after applying the text recognition (OCR) tool.
- Product
- Adobe Acrobat Pro 2017
- Device & OS
- Windows 10
- Scenario
- Applying text recognition (OCR) to a scanned PDF document to make the text searchable and editable.
- Observed behavior
- The page content disappears and turns entirely blank immediately after OCR processing, although existing markups and annotations remain visible.
Always create a backup copy of your original scanned PDF document before running text recognition or repairing software installations to prevent accidental data loss.
Install the Latest Software Patch and Repair Installation
Applying the latest bug fixes and repairing corrupted software files is the most effective way to resolve PDF rendering issues during OCR.
Software bugs in specific versions of Acrobat 2017 are known to cause rendering failures when processing OCR. Installing the 17.11.30197 patch or newer typically resolves this.
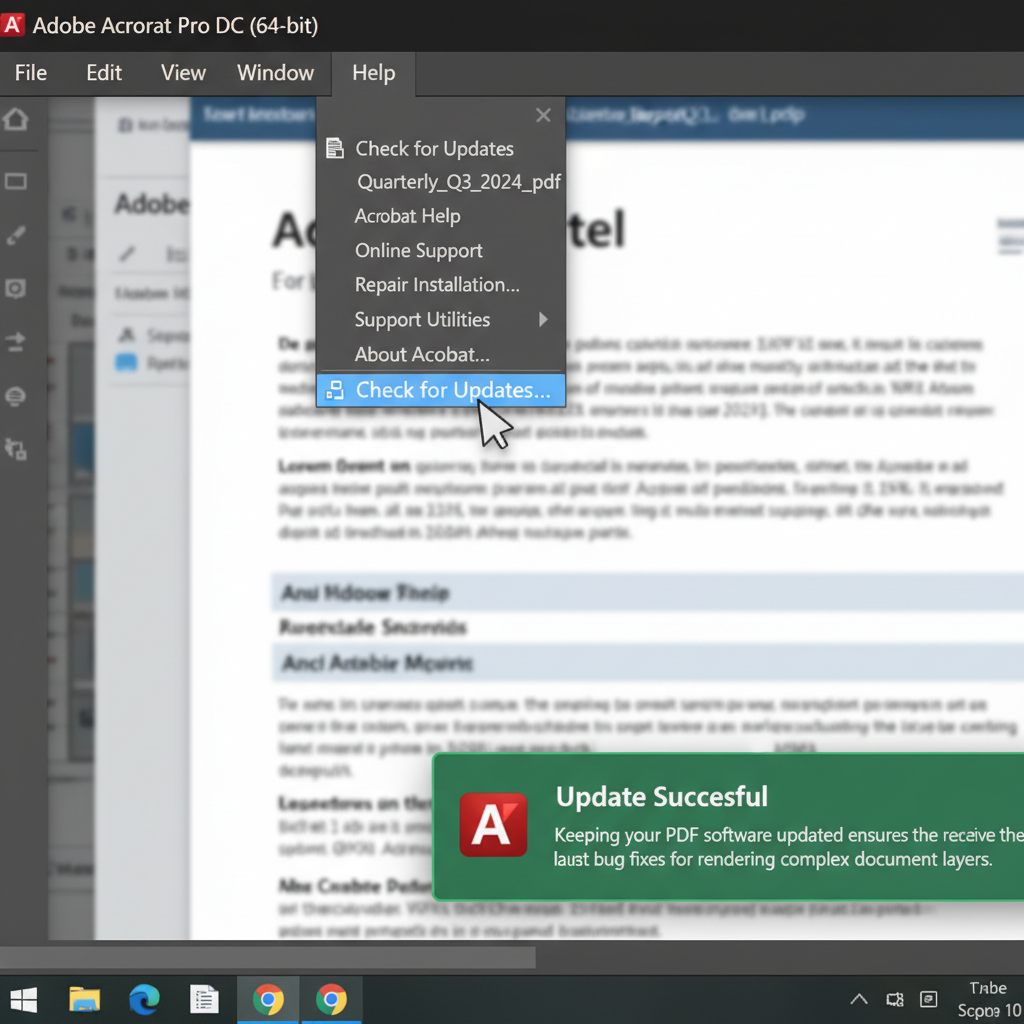
Open Adobe Acrobat, click on the 'Help' menu at the top, and select 'Check for Updates' to download and install the latest available patch.
Once the update is successfully installed, restart your Windows 10 computer to ensure the system registry and program files are fully updated.
If the issue persists after updating, reopen Acrobat, go to the 'Help' menu, and select 'Repair Installation' to fix any corrupted underlying files.
Reset Application Preferences to Default
Corrupted preference configurations can sometimes cause unexpected behaviors, such as blank pages, during heavy processing tasks like text recognition.
Isolate Document-Specific OCR Issues
Testing a different file helps determine whether the blank page error is caused by a corrupted PDF file rather than a software malfunction.
Use WPS PDF to Extract Text Flawlessly
Avoid blank page bugs and rendering errors by using the highly accurate OCR feature in WPS PDF. It seamlessly recognizes and extracts text from your scanned documents while preserving the original layout.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document in the WPS PDF reader.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select OCR settings: Choose your desired output format, such as 'Extract text' or 'Convert to Word', and select the document's language.
- 4. Process the document: Click 'Start' to begin text recognition. The processed document will display the editable text instantly without altering the visibility of your original pages.

Frequently Asked Questions
Why do PDF pages go blank after running OCR?
This usually happens due to a rendering bug in the PDF software, an outdated application version, or corrupted underlying image layers within the specific scanned document that crash the display engine upon processing.
Does OCR delete my original PDF images?
No, standard OCR processes analyze the image and overlay an invisible layer of searchable text on top of it. If the page goes blank, it is a display or software rendering error, not an intentional deletion of your image.
How can I recover my PDF if it turned blank after saving?
If you accidentally saved over the original file after the blank page error occurred, you will need to restore a previous version from your system backups or original source, as the rendered image layer might be permanently corrupted in that saved instance.
Can I extract text from a PDF without using Adobe Acrobat?
Yes, alternative lightweight PDF editors like WPS Office feature built-in, highly accurate OCR tools that can easily extract, recognize, and convert scanned PDF images into editable text formats without rendering errors.


