

How to Fix PDF Tables Exporting Incorrectly to Excel with Merged Cells

Question details
The user needs to resolve formatting inaccuracies, such as merged cells and missing headers, when converting tables from PDF documents to Excel.
- Product
- PDF to Excel Converter
- Device & OS
- not provided
- Scenario
- Exporting structured table data from a PDF file to Excel for further data modeling and analysis using tools like Power Pivot.
- Observed behavior
- The exported Excel file contains merged cells, missing column headers (like years), or yields empty results when processed in Power Pivot due to poor PDF structure.
Verify if the original PDF contains selectable text or is a scanned image, as scanned documents require OCR (Optical Character Recognition) enabled during conversion for accurate table extraction.
Clean Up Formats Post-Conversion and Unmerge Cells
Manually adjust the converted Excel file to remove merged cells and restore missing headers so the data functions properly in Power Pivot.
PDFs are designed as final-format viewing files rather than data storage containers. Unless the PDF was properly tagged with structural table elements during its creation, standard conversion tools often merge cells to replicate the visual spacing of the original document.
Open the converted file in Excel. Click the top-left corner of the table or press Ctrl+A to select the entire dataset.
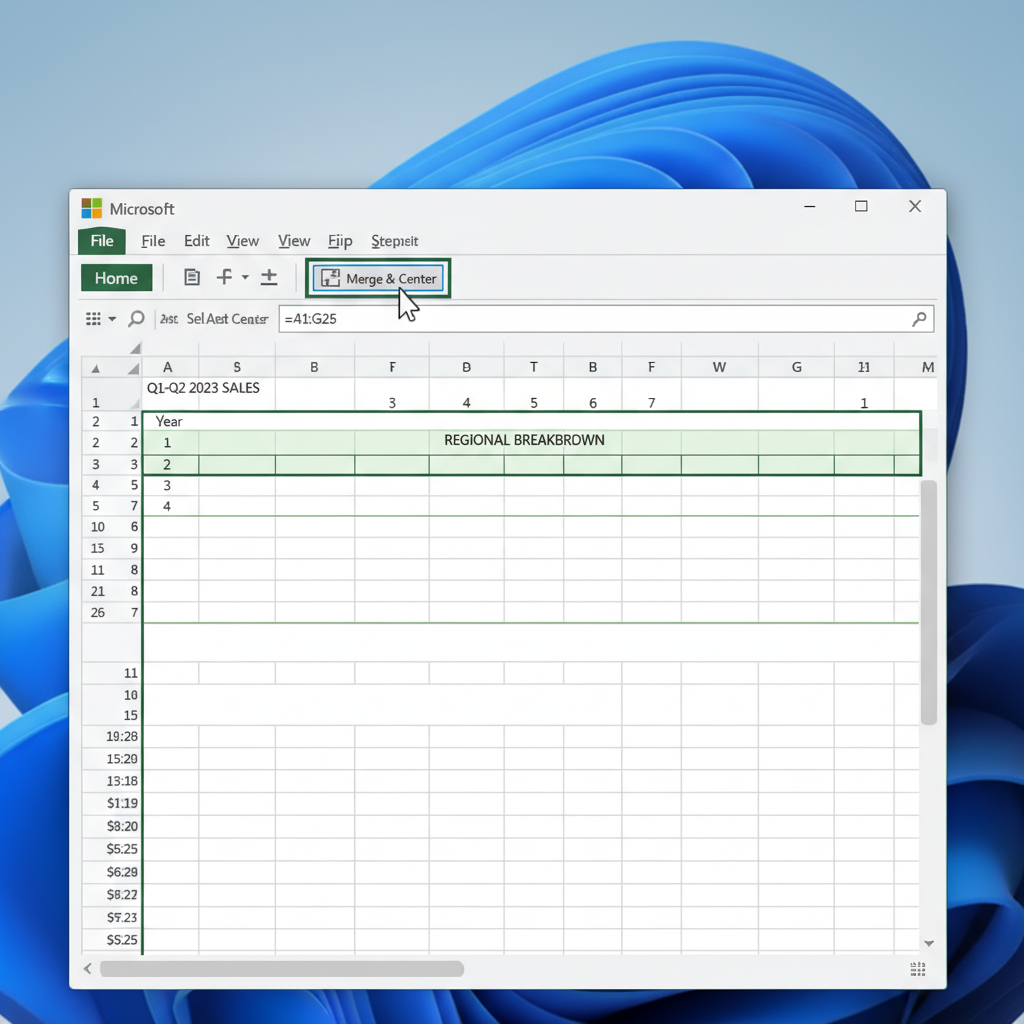
Navigate to the 'Home' tab on the ribbon and click the 'Merge & Center' button to immediately unmerge all combined cells in the selected range.
To fill the resulting blank cells with the correct data above them, press F5, click 'Special...', select 'Blanks', type '=' and press the Up Arrow key, then press Ctrl+Enter.
Manually type in any missing column headers (like years or categories). Then, select the cleaned data and press Ctrl+T to format it as a standard Excel Table before importing it to Power Pivot.
Extract Data Using Power Query
Bypass standard PDF export by using Excel's built-in Power Query tool to extract tables directly from the PDF file, allowing for better structural control.
Use WPS PDF to Excel for Accurate Table Conversion
WPS Office provides an advanced PDF to Excel conversion tool designed to preserve complex table structures, minimizing formatting issues like merged cells and lost headers so your data is immediately ready for analysis.
- 1. Open the PDF in WPS: Launch WPS Office and open your problematic PDF document within the built-in PDF viewer.
- 2. Access the conversion tool: Navigate to the 'Tools' tab at the top of the interface and click on the 'PDF to Excel' button.
- 3. Configure and convert: Choose your desired output location, select the specific pages containing the tables if necessary, and click 'Convert' to process the file.
- 4. Review in WPS Spreadsheet: Once the conversion finishes, the file will automatically open in WPS Spreadsheet where you can effortlessly verify headers and perform data analysis without dealing with messy merged cells.

Frequently Asked Questions
Why do my PDF tables merge cells when exported to Excel?
PDF files prioritize visual layout and typography over underlying data structure. If the original document lacks proper table structure tags, the conversion tool attempts to guess the layout. This often results in merged cells to replicate the visual spacing and margins of the original PDF.
How can I prevent missing headers during PDF conversion?
Missing headers typically occur if they are formatted differently from the table body or if the table is split across multiple pages. To minimize this, use advanced PDF editors with dedicated table-extraction tools, or use Power Query in Excel to define and promote the headers manually.
Does scanned PDF table conversion work as well as native text PDFs?
No, scanned PDFs are essentially images and require Optical Character Recognition (OCR) to read the text. While modern OCR is highly accurate, it is more prone to structural errors like misaligned columns, dropped characters, or merged cells compared to native text PDFs. Always use a high-quality OCR tool for scanned documents.


