

How to Fix PDF Text Becoming Gibberish When Copied and Pasted

Question details
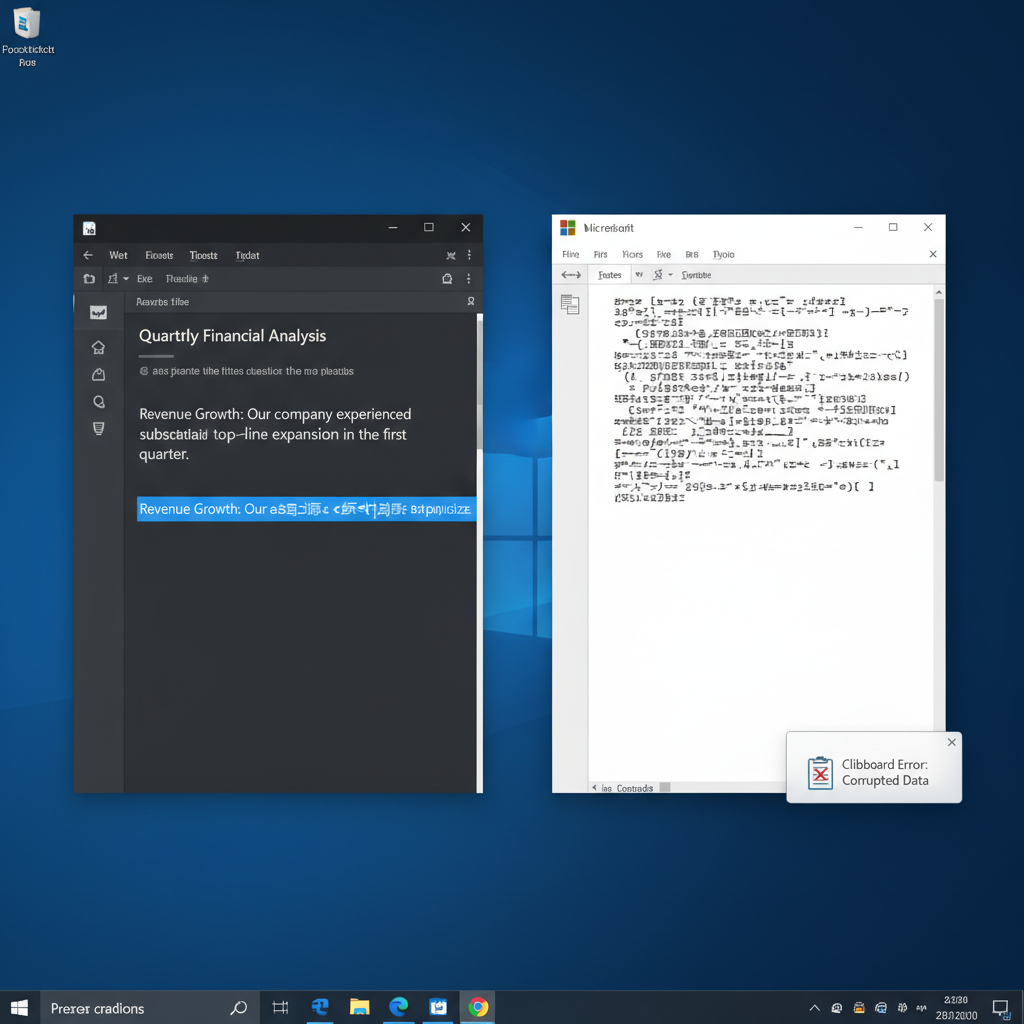
Users experience corrupted formatting or unreadable symbols when attempting to copy text from a PDF.
- Product
- Device & OS
- not provided
- Scenario
- Extracting or reusing text from a PDF document by copying it to the clipboard and pasting it into another application, such as Microsoft Word or a text editor.
- Observed behavior
- Instead of the original text, pasting the copied selection outputs unreadable symbols, corrupted characters, or complete gibberish.
Ensure the application you are pasting into supports standard text encoding (like UTF-8). If your PDF contains sensitive or confidential information, be prepared to use a local desktop application rather than an online OCR service to protect your data.
Extract the Text Using the OCR Feature
Applying Optical Character Recognition (OCR) bypasses underlying font encoding errors by visually recognizing the characters on the page and creating fresh, copyable text.
The gibberish text problem typically occurs because the PDF uses an incorrect, missing, or custom font encoding map. The visual representation is correct, but the underlying text data is unreadable to the clipboard. Using an OCR tool forces the software to 'read' the text visually.
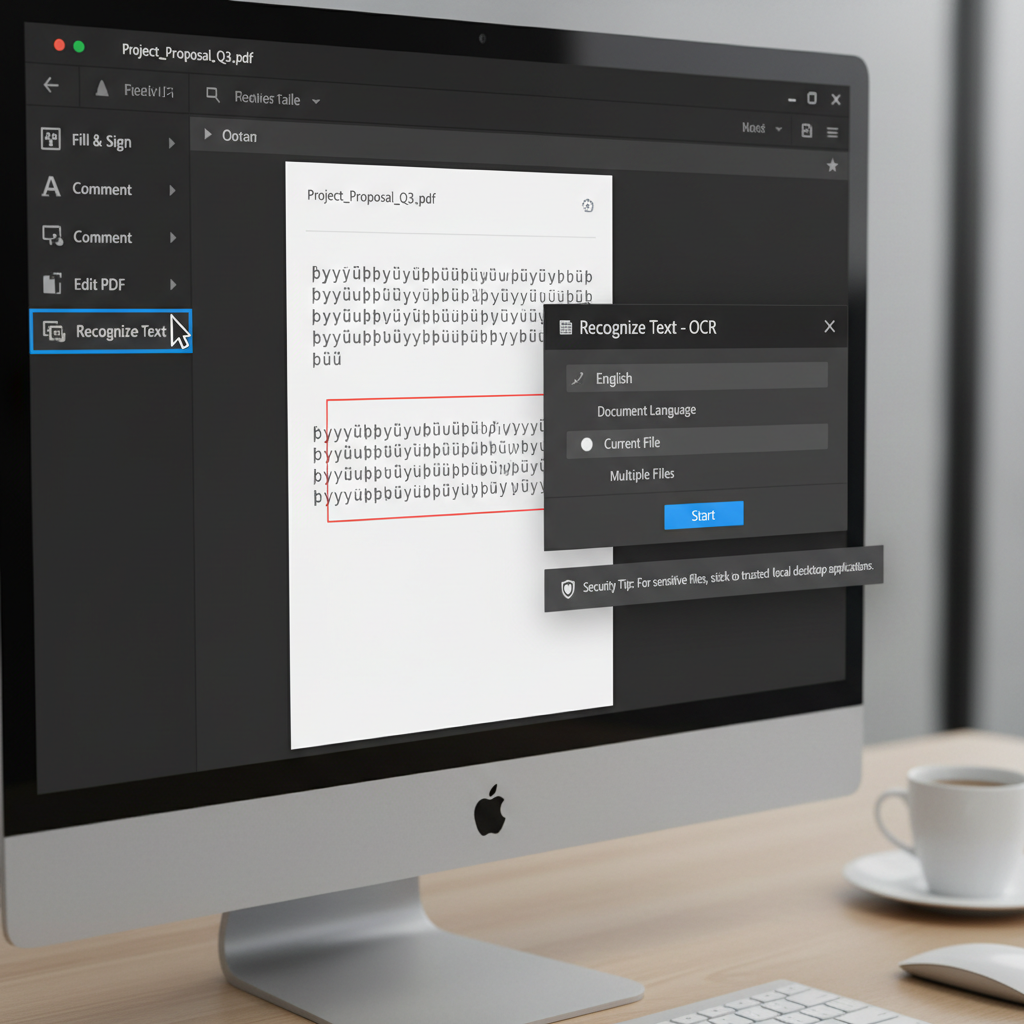
Launch your preferred PDF software, such as Adobe Acrobat or WPS Office, and open the problematic PDF document.
Navigate to the 'Tools' menu and select 'Recognize Text' or 'OCR'. Ensure you set the correct language that matches the document's content.
Click 'Start' or 'Recognize' to process the document. Depending on the size of the PDF, this may take a few moments.
Once the OCR process is complete, highlight the newly recognized text using your cursor, press Ctrl+C to copy, and paste it into your desired application.
Recreate the PDF from the Source Document
If you have access to the original source file, re-exporting it properly can permanently fix the font encoding issues.
Extract Text from PDFs Accurately with WPS Office
WPS Office includes a highly accurate, built-in OCR tool that quickly recognizes text from improperly encoded PDFs, allowing you to copy, paste, and edit without encountering gibberish.
- 1. Open the Problematic PDF: Launch WPS Office, click 'Open', and select the PDF file containing the unreadable text.
- 2. Navigate to the OCR Tool: Click on the 'Tools' tab on the top ribbon menu, then select the 'OCR' or 'Picture to Text' button.
- 3. Extract and Copy the Text: Select the specific area or page you need, confirm the document language, and click 'Extract Text'. You can now safely copy the accurate text and paste it anywhere.

Frequently Asked Questions
Why does copied PDF text turn into symbols?
This happens when the PDF uses custom or subset fonts without proper Unicode character mapping. The computer knows what the font looks like visually, but doesn't know what underlying letters the shapes represent, resulting in a clipboard full of gibberish.
Can I fix the font encoding of the PDF directly without OCR?
Fixing the underlying encoding of an existing PDF directly is technically complex and usually requires specialized software like Adobe Acrobat Pro. It's almost always faster and easier to either run an OCR tool on the file or recreate the PDF entirely from the original source file.
Will using 'Print to PDF' fix the gibberish text issue?
Using 'Print to PDF' essentially flattens the file and strips the problematic font encoding completely. While this removes the bad encoding, it turns the entire document into an image. You will still need to run an OCR tool on this newly flattened PDF to make the text selectable and copyable again.


