

How to Fix PDFs Created from Web Pages Saving as Images

Question details
The user is unable to select or edit text in PDFs generated from web pages because the content is saved entirely as images.
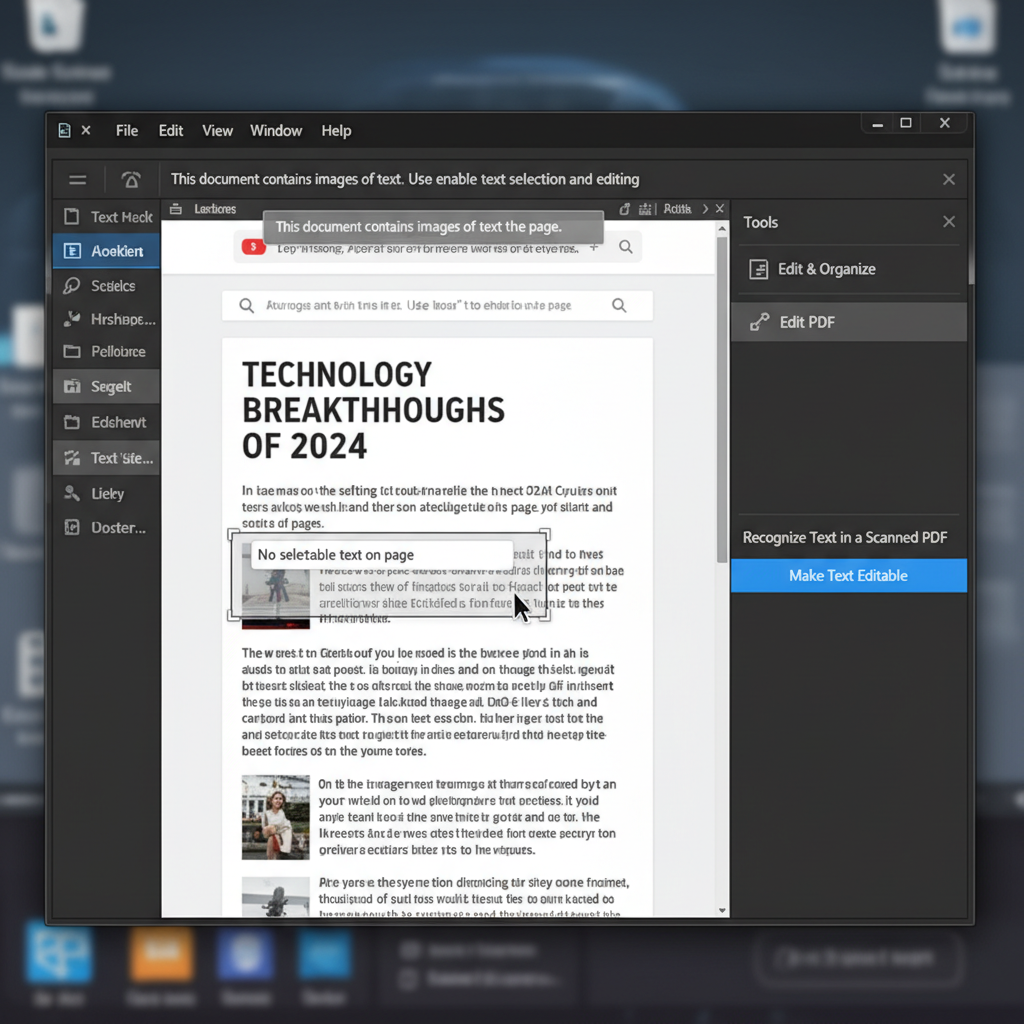
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Converting a web page into a PDF document with the intention of editing, copying, or searching the text.
- Observed behavior
- The resulting PDF preserves the web page layout but flattens the content into images, making the text impossible to select or edit.
Ensure the original web page is fully loaded before conversion. Note that some websites use image-based graphics for text to protect content, requiring Optical Character Recognition (OCR) software to make it readable.
Use OCR in Adobe Acrobat Pro to Recognize Text
Since the web page was flattened into an image during conversion, using Acrobat's built-in OCR feature will identify the characters and convert them back into editable text.
When websites are built using complex visual elements or image-based text, PDF converters often capture them as flat images to maintain visual fidelity. Running OCR (Optical Character Recognition) analyzes these images and overlays invisible, selectable text on top of them.
Launch Adobe Acrobat Pro and open the PDF file that was generated from the web page.
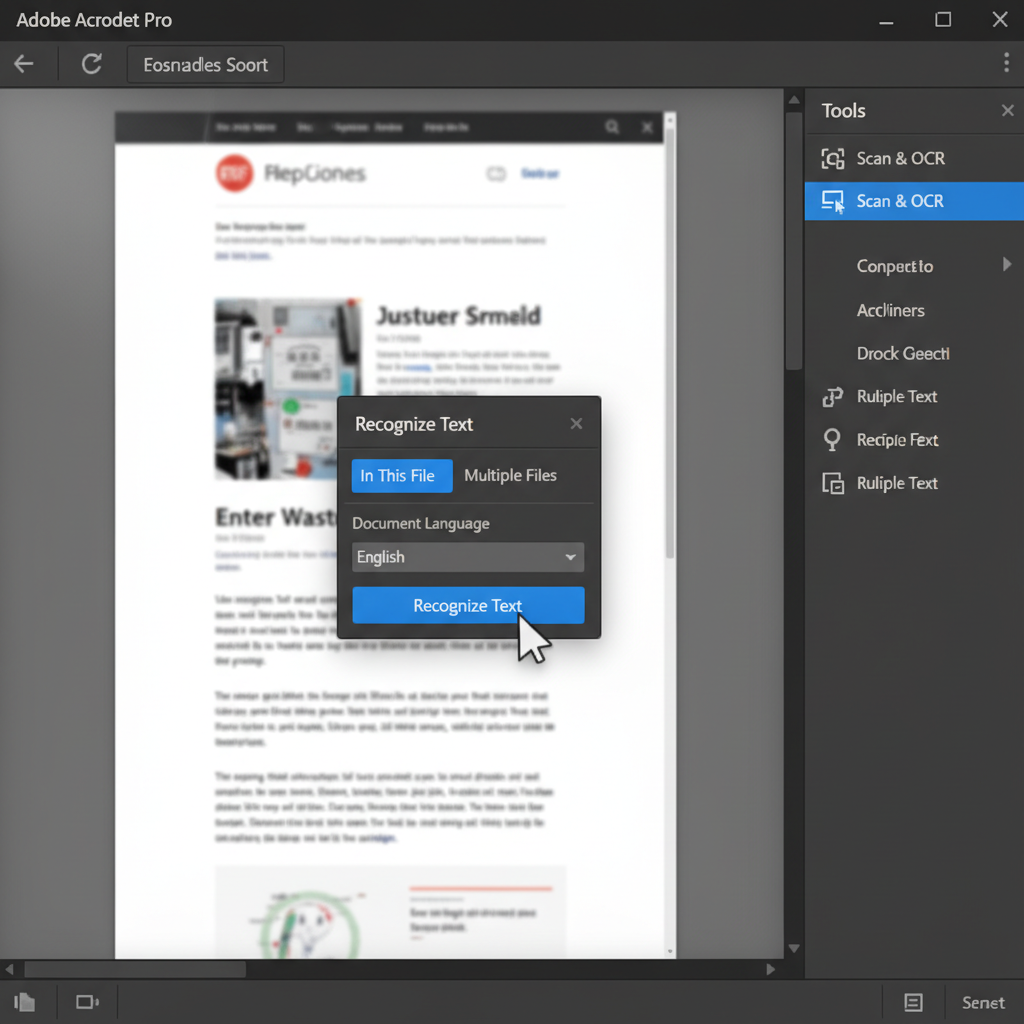
Navigate to the right-hand panel or go to the 'Tools' menu at the top left, then select 'Scan & OCR'.
Click on 'Recognize Text' in the toolbar, select 'In This File', and choose your preferred document language.
Click the 'Recognize Text' button to initiate the scan. Once the process completes, you can use the 'Edit PDF' tool to select, copy, or modify the newly recognized text.
Easily Convert Image-Based PDFs to Editable Text using WPS OCR
If your PDF saved as an image, WPS Office offers a powerful and highly accurate OCR (Optical Character Recognition) feature. You can effortlessly extract text from image-based web page PDFs and edit them directly without needing expensive software.
- 1. Open your PDF: Launch WPS Office and open the image-based PDF created from your web page.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Extract the Text: Select the specific area or the entire page you wish to scan, confirm the language, and click 'Extract text'.
- 4. Save or Edit: Copy the recognized text to your clipboard, or choose to convert it directly into an editable Word document for further adjustments.

Frequently Asked Questions
Why do some web pages save as images instead of text when printed to PDF?
Many modern websites use complex CSS rendering, canvas elements, or actual image files instead of standard HTML text to display stylized fonts. When standard PDF converters capture these pages, they often flatten these complex elements into standard images to preserve the visual layout.
Can I prevent the web page from becoming an image before converting?
Yes, you can try activating 'Reader Mode' or 'Reading View' in your web browser before printing to PDF. This strips away complex formatting, backgrounds, and scripts, leaving plain HTML text that usually converts into a perfectly editable PDF document.
Does OCR work effectively on low-resolution web page screenshots?
OCR accuracy drops significantly with low-resolution or heavily compressed images. If the web page text appears blurry or pixelated in the generated PDF, the OCR engine may struggle to accurately recognize the characters. Zooming in on the web page before saving to PDF can improve the resolution.
Is it possible to extract only a specific paragraph from an image-based PDF?
Yes, many PDF editors, including WPS Office, offer a partial text extraction feature. You can select the OCR tool and draw a bounding box around just the specific paragraph or image area you want to convert into text, rather than processing the entire document.


