

How to Fix the Acrobat DC PaperCapture OCR Entry Point Error

Question details
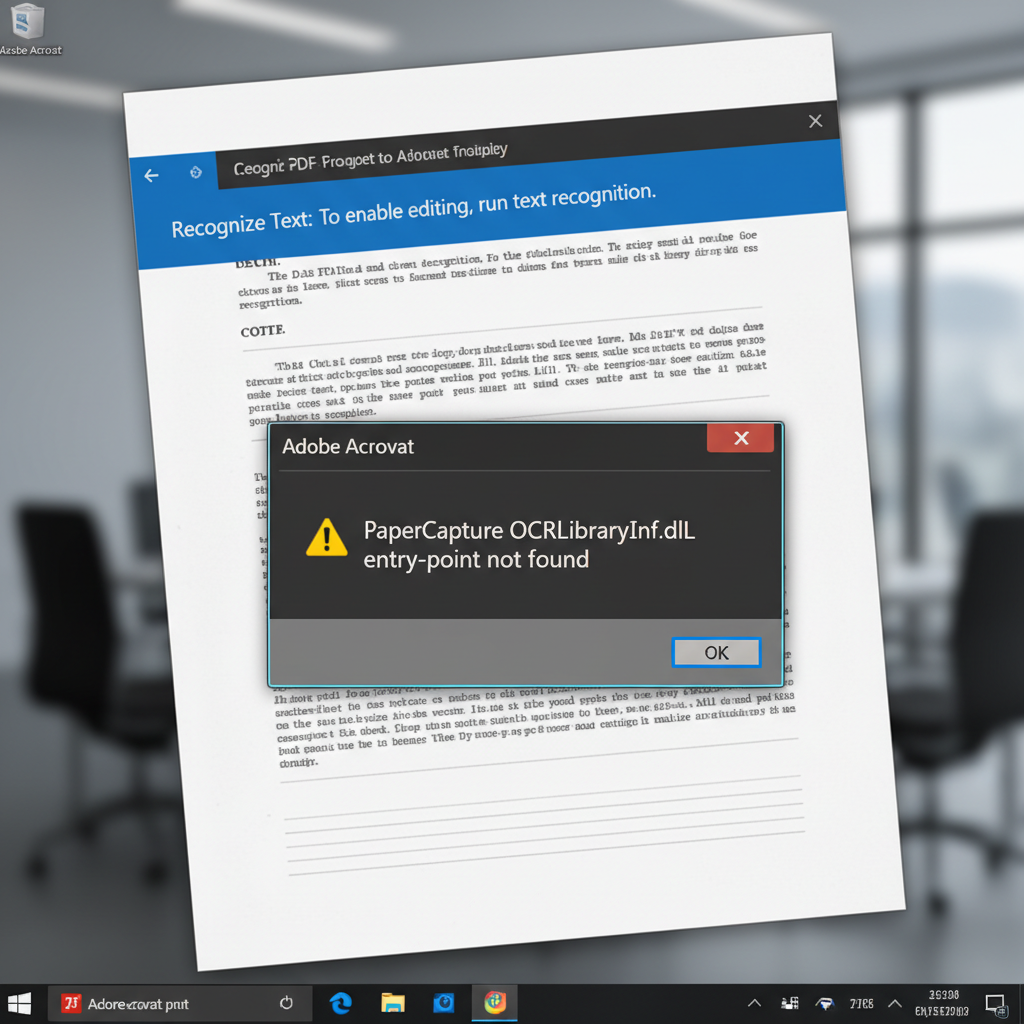
The user is encountering an OCRLibraryInf.dll entry-point error in Acrobat Pro DC when trying to process and edit scanned PDF pages.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- Windows
- Scenario
- Attempting to run Optical Character Recognition (OCR) to edit scanned PDF pages.
- Observed behavior
- Acrobat fails to process the scan and displays a PaperCapture OCRLibraryInf.dll entry-point error, preventing document editing.
Before proceeding, ensure your scanner is securely connected and that you have administrative privileges on your Windows computer to modify program files.
Copy the Required iDRS15 Files to the PaperCapture Folder
Resolves the OCRLibraryInf.dll error by manually restoring missing or corrupted iDRS15 recognition service files in the Acrobat directory.
This error is primarily caused by Acrobat being unable to access its internal recognition service. Copying the essential DLL files directly into the active plug-in folders often resolves the communication breakdown.
Open File Explorer and navigate to your Acrobat installation directory, typically located at C:\Program Files (x86)\Adobe\Acrobat DC\Acrobat.
Find and open the 'iDRS15' folder. Select all the files inside, right-click, and choose 'Copy'.
Navigate back to the main Acrobat folder, open the 'PaperCapture' folder, right-click in an empty space, and select 'Paste' to transfer the files.
Go to the 'plug_ins' folder (also in the Acrobat directory) and paste the exact same copied files there. Restart Acrobat and try the OCR tool again.
Update Scanner Drivers and Acrobat Firmware
Outdated drivers or older versions of Acrobat DC can cause compatibility issues with the OCR module.
Perform a Clean Reinstall of Acrobat DC
If core installation files are severely corrupted, a fresh installation will fully rebuild the OCR directories.
Seamlessly Extract Text from Scanned PDFs with WPS Office
Instead of troubleshooting complex DLL errors, you can use WPS PDF's built-in OCR feature to quickly convert scanned documents into editable text. WPS Office provides a powerful, lightweight PDF editor that fully supports advanced text recognition without complicated folder configurations.
- 1. Open Your Scanned PDF: Launch WPS Office and open your scanned PDF document using the WPS PDF viewer.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Configure Extraction Settings: Select the language of your document and choose whether you want to extract the text into a new Word document or make the current PDF editable.
- 4. Process the Document: Click 'Start' to process the document. Within seconds, you can begin editing, copying, or formatting the newly recognized text.

Frequently Asked Questions
What causes the Acrobat OCRLibraryInf.dll entry point error?
This error typically occurs when Acrobat's internal PaperCapture recognition service files (specifically the contents of the iDRS15 folder) are missing, corrupted, or not properly registered in the application's plug-ins directory.
Can outdated scanner drivers prevent OCR from working?
Yes. If your scanner drivers or device firmware are incompatible with your current version of Windows or Acrobat DC, it can interrupt the scan-to-text pipeline and trigger unexpected entry-point errors.
Where is the PaperCapture folder located in Windows?
By default, the PaperCapture folder is located within the Acrobat installation path, generally found at C:\Program Files (x86)\Adobe\Acrobat DC\Acrobat\plug_ins\PaperCapture.
Does WPS Office offer an alternative OCR tool?
Yes. WPS Office includes a robust PDF editor equipped with an OCR feature that allows users to seamlessly extract and edit text from scanned documents and images.


