

How to Fix the idrskrn15.dll Error During PDF OCR

Question details
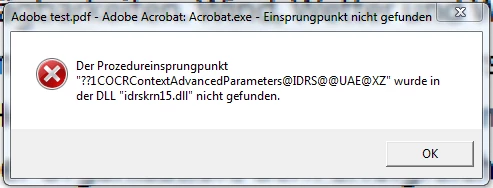
The user needs to resolve an idrskrn15.dll wrong-content error that occurs when attempting to perform Optical Character Recognition (OCR) on a PDF file.
- Product
- Adobe Acrobat / PDF Software
- Device & OS
- not provided
- Scenario
- Running OCR on a PDF document to make the text searchable or editable.
- Observed behavior
- The OCR process fails to complete and displays an error message referencing the idrskrn15.dll file.
Ensure your PDF software is fully updated to the latest version and restart your computer to clear any temporary background glitches before attempting to repair the OCR components.
Isolate the Issue and Verify OCR Language Settings
Testing a different file helps determine if the error is specific to one corrupted document or a broader application issue.
Often, a damaged or improperly formatted PDF can cause the OCR engine to crash. By running the OCR tool on a known-working document, you can figure out whether the problem lies with the specific file or your software's OCR component.
Open a different, known-working PDF file in your PDF software and run the OCR tool to see if the process completes successfully.
Navigate to your PDF software's OCR settings, usually found under the 'Tools' or 'Scan & OCR' menu.
Check the selected OCR language. Ensure the selected language matches the text in your document and that the language pack is properly installed.
Repair or Update the PDF Application
A missing or corrupted idrskrn15.dll file can often be fixed by running the software's built-in repair tool.
Use WPS Office to Extract Text from PDFs via OCR
If your current PDF reader continues to throw DLL errors, WPS Office provides a robust, built-in OCR feature to quickly and accurately convert your scanned PDFs or images into editable text without complex configuration.
- 1. Open the PDF: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon menu.
- 3. Initiate text recognition: Click on the 'OCR' button to launch the text recognition interface.
- 4. Extract the text: Select your desired output format (like Word or plain text) and extraction area, then click 'Extract text' to finish.

Frequently Asked Questions
What is the idrskrn15.dll file?
The idrskrn15.dll is a Dynamic Link Library file associated with Optical Character Recognition (OCR) engines in certain PDF applications. It is responsible for processing images and scanned documents into searchable and editable text.
Why does the OCR error only happen on one specific PDF?
If the error occurs exclusively on a single file, that PDF might contain corrupted metadata, unsupported embedded fonts, or a damaged image layer that causes the OCR engine to crash during processing.
Can I manually download and replace the idrskrn15.dll file?
It is highly discouraged to download DLL files from third-party websites due to malware and security risks. Instead, you should use the 'Repair Installation' feature of your PDF software to safely and officially restore the file.
How do I change the OCR language?
In most PDF editors, you can adjust the OCR language by accessing the OCR or Scan settings menu right before you initiate text recognition. Ensuring it matches the language of your document improves accuracy and prevents processing errors.


