

How to OCR and Export a Specific Area of a Scanned PDF
Question details
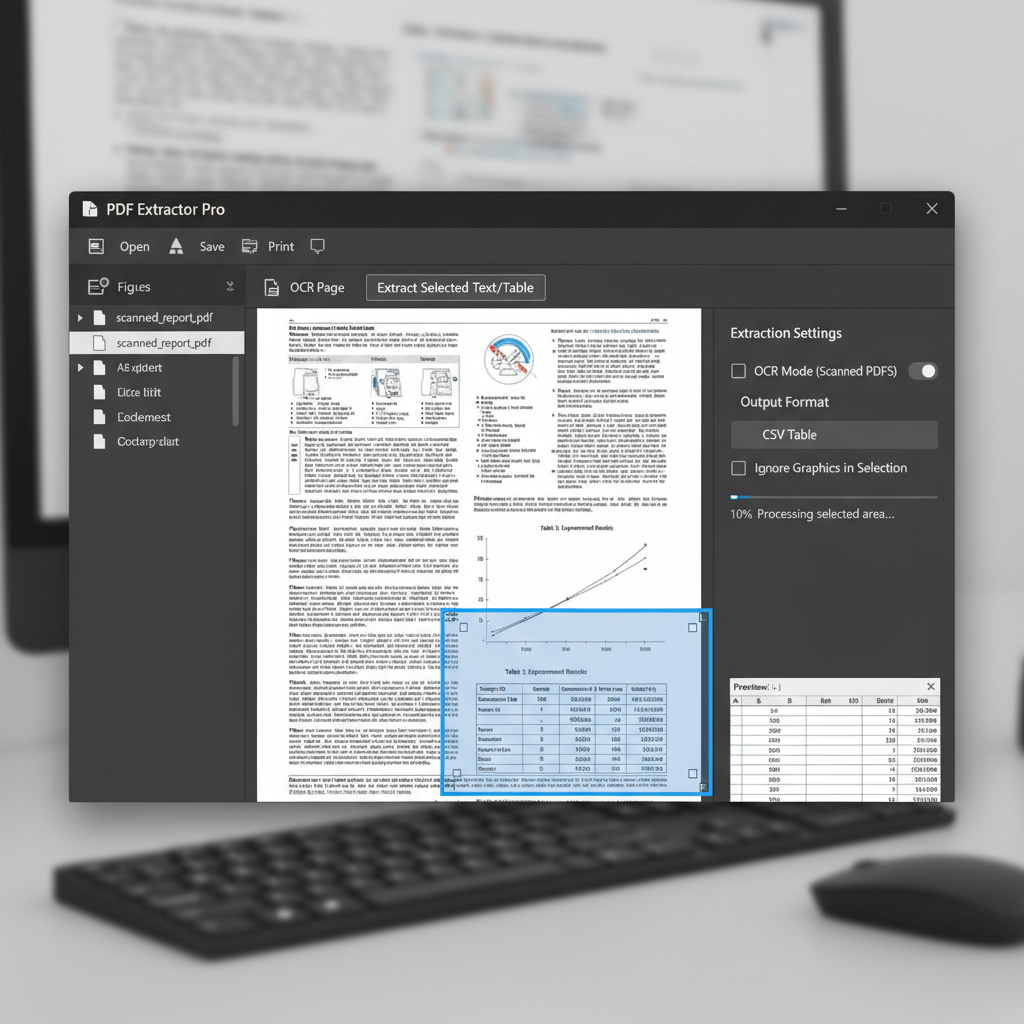
The user needs to extract text or tabular data from a specific region of a scanned PDF without processing the irrelevant content on the rest of the page.
- Product
- Device & OS
- not provided
- Scenario
- Extracting localized tables or text snippets from large, cluttered scanned PDF pages to improve extraction accuracy.
- Observed behavior
- Running standard OCR processes the entire page, which extracts unwanted data alongside the necessary content and requires manual cleanup.
Always create a duplicate copy of your original scanned PDF before cropping or using redaction tools, as these actions alter the document structure.
Isolate the Area Using the Crop Tool Before OCR
Use the crop tool to remove irrelevant parts of the scanned page so the OCR engine focuses only on the specific table or text you need.
By cropping the document first, you limit the OCR engine's processing area. This not only speeds up the conversion process but also significantly reduces unwanted data in your final export.
Duplicate your scanned PDF file to ensure the original remains intact.
Open the copied PDF in your PDF editor and navigate to the 'Edit' or 'Page' menu, then select the 'Crop' tool.
Draw a crop box precisely around the table or text region you want to extract, and apply the crop to hide the irrelevant content.
Navigate to the 'Tools' or 'Convert' menu and select 'OCR' (Optical Character Recognition). Choose your document language and run the process.
Once the text is recognized, select 'Export To' or 'Save As' and choose your desired format, such as Microsoft Excel or Word.
Use Redaction Tools to Block Unwanted Content
If cropping is not viable, redaction tools can permanently black out irrelevant sections so the OCR engine ignores them.
Effortlessly Extract and OCR PDF Regions with WPS Office
WPS Office features an advanced built-in OCR engine that makes extracting data from specific areas of a scanned PDF incredibly simple. You can easily crop, recognize, and export directly to Word or Excel without complex workarounds.
- 1. Open your scanned PDF: Launch WPS Office and open your scanned PDF document.
- 2. Access OCR tools: Go to the 'Tools' tab and select 'OCR' or 'Picture to Text'.
- 3. Select the specific area: Use the selection tool to highlight exactly the table or paragraph you need to extract.
- 4. Convert and save: Click 'Extract Text' or 'Extract to Excel' to immediately convert the localized area into your desired editable format.
Frequently Asked Questions
Can I extract a table from a scanned PDF directly to Excel?
Yes, after isolating the table and running OCR, you can export the recognized data specifically to an Excel spreadsheet format (.xlsx) using a capable PDF editing software.
Does cropping a PDF permanently delete the hidden content?
In many PDF viewers, cropping only hides the content outside the crop box visually. To permanently remove it and ensure only the visible part is OCR'd, you may need to use redaction tools or 'Print to PDF' to flatten the document first.
Why is the OCR output inaccurate after isolating the area?
OCR accuracy heavily depends on scan resolution. Ensure the isolated area has high contrast and is clear. If the text is blurry, try enhancing the scan quality or adjusting the brightness/contrast before running OCR.


