

How to OCR Only Replacement Pages in Acrobat Pro DC

Question details
The user wants to perform text recognition (OCR) exclusively on newly inserted or replacement pages within a larger PDF document, rather than processing the entire file.
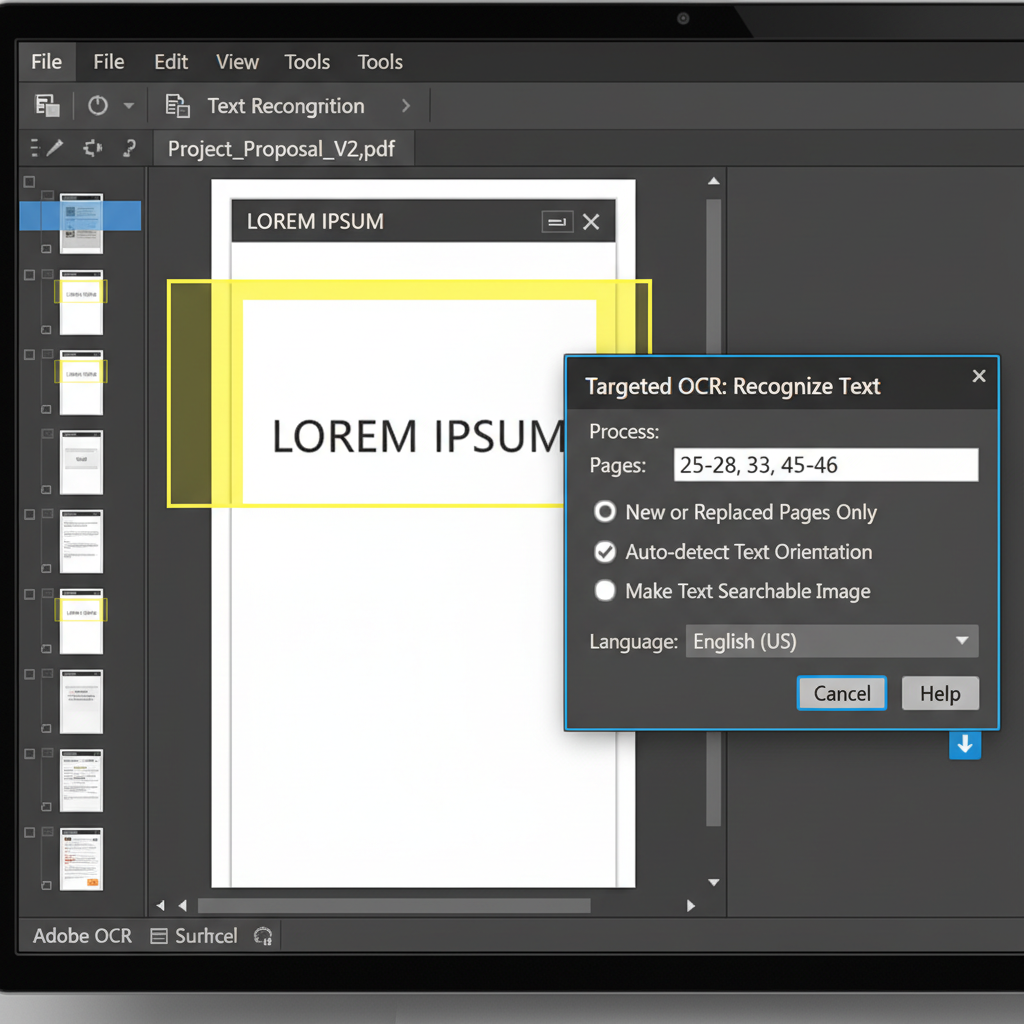
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Editing a lengthy PDF document by adding or replacing certain scanned pages that require text recognition to become searchable and editable.
- Observed behavior
- To save time and preserve the formatting of already processed pages, the user needs a method to target OCR functions to specific page ranges.
Verify the exact page numbers of your newly inserted or replacement pages within the PDF document before initiating the text recognition process.
Specify the Page Range During the OCR Command
Use Acrobat's built-in page range selection to run OCR only on the pages you just inserted.
Adobe Acrobat Pro DC allows you to limit the scope of the Recognize Text tool. By specifying a page range, you avoid wasting system resources on pages that are already searchable.
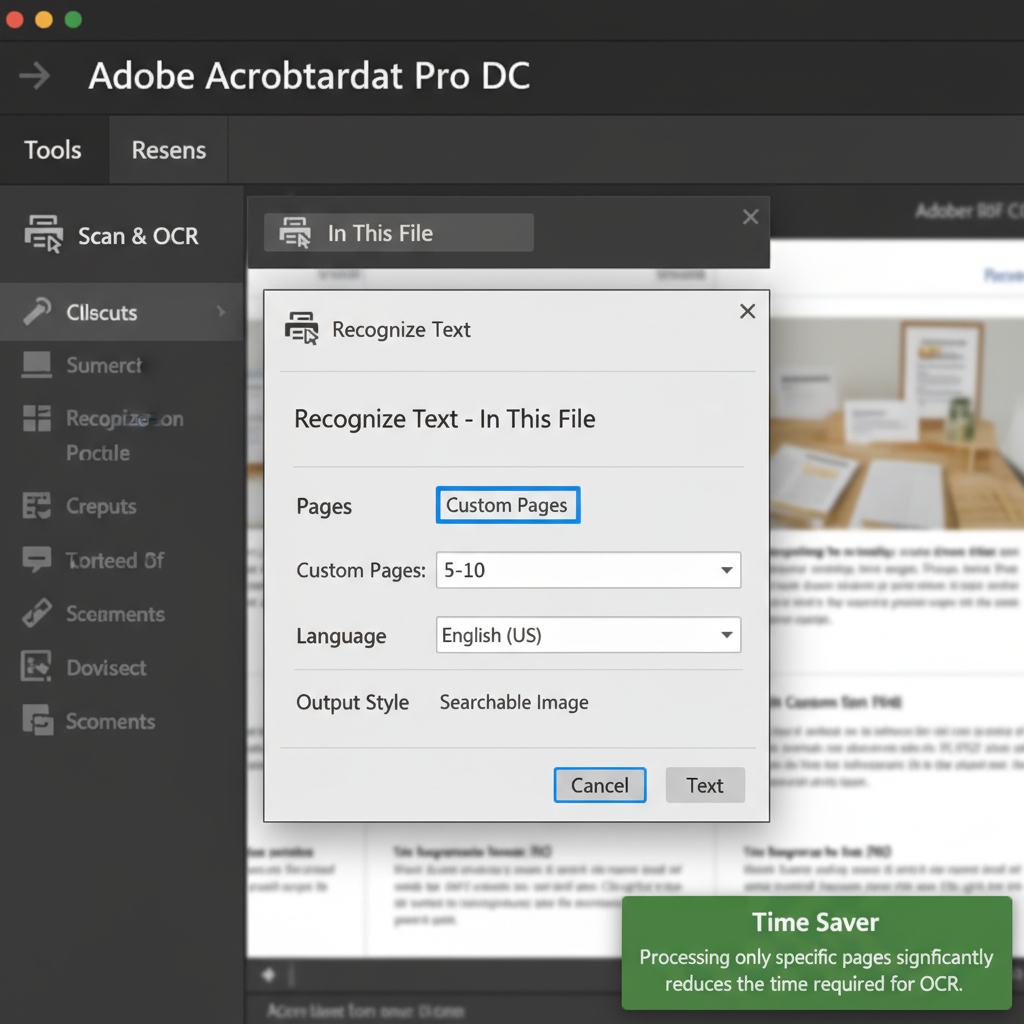
Open your PDF in Acrobat Pro DC. Go to the 'Tools' tab and select 'Scan & OCR' from the available options.
In the secondary toolbar, click on 'Recognize Text' and then choose 'In This File' from the dropdown menu.
Click on the 'Pages' option (often displayed as 'All Pages' by default). Change the selection to 'Custom Pages' and enter the specific page numbers corresponding to your replacement pages.
Adjust your preferred settings (such as language and output style) if necessary, and click the 'Recognize Text' button to process only the selected pages.
OCR the Replacement Pages Before Insertion
Perform text recognition on the standalone replacement pages prior to adding them to the main document.
Easily OCR Specific PDF Pages Using WPS Office
WPS Office includes a robust PDF editor equipped with high-accuracy OCR tools. It allows you to selectively extract and convert text from specific scanned pages without needing expensive premium software.
- 1. Open your PDF: Launch WPS Office and open the PDF document containing the scanned pages.
- 2. Access the OCR tool: Navigate to the 'Tools' tab and click on the 'OCR' button on the toolbar.
- 3. Set the page range: In the OCR dialog box, choose the 'Custom Pages' option and input the exact page numbers of your replacement pages.
- 4. Extract the text: Select your desired output format (such as DOCX or a searchable PDF overlay) and click 'Extract' or 'Convert'.

Frequently Asked Questions
Why does the OCR process fail on certain replacement pages?
OCR may fail if the replacement pages are already text-based rather than images, if the resolution of the scan is too low (under 300 DPI), or if the text is heavily obscured or handwritten.
Can I select multiple non-consecutive pages for OCR in Acrobat?
Yes, when selecting custom pages in the Recognize Text dialog, you can enter non-consecutive page numbers separated by commas (e.g., 5, 12, 18-20).
Will running OCR again degrade the quality of my PDF?
Running OCR over a previously processed document typically does not degrade the visual quality, but it can create invisible duplicate text layers which might affect text searching and copying. It is best to process only the pages that lack a text layer.


