

How to OCR Thousands of PDF Pages Without Acrobat Crashing
Question details
The user needs to perform optical character recognition (OCR) on exceptionally large PDF documents (thousands of pages) without the software failing.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
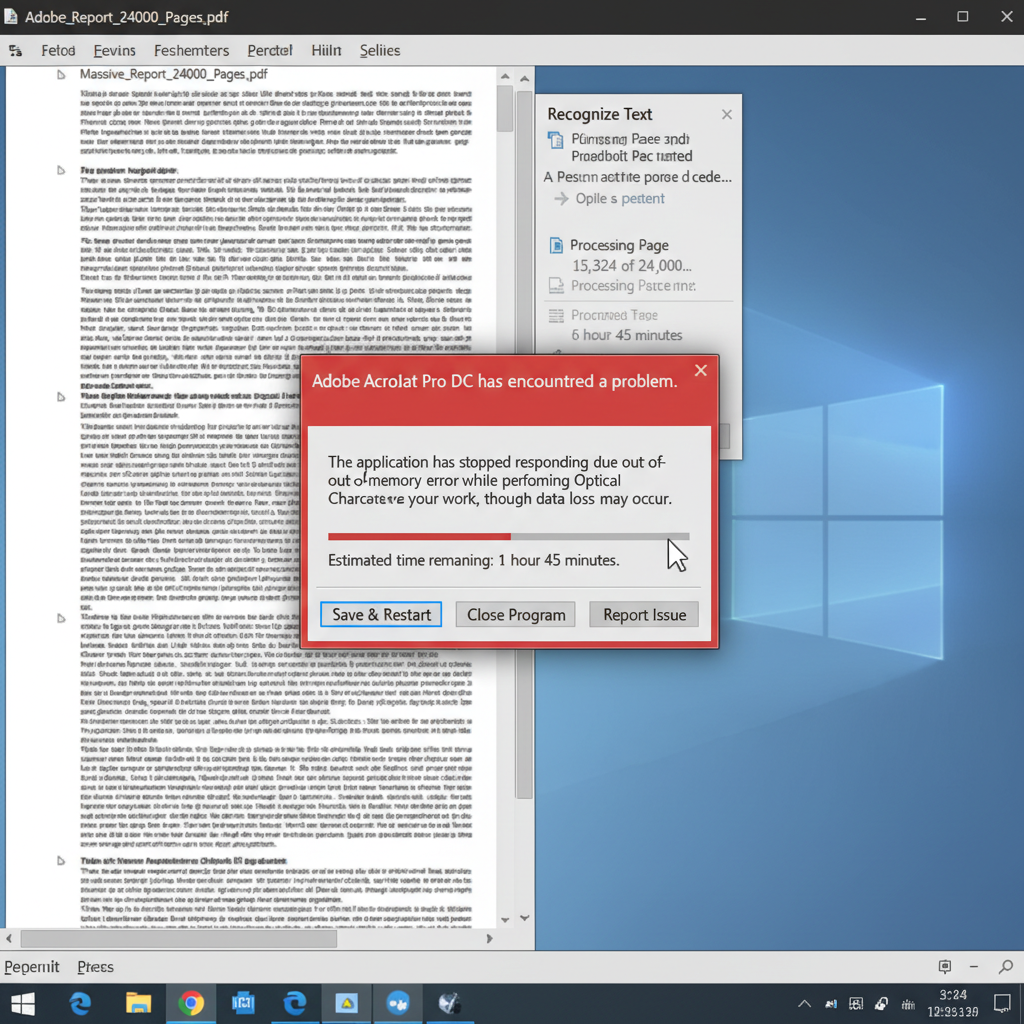
- Attempting to process, save, or bookmark massive PDF documents containing upwards of 10,000 to 24,000 pages using OCR tools.
- Observed behavior
- The software crashes, freezes, or completely locks up during processing, saving, or when adding new pages and bookmarks.
Before beginning the OCR process on massive documents, verify that your computer has sufficient available RAM, and ensure you have created an unmodified backup copy of your original PDF.
Split the PDF into Smaller Sections for Batch OCR
Processing extremely large documents in one pass often exceeds software memory limits. Splitting the file into smaller, manageable chunks prevents Acrobat from crashing during the OCR process.
Adobe Acrobat does not have an explicitly defined maximum page limit for OCR, but handling thousands of pages simultaneously consumes significant computational resources. Breaking the document into chunks of approximately 200 pages is a proven method to bypass memory overflow issues.
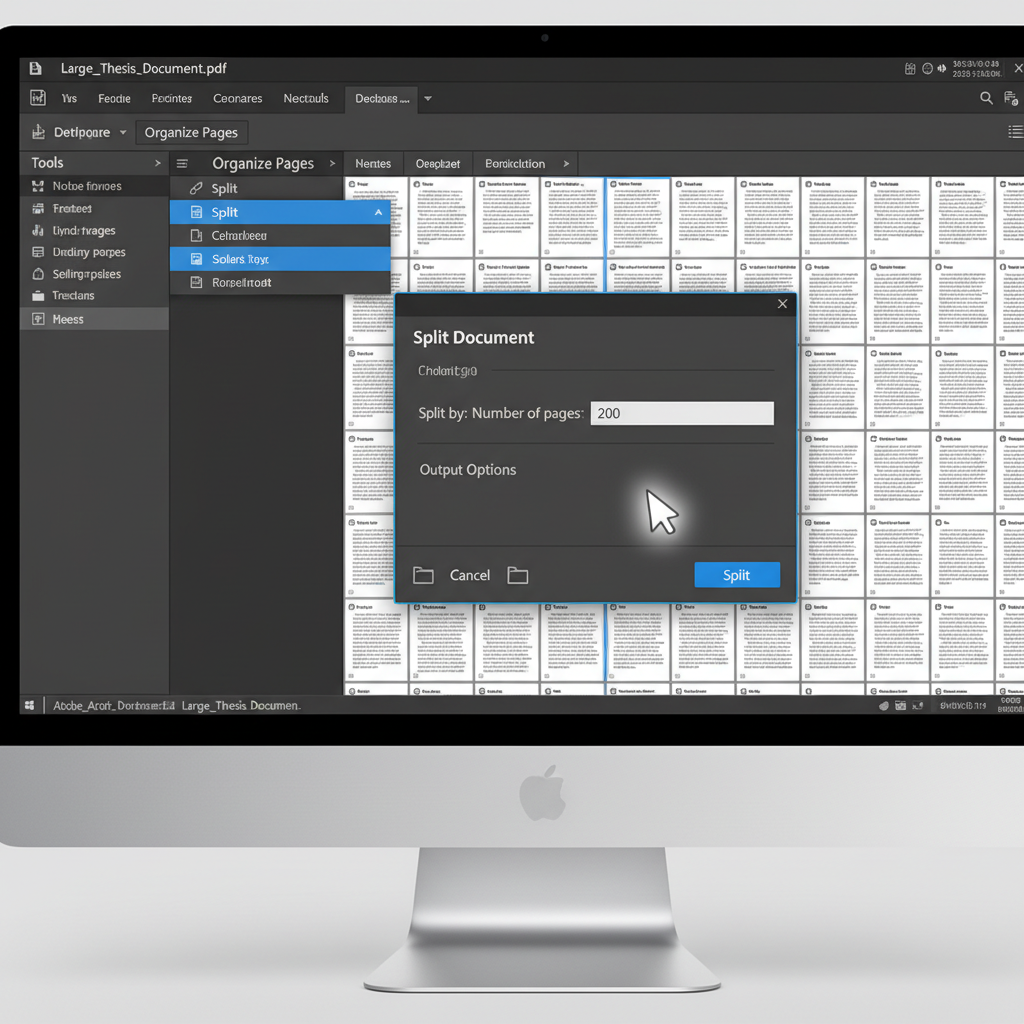
Launch Adobe Acrobat Pro DC, open your large PDF document, and navigate to the 'Tools' menu. Select 'Organize Pages'.
Click the 'Split' button in the top toolbar. Choose to split by 'Number of pages' and enter a safe value, such as 200. Click 'Split' to save these smaller files to a designated folder.
Open each newly split PDF document individually. Go to 'Tools', select 'Scan & OCR', and click 'Recognize Text'. Process and save each file one by one.
Once all sections have been successfully OCR'd, go to 'Tools' and select 'Combine Files'. Add all your processed PDF sections in the correct order and merge them back into a single document.
Use WPS Office for Reliable and Lightweight PDF Processing
If your current software continually crashes under heavy workloads, WPS Office offers a highly optimized PDF editor equipped with a powerful OCR engine. It handles document splitting, merging, and text recognition with minimal system resource consumption.
- 1. Import Your PDF: Open WPS Office and launch the WPS PDF tool. Browse your files and open the scanned PDF document you wish to process.
- 2. Access the OCR Feature: Navigate to the 'Tools' tab located on the top ribbon and click the 'OCR' icon to launch the text recognition module.
- 3. Configure and Extract: Choose your required document language and select your preferred output format (such as a searchable PDF or a Word document). Click 'Extract' to complete the process smoothly.
Frequently Asked Questions
Why does Adobe Acrobat crash when running OCR on large files?
Acrobat may crash during OCR because processing thousands of high-resolution pages simultaneously requires massive amounts of RAM and CPU power, often exceeding the software's memory allocation limits or the physical limits of your PC.
What is the maximum number of pages Acrobat can OCR at once?
While Adobe does not specify a hard coded maximum page limit for text recognition, users frequently experience performance drops or crashes when processing documents that exceed 200 to 500 pages, depending on system specifications and scan DPI.
Can I batch OCR multiple smaller PDFs automatically?
Yes, in Acrobat Pro, you can use the 'Action Wizard' tool to create a custom batch process. This allows you to target a specific folder containing your split PDFs and automatically run the 'Recognize Text' tool on all of them consecutively.
How does scan resolution affect PDF OCR performance?
Higher scan resolutions (such as 600 DPI) capture greater detail, which improves text recognition accuracy. However, this dramatically increases file size and computational load, making the software more susceptible to freezing or crashing during processing.


