

How to Perform OCR on PDFs with Both English and Chinese Text

Question details
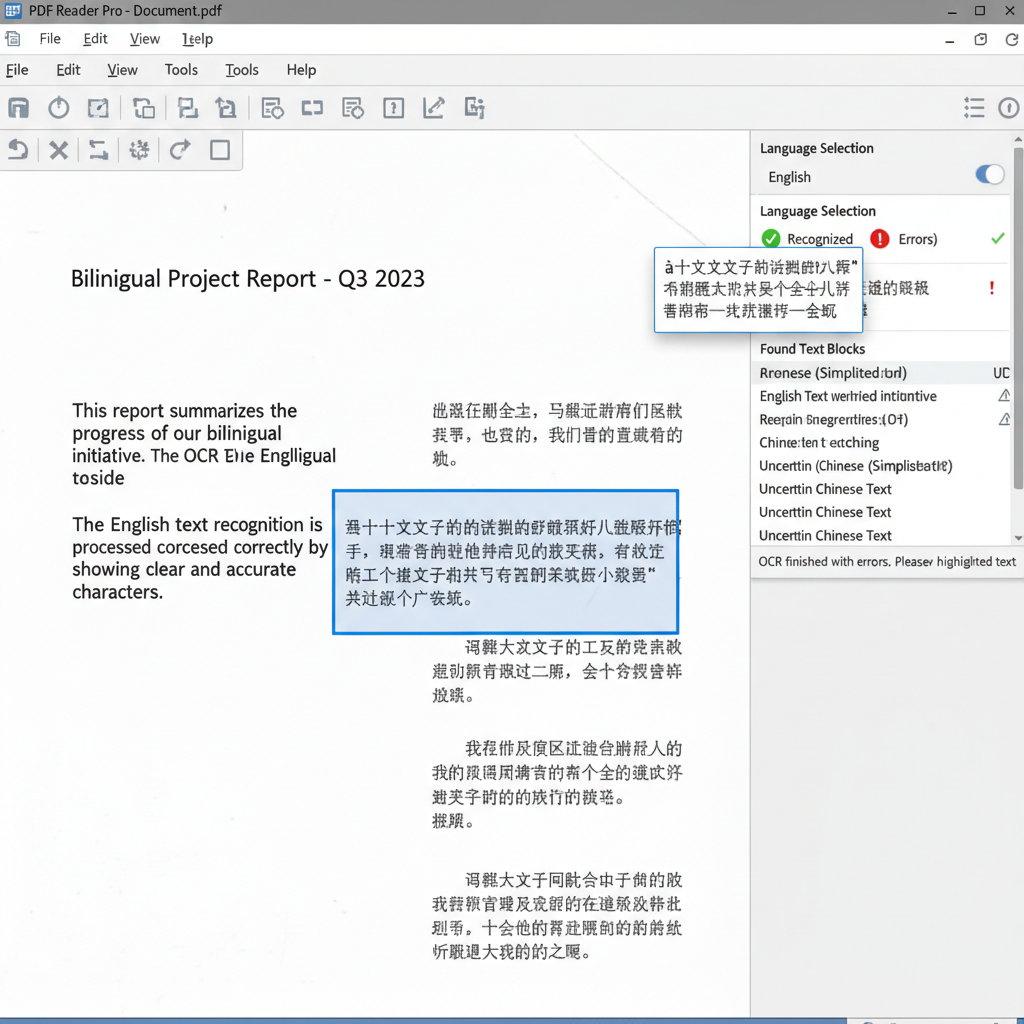
The user needs to accurately recognize and extract text from a scanned PDF that contains both English and Chinese characters.
- Product
- Device & OS
- not provided
- Scenario
- Extracting text from a bilingual scanned document using OCR.
- Observed behavior
- The OCR tool recognizes English text accurately but produces poor or garbled results for the Chinese characters.
Ensure your scanned PDF document is clear and has a high resolution (preferably 300 DPI or higher) for the best OCR accuracy. It is also helpful to identify which pages contain predominantly English or Chinese text before starting.
Process the Document with Separate Language Settings and Combine
This method involves creating copies of the document and running OCR separately for each language, ensuring high accuracy for both English and Chinese.
When an OCR tool only processes one language accurately at a time, it is because the recognition engine forces characters to match the selected language model. By processing the text separately and combining the accurate portions, you can create a perfect bilingual document.
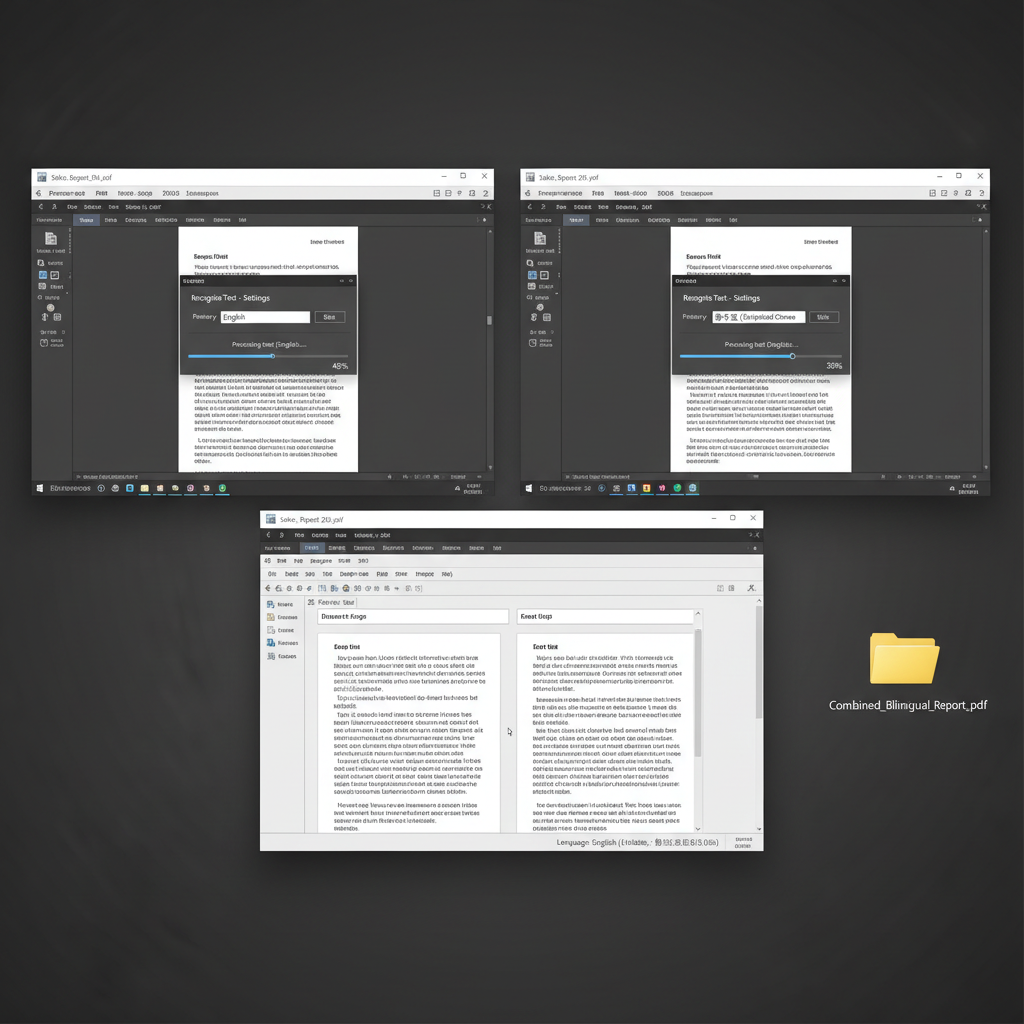
Duplicate your scanned PDF file to create two separate copies on your computer.
Open the first copy in your PDF editor, access the OCR tool, select 'English' as the recognition language, and extract the text to a Word document.
Open the second copy, launch the OCR tool, select 'Simplified Chinese' or 'Traditional Chinese' as the language, and extract the text.
Open a word processor that supports both languages. Copy the accurate English text from the first document and merge it with the accurate Chinese text from the second document.
Once the bilingual text is formatted correctly, export or save the combined document as a new PDF file.
Easily Extract Bilingual Text with WPS Office
WPS Office provides a powerful PDF toolkit with advanced OCR technology that can intelligently recognize and extract text from scanned documents in multiple languages, making it easy to convert mixed English and Chinese PDFs into editable Word documents.
- 1. Open the PDF: Launch WPS Office and open your scanned bilingual PDF document.
- 2. Access OCR: Go to the 'Tools' tab and click on the 'OCR' or 'Picture to Text' button.
- 3. Select Output Format: Choose whether you want to extract the text directly or convert it to a Word document.
- 4. Configure Language: If prompted, ensure the language settings are optimized for the document's content, then click 'Confirm' to start the extraction.

Frequently Asked Questions
Why does OCR fail on Chinese characters when English is recognized perfectly?
OCR engines rely on specific language models. If the engine is set to recognize only English, it will attempt to match Chinese characters to English letters or symbols, resulting in garbled text. You must explicitly select Chinese as a recognition language or use a multi-language OCR tool.
Can I select multiple languages at once when performing OCR?
Yes, many modern PDF editors and dedicated OCR software allow you to check multiple languages (like English and Chinese) in the settings menu before running the scan, which helps the software process mixed-language text accurately.
How can I improve the OCR accuracy for scanned PDFs?
To improve accuracy, ensure your source document is scanned at a high resolution (at least 300 DPI), the text is not blurry or skewed, and there is good contrast between the text and the background.
Does WPS Office support OCR for Traditional Chinese?
Yes, WPS Office's OCR feature supports both Simplified Chinese and Traditional Chinese, along with English and many other languages, allowing for versatile document conversion.


