

How to Remove Dark Blotches from Scanned PDFs After OCR
Question details
The user wants to remove dark blotches, black scan edges, and random speckles that appear on scanned PDF files after processing them with OCR, grayscale conversion, or adaptive compression.
- Product
- PDF Software
- Device & OS
- not provided
- Scenario
- Scanning physical documents and processing them with OCR or adaptive compression to create searchable PDFs.
- Observed behavior
- Dark blotches appear along page folds, and black edges or speckles are generated on the scanned pages after optimization or OCR processing.
Before modifying your scanner's optimization settings or applying new OCR passes, ensure you have saved a backup copy of your original, uncompressed raw scan files.
Adjust Scanner Optimization and Background Removal Settings
Tweak the background removal and compression options in your PDF editor to prevent dark blotches from forming during the OCR process.
Dark blotches and speckles are often the result of adaptive compression and grayscale conversion misinterpreting shadows from page folds or physical scanner edges.
By configuring your software to aggressively remove backgrounds and reduce adaptive compression artifacts before running OCR, you can achieve a much cleaner document.
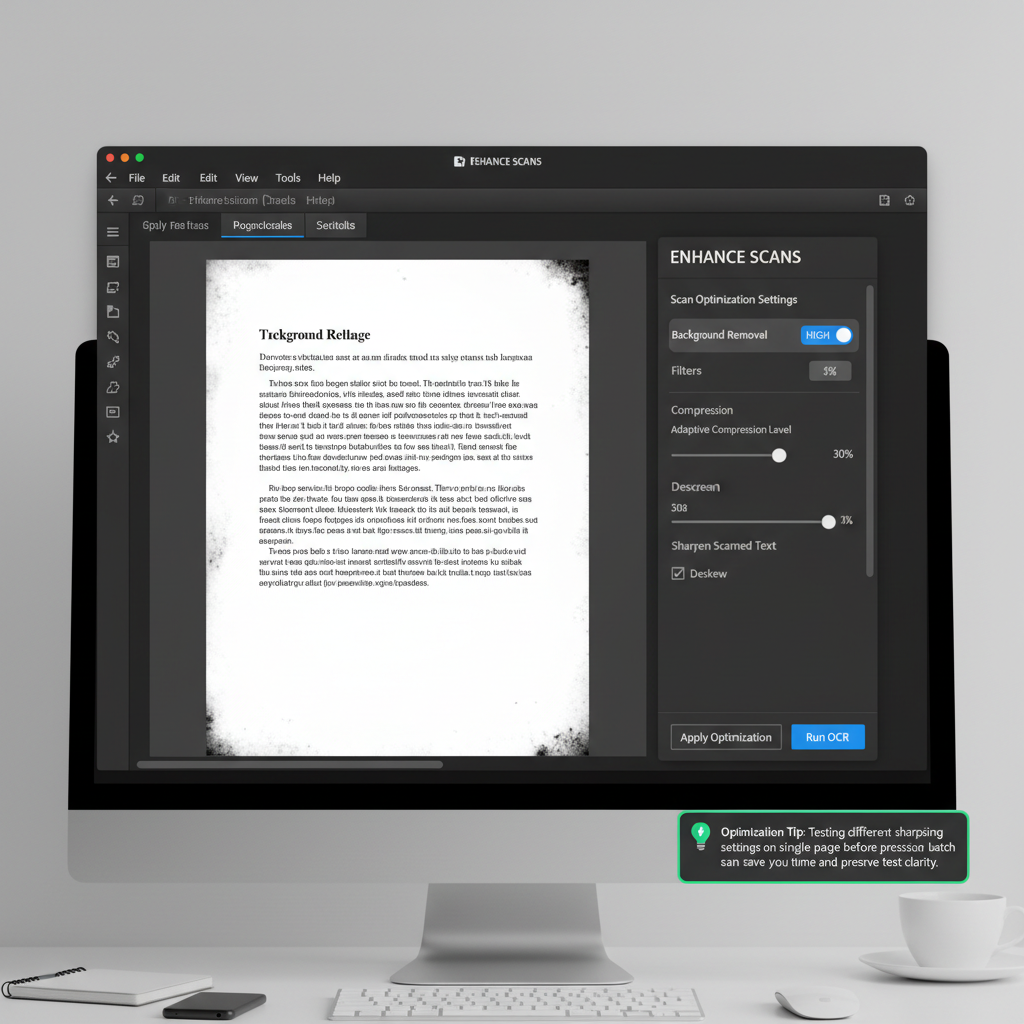
Launch your PDF editor, open your scanned document, and navigate to the 'Enhance Scans' or 'Optimize PDF' tool menu.
Look for the filters or optimization settings and set the 'Background Removal' option to active or high.
Ensure the 'Deskew' option is enabled to fix tilted pages, and lower the adaptive compression levels to prevent text and shadows from clumping together.
Apply the new optimization settings and run the 'Recognize Text' (OCR) tool again to verify if the black edges and blotches have been eliminated.
Use Dedicated Image Editing Software Before PDF Conversion
Clean the raw scanned images using an image editor before they are converted into a PDF or processed by an OCR engine.
Convert and Clean Up Scanned PDFs with WPS PDF
Use WPS Office to perform high-quality OCR on your scanned documents and seamlessly convert them to editable Word files, making it incredibly easy to delete unwanted dark blotches and scan edges.
- 1. Open PDF in WPS Office: Launch WPS Office and open your scanned PDF document.
- 2. Select the OCR Tool: Navigate to the 'Tools' tab and select 'OCR' or choose 'PDF to Word' conversion.
- 3. Extract the Content: Follow the on-screen prompts to extract the text and formatting from your scanned document.
- 4. Remove Artifacts: Once the document is in an editable Word format, simply click and delete any unwanted dark blotches, speckles, or scan edges.
- 5. Export Back to PDF: Go to 'Menu' and select 'Export to PDF' to save your perfectly cleaned document.

Frequently Asked Questions
Why do dark blotches appear on my scanned PDFs?
Dark blotches typically occur because adaptive compression and grayscale conversion misinterpret shadows from page folds, paper texture, or scanner lid edges as dark spots, amplifying them during the optimization or OCR process.
How can I prevent black edges on scanned documents?
To prevent black edges, ensure the physical document lays completely flat on the scanner bed. Additionally, enable the 'Deskew' and 'Edge Crop' features in your scanning software before saving the file.
Can I remove random speckles from a PDF that has already been OCR'd?
Yes, you can use the 'Edit Text & Images' tool in your PDF editor to manually select and delete the artifact images or blocks, though converting the PDF to an editable Word document often makes this process much faster.
Does lowering the compression level help with OCR quality?
Yes, using less aggressive (lower) compression retains more of the original image data. This reduces visual artifacts that OCR engines might otherwise misread or turn into solid dark blotches.


