

How to Remove the Extra Document Name Column from Acrobat Form Data

Question details
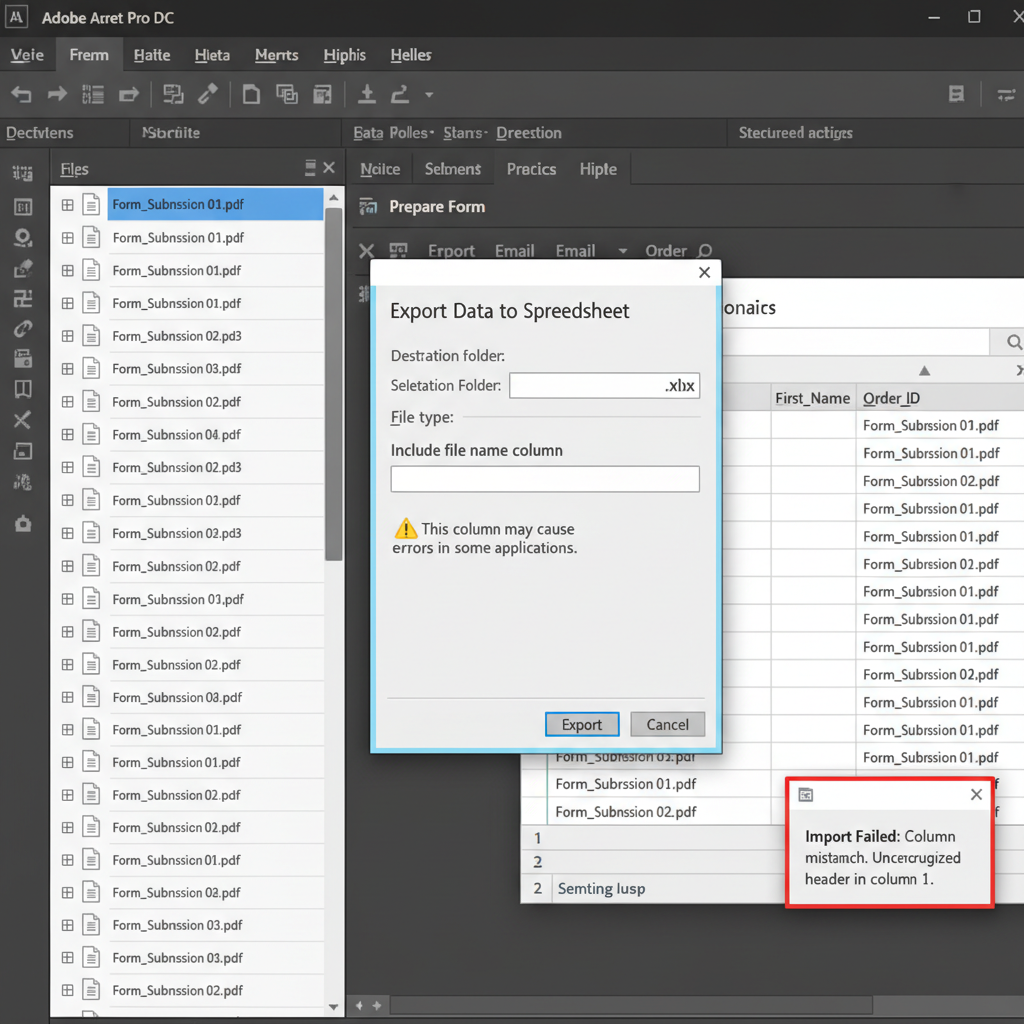
The user needs a way to prevent or remove the extra, unlabeled document name column that is generated when exporting PDF form data to a spreadsheet.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Merging multiple PDF form data submissions into a single spreadsheet for automated importing into another database or application.
- Observed behavior
- Acrobat automatically adds an unlabeled first column containing the document name to the exported spreadsheet, causing automated imports to fail because the column does not match any defined field header.
Ensure you know the exact file format (such as CSV or XLSX) and the specific column headers required by your automated import system before modifying the exported data.
Preprocess the Exported Spreadsheet Manually
The most straightforward approach is to let Acrobat export the data normally, then open the resulting spreadsheet to delete the extra column before importing it into your target system.
If you are not comfortable writing custom JavaScript for Adobe Acrobat, handling the cleanup in a spreadsheet application is highly reliable and takes only a few seconds.
Launch your spreadsheet application (such as WPS Spreadsheet or Microsoft Excel) and open the merged data file exported from Acrobat.
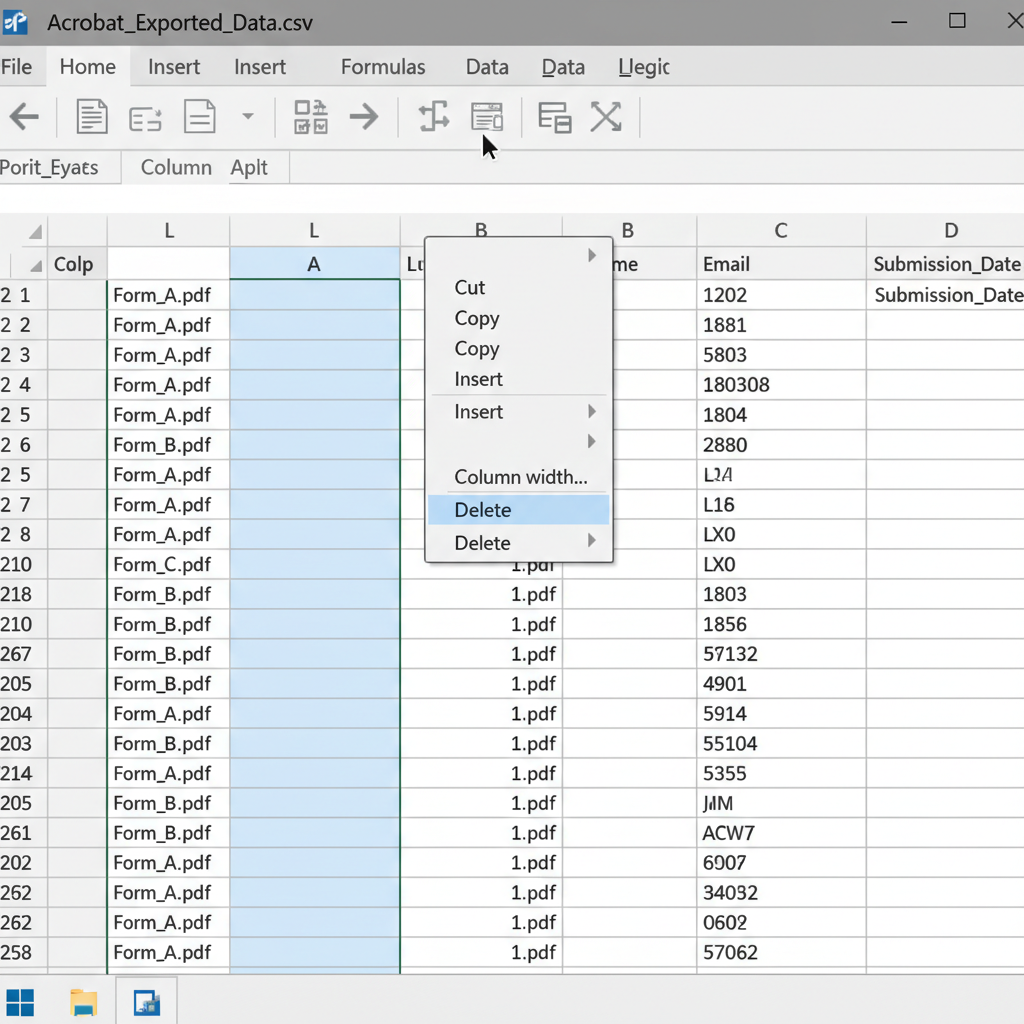
Identify the first column (typically Column A) that contains the PDF document names and has a blank or missing column header.
Right-click the column letter 'A' at the top of the worksheet and select 'Delete' from the context menu to remove the entire column.
Go to 'File' > 'Save' to overwrite the file, ensuring you keep the format (like CSV) required by your automated import system.
Use an Action Wizard Script in Acrobat
Automate the data extraction process within Acrobat by using a custom JavaScript action to bypass the default merging behavior.
Clean Up Your Form Data Easily with WPS Spreadsheet
WPS Office provides a powerful, free Spreadsheet tool that allows you to quickly remove unwanted columns from merged PDF data, ensuring your automated imports run smoothly.
- 1. Open WPS Spreadsheet: Launch WPS Office and open your merged form data file (CSV or XLSX).
- 2. Select the Extra Column: Click on the column header 'A' to highlight the unlabeled document name column.
- 3. Delete the Column: Right-click the highlighted header and select 'Delete' from the context menu.
- 4. Save the Cleaned Data: Click 'Save' or press Ctrl+S to keep the changes before importing the file into your automated system.

Frequently Asked Questions
Why does Acrobat add the document name column when exporting form data?
By default, Acrobat includes the document filename in the first column of the merged dataset to help users identify exactly which specific PDF file each row of data originated from.
Can I disable the document name column directly in Acrobat's export settings?
No, Adobe Acrobat does not currently offer a built-in toggle or checkbox in the standard export dialog to exclude the document name column. It must be removed manually after export or bypassed using a custom script.
Will deleting the first column affect the rest of my form data?
No, deleting the unlabeled document name column will only shift the remaining data columns to the left. As long as your automated import system relies on the remaining correct field headers, the import will succeed.
What format should I save the spreadsheet in after removing the column?
You should save the file in the format specifically required by your automated import system. This is typically a CSV (Comma Separated Values) file, which strips out formatting and leaves only the raw text data.


