

How to Search for Text on a Specific PDF Page with JavaScript

Question details
The user wants to find specific words (such as Fax, AutoFax, or Facemili) exclusively on the first page of a PDF file using Acrobat JavaScript.
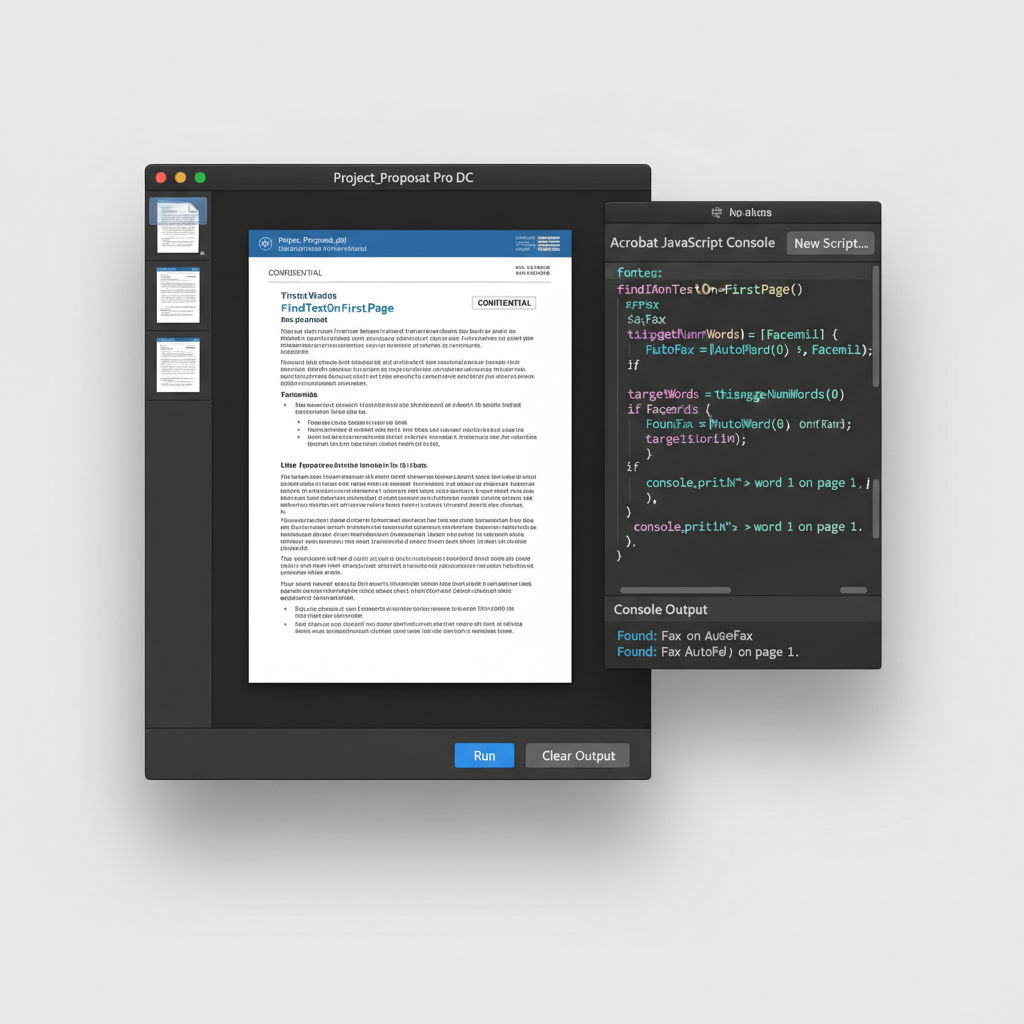
- Product
- Adobe Acrobat / PDF
- Device & OS
- not provided
- Scenario
- Automating text extraction or verification on specific pages of a PDF document using scripts.
- Observed behavior
- Needs a programmatic method to loop through and identify target words on a specific page index.
Ensure your PDF document contains searchable text. If your PDF is a scanned image, you must perform OCR (Optical Character Recognition) first, as JavaScript cannot read text from flat images.
Use the getPageNthWord Method in Acrobat JavaScript
Write a JavaScript loop using Acrobat's built-in getPageNthWord method to retrieve and evaluate words on a specific page index.
Acrobat's JavaScript API allows you to extract text word-by-word from specific pages using the Document object. By targeting a specific page index, you can limit your search scope and improve processing efficiency.
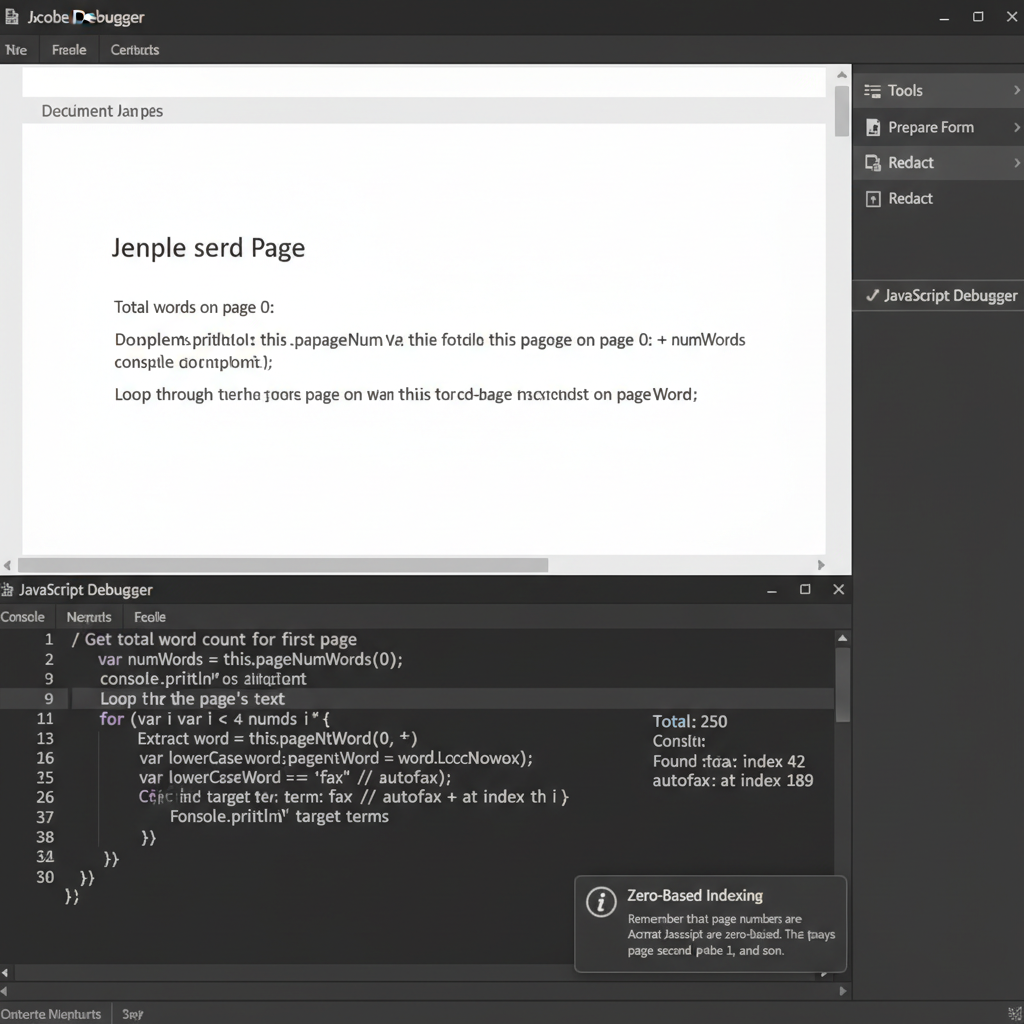
Launch your PDF in Adobe Acrobat, navigate to the Tools menu, select JavaScript, and open the Document JavaScripts or the JavaScript Debugger.
Use the script var numWords = this.getPageNumWords(0); to determine how many words exist on the first page. Note that the first page is index 0.
Set up a standard for loop ranging from i = 0 up to numWords - 1 to systematically check every word on that specific page.
Inside the loop, retrieve each word using var word = this.getPageNthWord(0, i);. Convert the extracted word to lowercase and compare it against your target terms (e.g., 'fax', 'autofax').
Find Text Instantly with WPS PDF
Skip the complex JavaScript coding. WPS PDF provides an intuitive Search panel and built-in OCR tools to help you find specific words on any page instantly.
- 1. Open your PDF file: Launch WPS Office and open your PDF document.
- 2. Activate the Search panel: Press the Ctrl+F shortcut on your keyboard to bring up the Search pane on the side.
- 3. Enter target words: Type your target word (e.g., "Fax") into the search bar. You can click the settings gear to match whole words or toggle case sensitivity.
- 4. Browse results by page: The search results are neatly categorized by page numbers, allowing you to quickly verify if the word appears on the first page.

Frequently Asked Questions
Why does getPageNthWord fail to find text in some PDFs?
If the PDF is created from a scanner or saved as an image, it lacks a readable text layer. You must use OCR (Optical Character Recognition) to convert the images to searchable text before running your JavaScript code.
How do I make my JavaScript text search case-insensitive?
Append the .toLowerCase() method to the string returned by getPageNthWord, and compare it against the lowercase versions of your target keywords.
Can I extract the exact coordinates of the found text?
Yes, Acrobat JavaScript provides the getPageNthWordQuads method, which returns the geometric coordinates (quadrilaterals) of the specified word on the page, allowing you to highlight or add fields over the text.


