

How to Search Multiple PDF Files on a Website Server
Question details
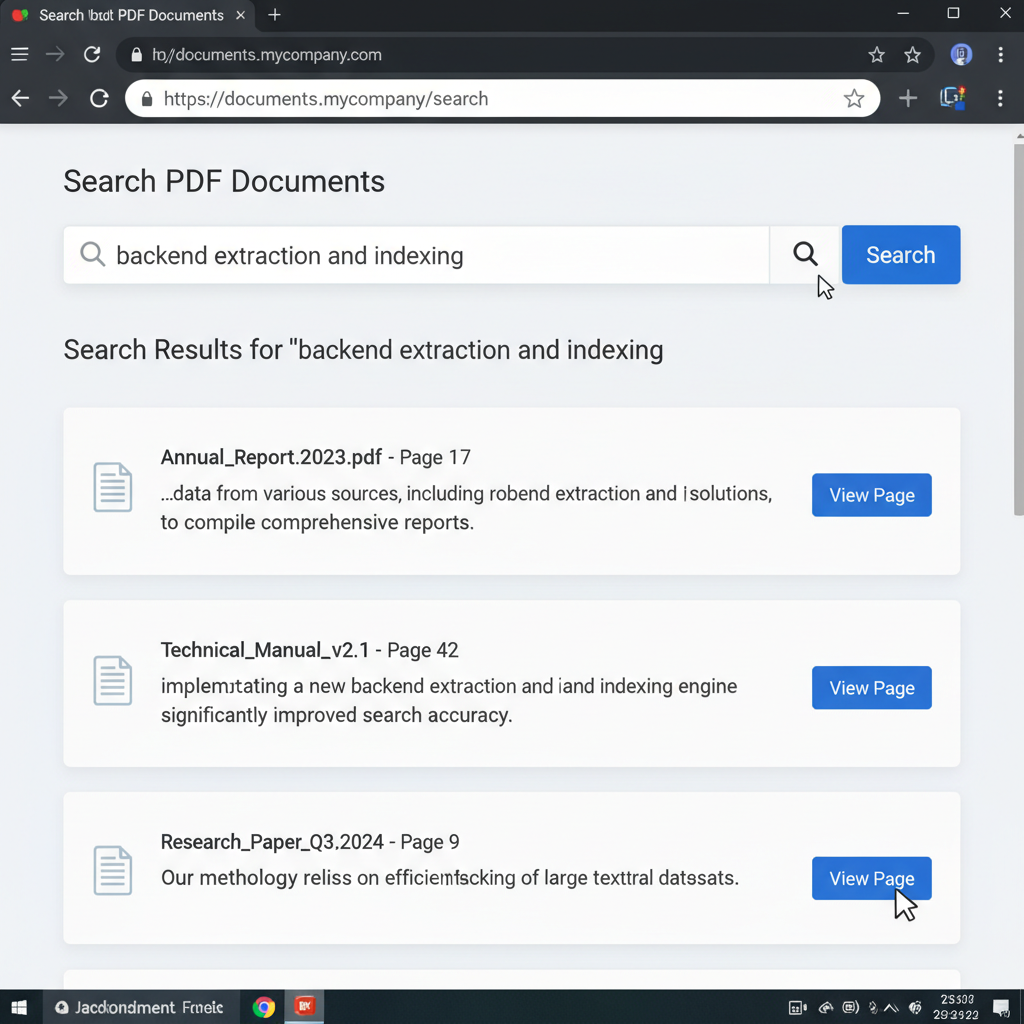
The user needs to create an HTML search box that queries multiple server-hosted PDF files, displays text matches, and opens results to the exact page without relying on Google indexing.
- Product
- Device & OS
- not provided
- Scenario
- Building a custom server-side website search function for hosted PDF documents.
- Observed behavior
- Needing a robust backend extraction and indexing solution because local PDF index files do not work for hosted web environments.
Ensure all your PDF files contain a readable text layer. If you are working with scanned documents, you must run an OCR (Optical Character Recognition) process on them before attempting to extract and index their text.
Build a Server-Side PDF Search Index
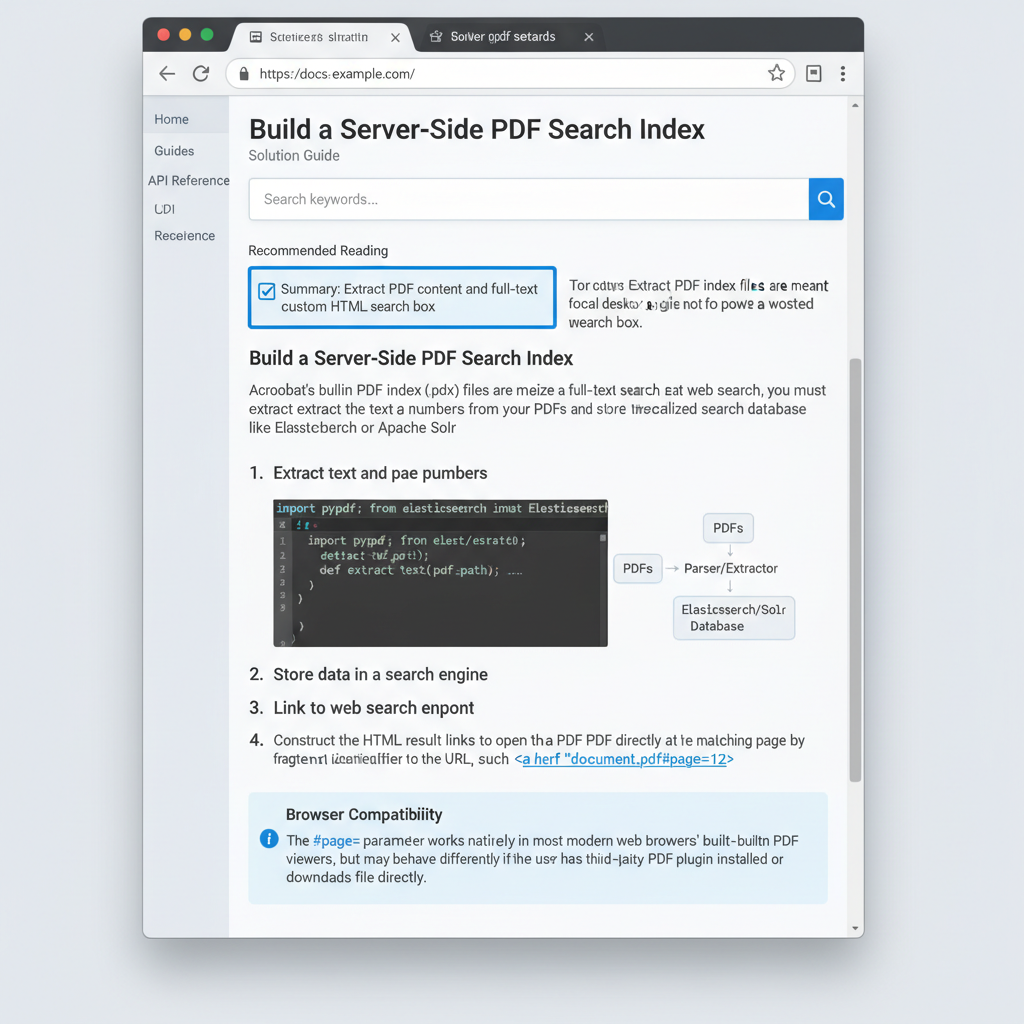
Extract PDF content and utilize a full-text search engine to power a custom HTML search box.
Acrobat's built-in PDF index (.pdx) files are meant for local desktop use, not for powering a hosted website search interface. To create a self-hosted web search, you must extract the text and page numbers from your PDFs and store them in a specialized search database like Elasticsearch or Apache Solr.
Use a backend programming library (such as Python's PyPDF2, PDFMiner, or a Node.js equivalent) to parse through your server's PDF directory and extract text strings alongside their corresponding page numbers.
Feed the extracted text and page metadata into a full-text search index such as Elasticsearch, Solr, or a relational database configured for full-text querying.
Develop a backend API endpoint that accepts search queries from your website's HTML search box and returns the matching document names and page numbers from your database.
Construct the HTML result links to open the PDF directly at the matching page by appending a fragment identifier to the URL, such as <a href="document.pdf#page=12">.
Prepare Searchable PDFs and Manage Local Files with WPS Office
Before uploading PDFs to your server for web indexing, ensure they have extractable text. WPS Office provides powerful OCR tools to convert scanned images into searchable PDFs, as well as a robust local document search feature to manage multiple files effortlessly.
- 1. Open your scanned PDF: Launch WPS Office and open the PDF file you intend to upload to your web server.
- 2. Run OCR to extract text: Navigate to the 'Tools' tab and select 'OCR'. Choose 'Convert to Searchable PDF' to generate a text layer.
- 3. Save the searchable file: Save the newly converted PDF. It is now ready for your server-side scripts to extract text and build the search index.

Frequently Asked Questions
Can I use Adobe Acrobat index files (.pdx) on my website?
No, Acrobat PDF index files are designed strictly for local or application-based searching. They cannot be used directly to power a web-based HTML search box on a server.
How do I link to a specific page in a PDF from my web search results?
You can use PDF Open Parameters by appending '#page=[pagenumber]' to the end of the PDF URL in your HTML anchor tag (for example, href="document.pdf#page=5").
Why aren't my server-side scripts finding text in some PDFs?
The PDFs might be scanned images without an underlying text layer. You must run OCR (Optical Character Recognition) on these files to make their text extractable for your search index.
What is the best database for indexing PDF content?
Dedicated search engines like Elasticsearch, Solr, or Apache Lucene are highly recommended because they are optimized for full-text search, ranking, and keyword highlighting across large document datasets.


