

How to Search Multiple Scanned PDFs Using OCR

Question details
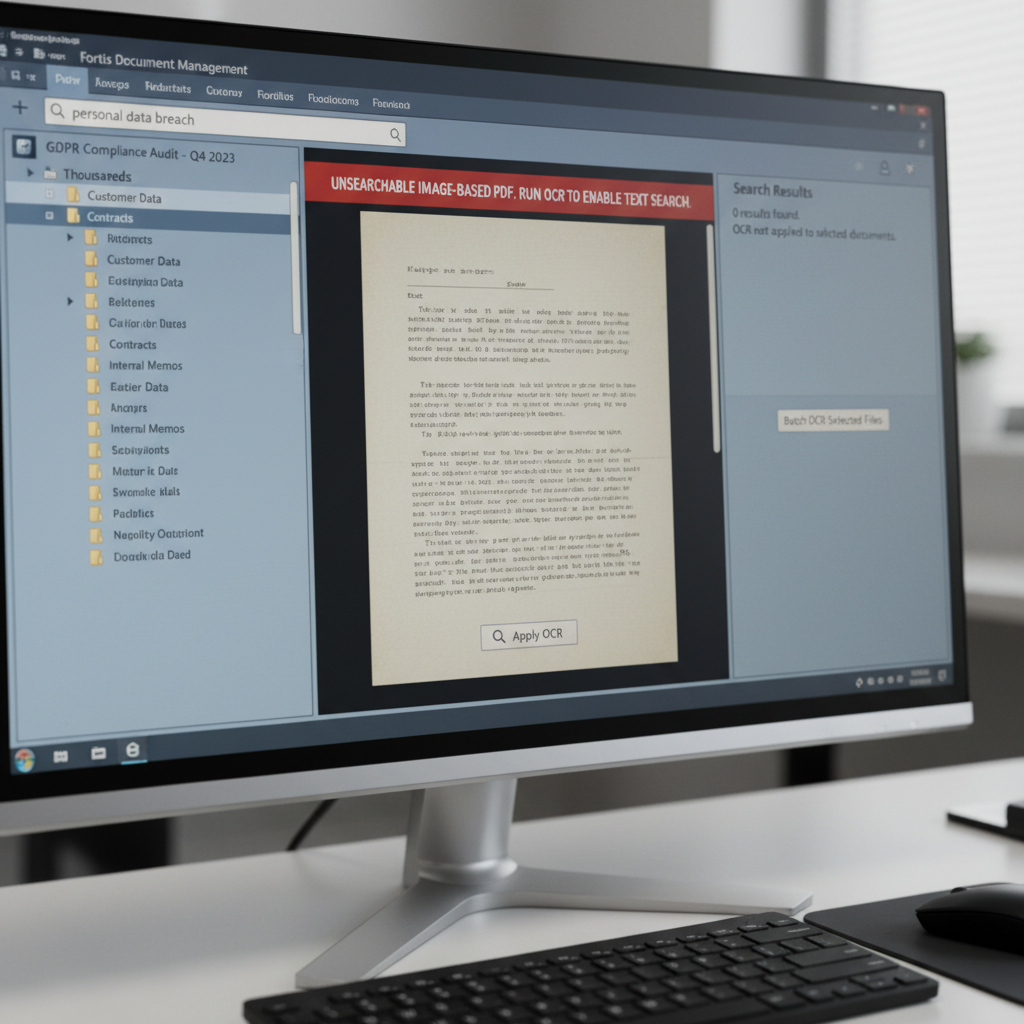
The user needs to search through thousands of scanned PDFs in a document management system for specific information, but the files are currently unsearchable images lacking OCR.
- Product
- Adobe Acrobat / Fortis Document Management
- Device & OS
- not provided
- Scenario
- Searching for potentially sensitive information across multiple scanned PDF documents for GDPR compliance without migrating the entire database.
- Observed behavior
- The PDFs are scanned as flat images and cannot be searched for text until Optical Character Recognition (OCR) is applied to the files.
Ensure you have adequate storage space on your local or network drive to temporarily export the batches of scanned PDFs before running the text recognition process.
Export and Run Batch OCR on Scanned PDFs
Use this method to export documents from your management system and apply text recognition to multiple files simultaneously.
PDFs that consist only of scanned images do not contain readable text. To search them, you must first convert the images to text using Optical Character Recognition (OCR).
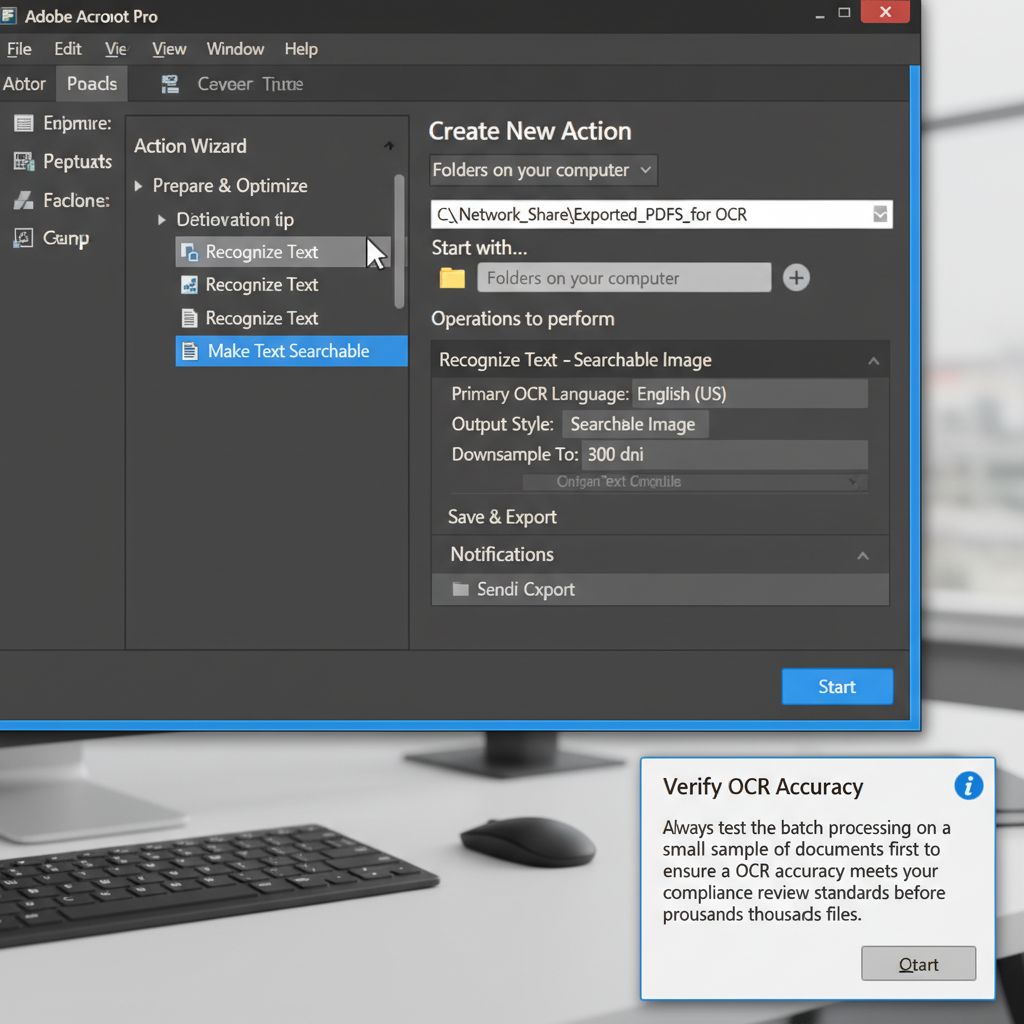
Export the target batches of scanned PDFs from your Fortis document management system to a dedicated Windows network folder.
Open Adobe Acrobat and access the 'Action Wizard' tool to set up a batch processing routine.
Select the 'Recognize Text' or 'Make Text Searchable' action and apply it to the network folder containing your exported PDFs.
Execute the batch process to convert the scanned images into searchable text. Once complete, use the advanced search feature (Ctrl+Shift+F) to query your required terms across the entire folder.
Use WPS Office to Batch OCR and Search Scanned PDFs
WPS Office provides a comprehensive PDF toolkit with built-in OCR capabilities. You can easily extract text from scanned images, make multiple PDFs searchable, and quickly find the information you need without complex configurations.
- 1. Open WPS PDF: Launch WPS Office and navigate to the PDF tool tab.
- 2. Select the OCR tool: Click on the 'OCR' tool located in the top menu toolbar.
- 3. Import your scanned PDFs: Drag and drop or import your batch of scanned PDF files into the OCR workspace.
- 4. Convert to searchable text: Choose the 'Convert to Searchable PDF' option and start the text extraction process.
- 5. Search across documents: Use the built-in search functionality to find your required keywords across the newly processed documents.

Frequently Asked Questions
Why can't I search text in my scanned PDF?
Scanned PDFs are essentially flat photographs of documents. Without applying Optical Character Recognition (OCR), the PDF reader cannot identify the individual letters and words to perform a text search.
Can I run OCR on multiple PDF files at once?
Yes, professional PDF editors like WPS Office and Adobe Acrobat offer batch processing features that allow you to apply OCR to an entire folder of PDFs simultaneously.
Does OCR work perfectly on all scanned documents?
OCR accuracy depends heavily on the quality of the original scan, the font type, and the document's condition. It is highly recommended to enhance or optimize the scans before running OCR to improve text recognition.
Do I need to migrate my document database to make PDFs searchable?
Not necessarily. You can export batches of documents to a local or network folder, process them with OCR, and perform your searches externally without altering your core database structure immediately.


