

How to Split a PDF Automatically Using Repeated Text or Keywords

Question details
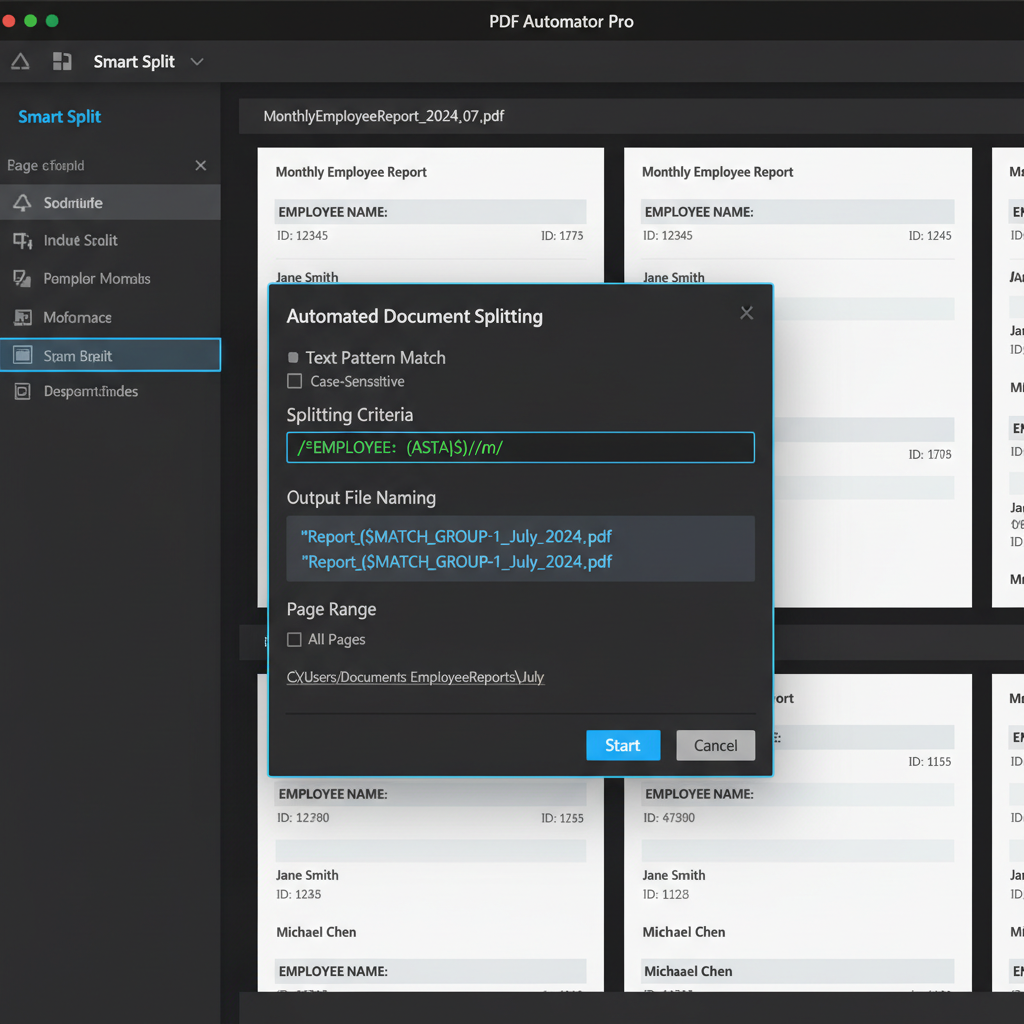
The user wants to split a multi-page PDF document automatically based on specific repeated text patterns or names and save each extracted section with a custom filename.
- Product
- Adobe Acrobat / PDF Editors
- Device & OS
- not provided
- Scenario
- Managing large recurring documents, such as monthly employee reports, by extracting individual sections based on specific text keywords.
- Observed behavior
- The user needs an automated scripting or software solution to separate and name PDF sections based on extracted text criteria, rather than splitting by simple page count.
Before attempting to split the document by text, ensure your PDF is text-searchable (run OCR if it is a scanned image) and create a backup copy of the original large PDF file to prevent accidental data loss.
Use Custom JavaScript in Adobe Acrobat to Split by Text
Because standard PDF splitters usually divide by page count or file size, splitting by specific text content requires a custom JavaScript tailored to your document's structure.
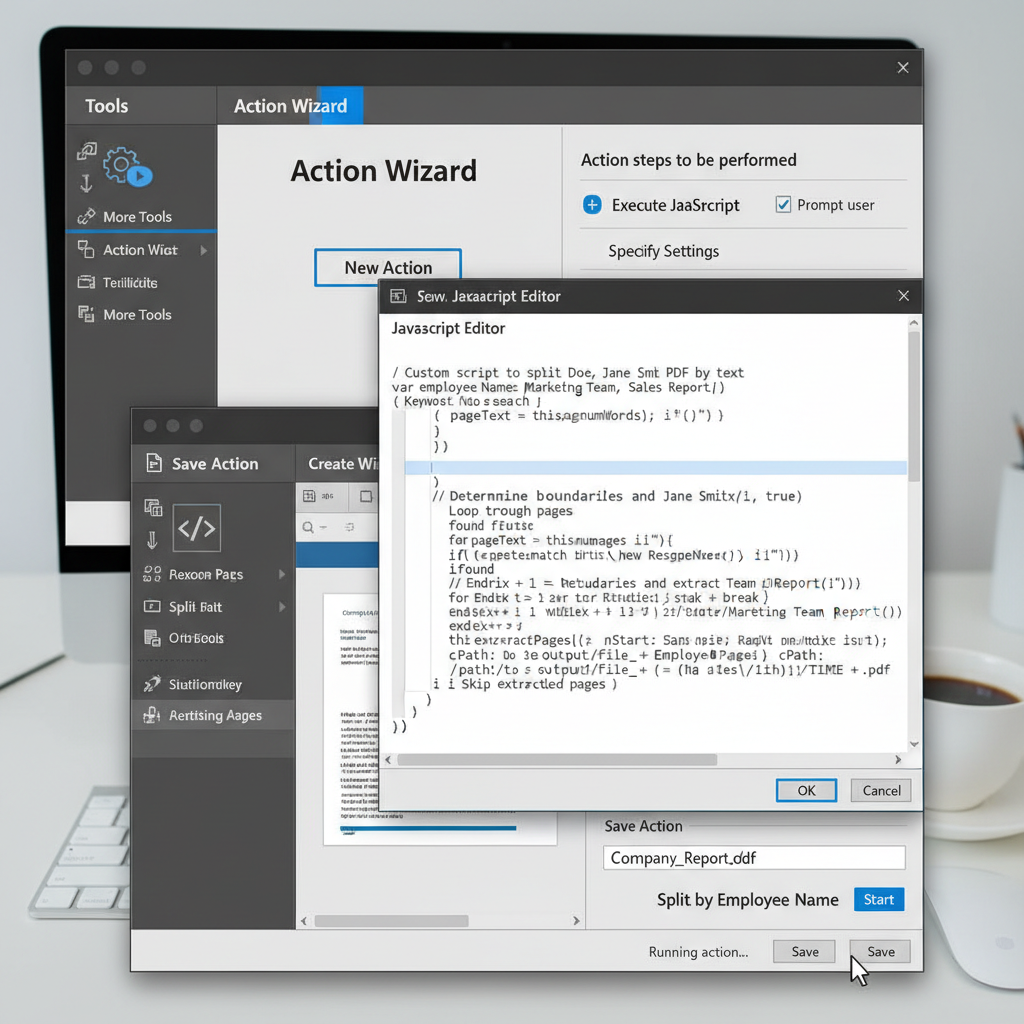
Adobe Acrobat allows you to run Action Wizard scripts or custom JavaScript to automate advanced tasks. You will need a script that loops through the pages, searches for specific keywords (like an employee name), determines the page boundaries for each section, and extracts those pages into a new file.
Launch Adobe Acrobat Pro, click on the 'Tools' tab, and select the 'Action Wizard' tool.
Click 'New Action' from the top toolbar, then navigate to the 'More Tools' section on the left panel and select 'Execute JavaScript'.
Click the plus icon to add the step, uncheck 'Prompt user', and click 'Specify Settings'. Paste your custom JavaScript code designed to extract text using getPageNumWords, match your desired keywords, and use extractPages to save the new files.
Save the action with a descriptive name, then run it on your target PDF file. The script will automatically process the text and generate the split PDF files into your designated folder.
Manually Split Using Bookmarks
If writing a custom script is not feasible, you can manually bookmark the target pages and use the built-in split tool to separate the PDF.
Easily Organize and Split Large PDFs with WPS Office
While splitting by specific text scripts requires advanced Adobe automation, WPS Office provides an intuitive, lightweight, and efficient way to search for keywords, add bookmarks, and extract PDF pages effortlessly.
- 1. Open the PDF File: Launch WPS Office and open your large, multi-page PDF document.
- 2. Identify Target Pages: Use the search function to locate the repeated text or keywords, and easily navigate to the sections you want to separate.
- 3. Navigate to the Split Function: Click on the 'Page' tab in the top ribbon and select the 'Split PDF' tool.
- 4. Configure and Extract: Choose to split the document by custom page ranges or equal parts, set your desired output directory, and click 'Split' to generate the separated files instantly.

Frequently Asked Questions
Can I split a PDF by keywords without using JavaScript?
Most standard PDF editors do not have a built-in 'split by text' feature. To achieve this without coding, you typically need to use third-party specialized PDF splitting software, or manually add bookmarks at each keyword location and split by those bookmarks.
What is the best way to name split PDF files automatically?
If you are using custom JavaScript in Acrobat, you can program the script to extract the target keyword (like the employee name) and use it as the filename variable when calling the save or extract function. Alternatively, splitting by top-level bookmarks allows you to use the bookmark text as the filename.
Does WPS Office allow me to split PDF files?
Yes, WPS Office includes a robust PDF editor that allows you to split large PDF files by page count, file size, or custom page ranges easily from the Page tab.
Why doesn't my PDF automation script find the target text?
Splitting by text heavily depends on the PDF's internal text layer structure. If the PDF was generated from a scanner or an image-based source, the script cannot read the text unless you perform Optical Character Recognition (OCR) first.


