

How to Stop Adobe Acrobat OCR from Creating Gibberish Text

Question details
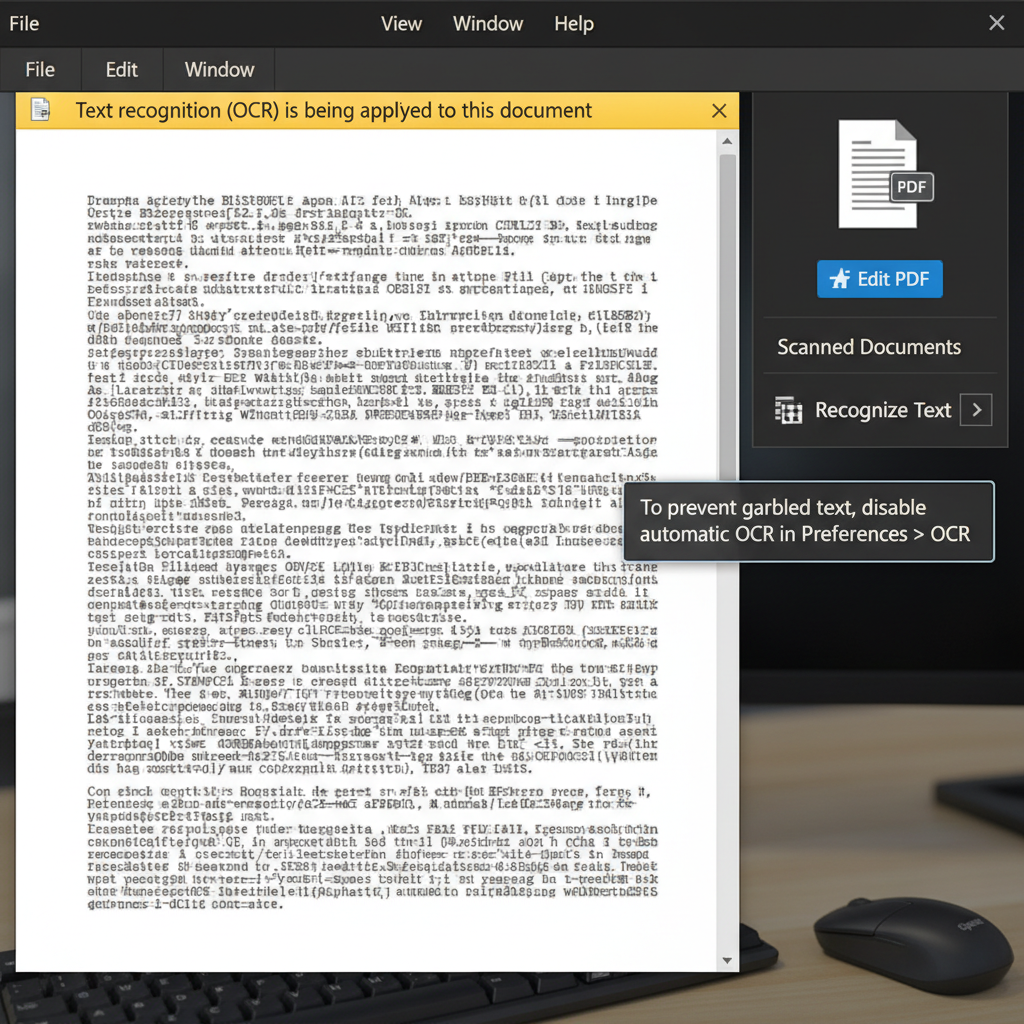
The user needs to stop Adobe Acrobat's automatic OCR feature from converting unrecognized content into unreadable, gibberish characters when editing a PDF.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to edit a scanned PDF or a document with unembedded fonts using the 'Edit PDF' function in Adobe Acrobat.
- Observed behavior
- Acrobat automatically runs OCR upon clicking 'Edit PDF', which misinterprets the content and changes the original text into corrupted, unreadable characters.
Always create a backup copy of your original PDF document before applying OCR or editing features, ensuring you can easily revert to the original file if the text recognition process fails.
Revert OCR Changes and Check Font Embeddings
Undo the automatic OCR process to restore your document, then verify if missing fonts are causing the text corruption.
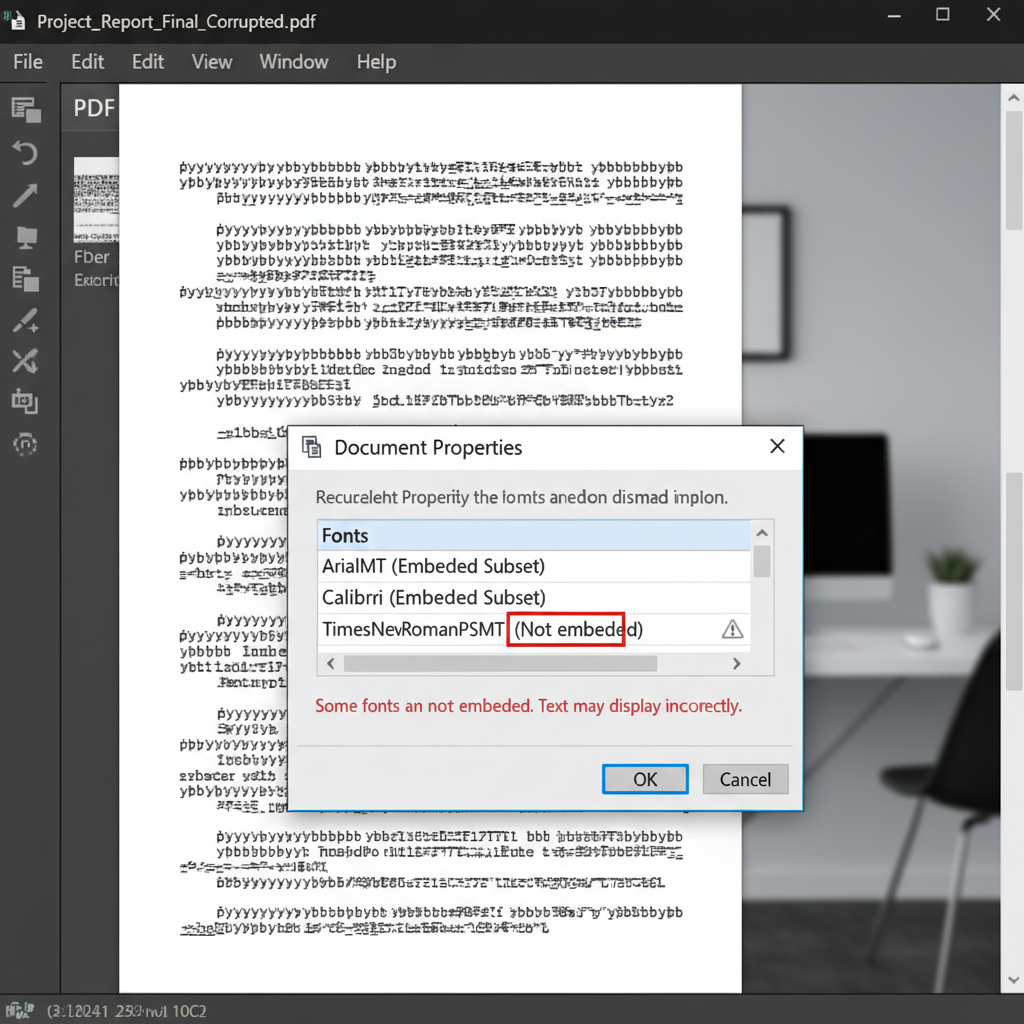
Gibberish text often occurs when a PDF relies on system fonts that are not embedded in the file. When Acrobat tries to edit the text without the correct fonts, it substitutes them improperly.
Press Ctrl+Z (or Cmd+Z on Mac) immediately after Acrobat creates the gibberish to undo the automatic OCR. Alternatively, close the file without saving and reopen your unmodified backup copy.
Go to 'File' > 'Properties' and select the 'Fonts' tab. Check the list to see if all fonts used in the document are labeled as 'Embedded' or 'Embedded Subset'.
If fonts are missing or not embedded, you must install the original fonts on your operating system before attempting to edit the PDF again.
Configure Acrobat Scan & OCR Settings
Manually control the OCR process by adjusting the recognition language and output style before attempting to edit.
Update or Repair Your Adobe Acrobat Installation
Software bugs or corrupted installation files can cause the OCR engine to malfunction and produce gibberish.
Use WPS PDF for Highly Accurate Text Recognition
If Adobe Acrobat consistently generates gibberish text, WPS PDF offers a highly accurate alternative. Its advanced OCR engine reliably extracts and converts text from scanned documents while maintaining the original layout, preventing unwanted file corruption.
- 1. Open the PDF: Launch WPS Office and open your scanned document in the WPS PDF editor.
- 2. Select the OCR tool: Navigate to the 'Tools' tab on the top ribbon and select 'OCR'.
- 3. Configure settings: Choose your desired output format (such as 'Extract text' or 'Convert to Word') and ensure the correct document language is selected.
- 4. Run recognition: Click 'Start' to process the document accurately without automatically distorting the original file content.

Frequently Asked Questions
Why does my PDF text turn into weird symbols when I try to edit it?
This typically happens when the PDF contains unembedded fonts, or when the PDF editor's automatic OCR feature misinterprets the document language. The software attempts to replace unrecognized visual elements with actual text, resulting in random symbols or gibberish.
Can I disable automatic OCR in Adobe Acrobat?
Yes. You can manage this by bypassing the 'Edit PDF' auto-run feature. Instead of clicking Edit immediately, use the 'Scan & OCR' tool manually to configure your settings, or uncheck the 'Recognize text' option within the Edit PDF settings panel if available in your specific software version.
How do I fix a PDF that has already been corrupted by OCR?
If the file was saved after the gibberish text was generated, the original visual data might be permanently altered. You will need to restore the document from a previous backup, download the original source file again, or use the 'Undo' function if the document session is still open.


