

How to Update an Acrobat OCR Index Without Reprocessing Existing Files

Question details
The user needs to routinely update an existing OCR search index to include only newly added PDF files, avoiding the need to reprocess a massive 600 GB database of existing documents.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Managing a large computer filing system with hundreds of gigabytes of PDFs that require routine search index updates as new files are added.
- Observed behavior
- Creating a completely new index forces the software to re-scan and reprocess all 600 GB of existing data, which is highly inefficient and time-consuming.
Ensure that all newly added PDF files are saved within the specific folder directories already defined in your existing Acrobat catalog. It is highly recommended to run OCR text recognition on any new scanned documents before updating the index.
Update the Existing Acrobat Catalog Index
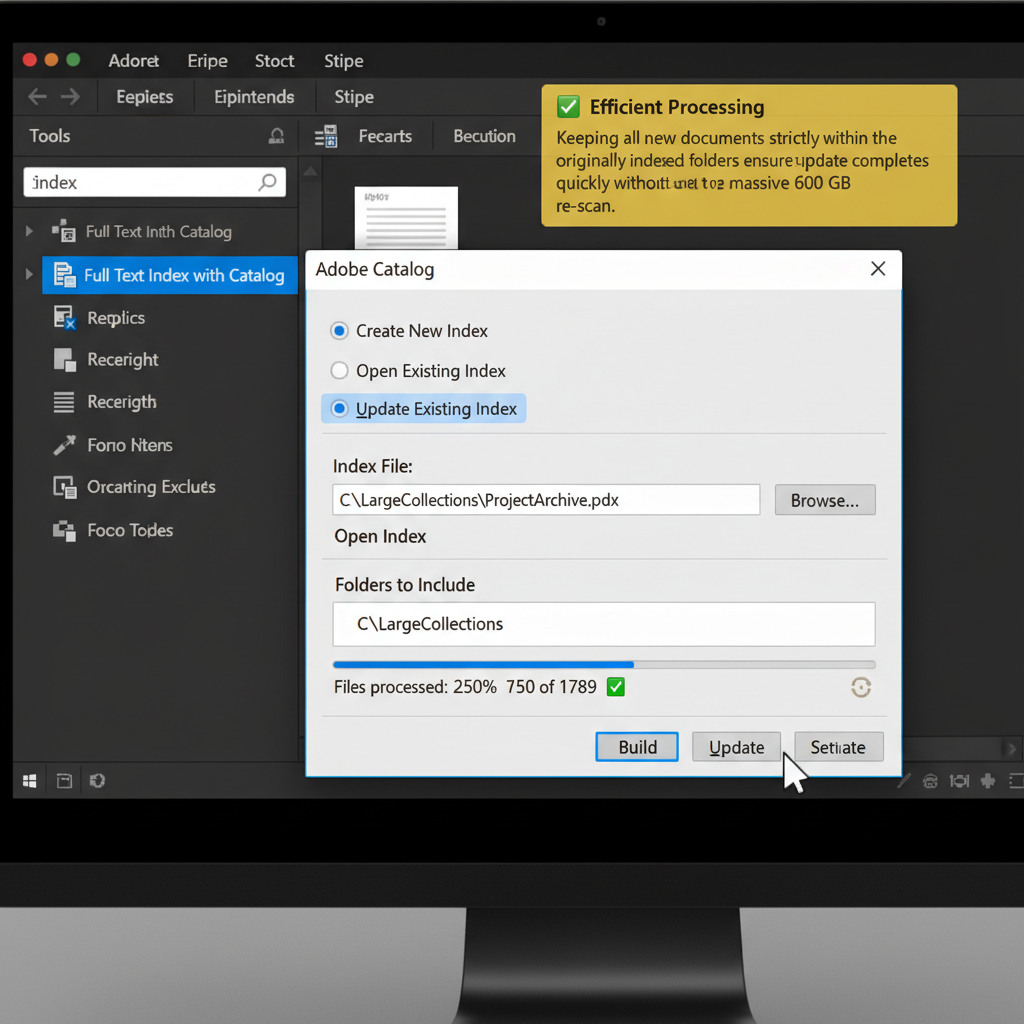
Use the Acrobat Catalog feature to update your existing index file (.pdx) so it only processes new or modified files rather than scanning the entire collection.
By defining a folder collection and updating its existing catalog, Acrobat intelligently skips unchanged documents. This method is essential for managing large databases efficiently.
Launch Adobe Acrobat Pro. Navigate to 'Tools', find the 'Index' tool (or search for it in the tools pane), and select 'Full Text Index with Catalog'.
Click on 'Open Index' in the Catalog dialog box. Browse your computer filing system to locate and select your existing .pdx index file that manages the 600 GB folder collection.
Instead of creating a new index, choose the 'Update' or 'Rebuild' option. Acrobat will now scan the defined directories but will only append data from files that have been added or modified since the last index build.
If you are adding newly scanned image PDFs, you must manually run the 'Recognize Text' (OCR) tool on those specific new files before running the catalog update. The indexer catalogs existing text; it does not perform OCR automatically.
Discover a Faster Way to Manage PDFs and Office Documents
Managing massive PDF catalogs in heavy applications can be resource-intensive and costly. WPS Office provides a free, lightweight, and highly compatible alternative. With an intuitive interface, you can effortlessly handle PDFs, perform OCR, and seamlessly edit Word, Excel, and PowerPoint documents all in one suite.
- 1. Download and Install: Visit the official WPS Office website to download the free all-in-one suite and install it on your device.
- 2. Open Your Documents: Launch WPS Office and drag-and-drop your PDFs, Word documents, or Excel spreadsheets directly into the unified workspace.
- 3. Utilize Advanced PDF Tools: Navigate to the PDF tab to extract text using OCR, merge files, or convert PDFs to editable Word documents instantly.

Frequently Asked Questions
Why does Acrobat reprocess all files when I try to update?
If you accidentally select 'New Index' or change the core directory structure, Acrobat assumes it needs to build the catalog database from scratch, forcing it to re-scan every file. Always open the existing .pdx file and choose 'Update'.
Do I still need to run OCR on the newly added PDF files?
Yes. The Acrobat Catalog indexing feature builds a searchable database based on existing text layers. If your newly added files are purely scanned images, you must run the Recognize Text (OCR) command on them before updating the index.
What exactly is a .pdx file?
A .pdx file is an Adobe Acrobat Catalog Index file. It stores a highly optimized, searchable database of text for a specific collection of PDF documents, enabling lightning-fast advanced searches across hundreds of gigabytes of data simultaneously.
Can I automate the index update process for large databases?
Yes, Adobe Acrobat Pro allows you to automate catalog updates using a BPDX (Batch PDX) file combined with your operating system's task scheduler, enabling routine updates of your 600 GB database overnight.


