

Why Adobe Acrobat DC Exports PDF Tables Incorrectly and How to Fix It

Question details
The user is trying to understand the root cause of formatting errors when extracting large tabular data from PDF files using Acrobat DC and needs a reliable workaround.
- Product
- Adobe Acrobat DC
- Device & OS
- not provided
- Scenario
- Exporting a large text-based PDF report containing complex tables into a spreadsheet or word processing format.
- Observed behavior
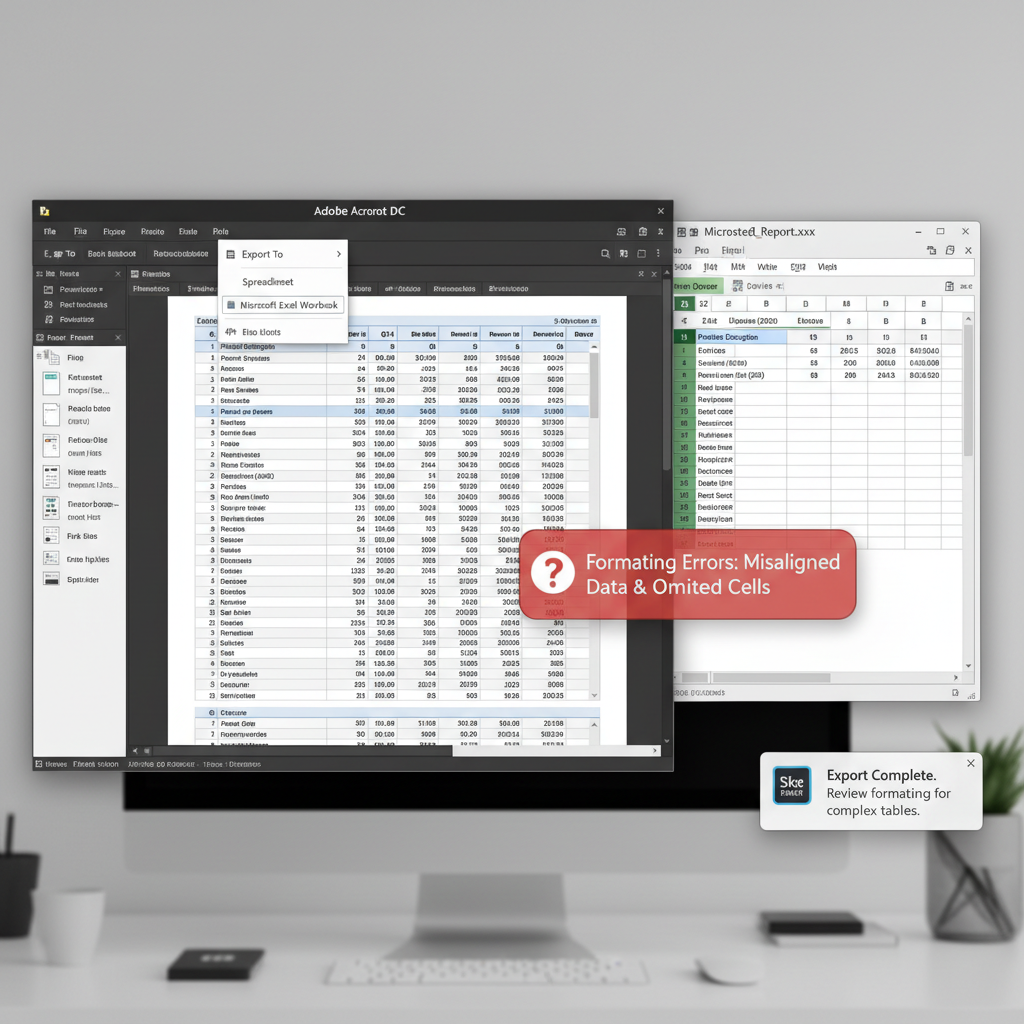
- The exported document displays misaligned columns, separated headings, and omitted cells because Acrobat processes internal PDF encoding rather than the visual table structure.
Before troubleshooting the PDF file, verify if you have access to the original source document or database export, as converting raw data directly is always more accurate than extracting from a finalized PDF.
Export a Specific Table Selection
Instead of converting the entire document, selecting and exporting only the problem table helps Acrobat focus on a smaller, defined grid, reducing the chance of misalignment.
PDF documents use internal coordinates to place text on a page. When Acrobat tries to export an entire page with headers, footers, and paragraphs mixed with tables, it can misinterpret the column boundaries.
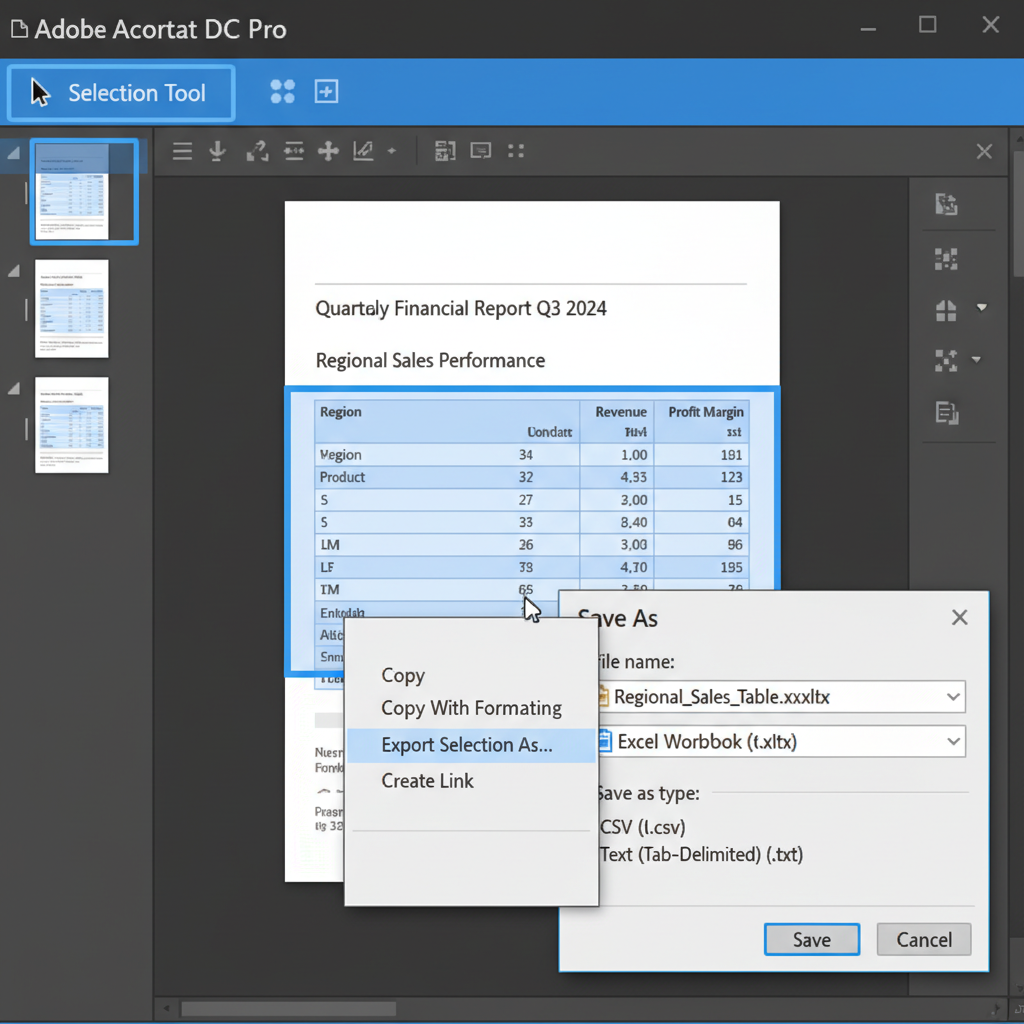
Open your document in Adobe Acrobat DC and select the 'Selection tool' (the arrow icon) from the top toolbar.
Click and drag your cursor to draw a box completely around the table you wish to extract, ensuring all columns and rows are highlighted.
Right-click anywhere inside the highlighted area and choose 'Export Selection As...' from the context menu.
Choose 'Excel Workbook' or 'CSV' from the 'Save as type' dropdown menu, select your destination folder, and click 'Save'.
Repair PDF Document Tags
Properly tagging a PDF gives Acrobat the structural blueprint it needs to identify rows and columns correctly during the export process.
Accurately Extract PDF Tables to Excel with WPS Office
Avoid misaligned columns and missing data cells. The built-in PDF to Excel converter in WPS Office uses advanced table-recognition algorithms to preserve your visual grids and seamlessly export them into editable spreadsheets.
- 1. Launch WPS Office: Open WPS Office on your computer and navigate to the 'PDF' tab on the home screen.
- 2. Open your PDF file: Click 'Open' and select the PDF report containing the tables you want to extract.
- 3. Select 'PDF to Excel': Click on the 'PDF to Excel' button located in the top conversion toolbar.
- 4. Convert and save: Set your desired page range and layout options in the dialog box, then click 'Convert'. The accurately formatted table will open directly in WPS Spreadsheet.

Frequently Asked Questions
Why does my PDF table look perfectly aligned on screen but export incorrectly?
PDFs are designed to preserve the visual appearance of a page by plotting text at specific X and Y coordinates. The file does not inherently 'know' it contains a table unless it includes structural tags. When exporting, the software reads the raw text coordinates, which can result in jumbled text if the columns aren't explicitly defined.
Can I prevent cells from merging when converting PDF to Excel?
Yes. Merged cells usually happen when the text in a PDF is packed tightly or crosses visual borders. Using a dedicated PDF conversion tool with advanced layout settings, or exporting a smaller selected area rather than the whole page, can significantly reduce unwanted cell merging.
Does flattening a PDF help with table extraction?
Flattening a PDF usually merges annotations and form fields into the base text layer. It generally does not improve table extraction and can sometimes make it worse by stripping out underlying structural data. It is better to rely on tagging or table-aware extraction tools instead.


