

Why Adobe Acrobat Standard 2017 Scans as Pictures and How to Fix It
Question details
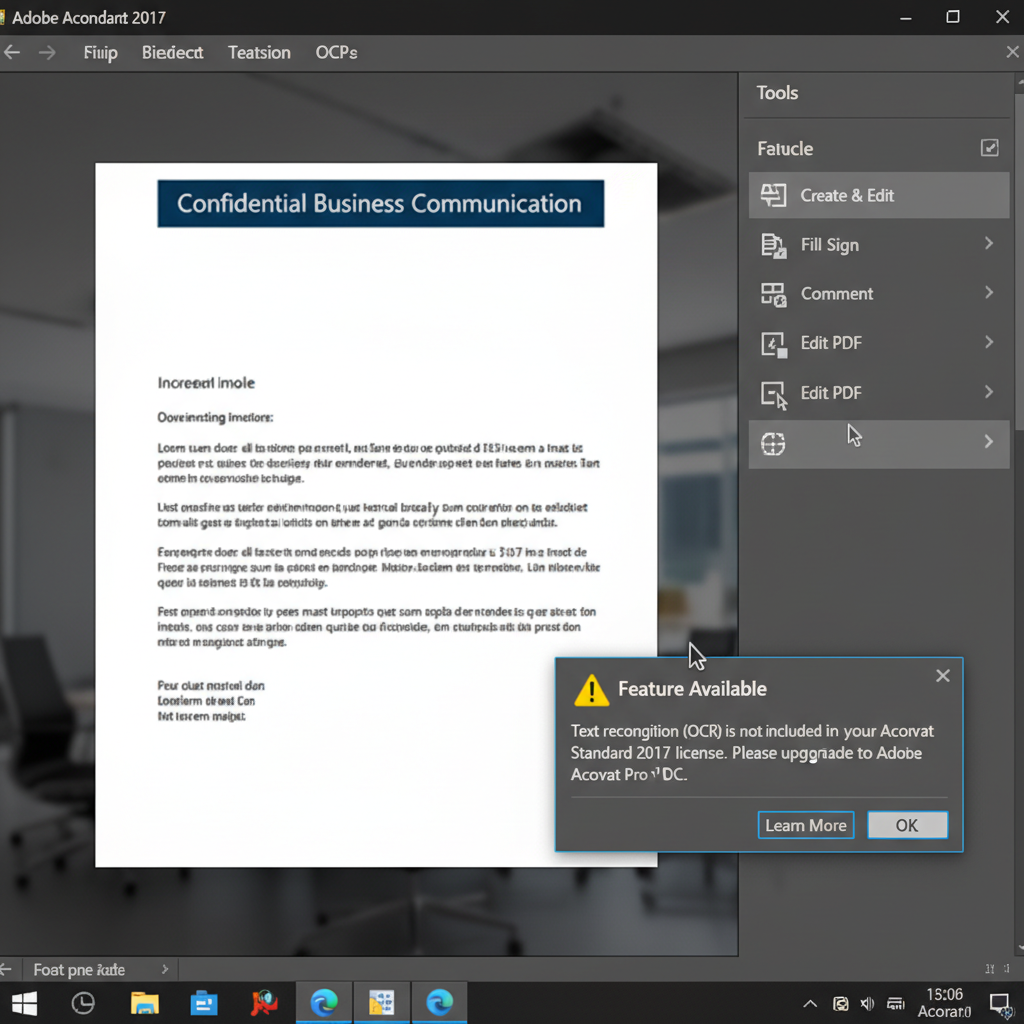
The user is experiencing an issue where Acrobat Standard 2017 only scans physical documents as flat images (pictures) and wants to know how to access missing features like text recognition (OCR).
- Product
- Adobe Acrobat Standard 2017
- Device & OS
- not provided
- Scenario
- Scanning physical documents into a digital PDF format using the software.
- Observed behavior
- The scanned output appears as a flat picture without selectable or searchable text, lacking OCR processing.
Ensure your scanner is securely connected to your computer and that you have installed the latest TWAIN or WIA drivers provided by your scanner manufacturer.
Run the Recognize Text (OCR) Tool on the Scanned Picture
Use the software's built-in OCR feature to convert an existing flat image scan into a document with selectable, searchable text.
If your document was already scanned as an image, you do not need to rescan it. You can force the software to analyze the picture and convert the recognizable letters into actual text using Optical Character Recognition (OCR).
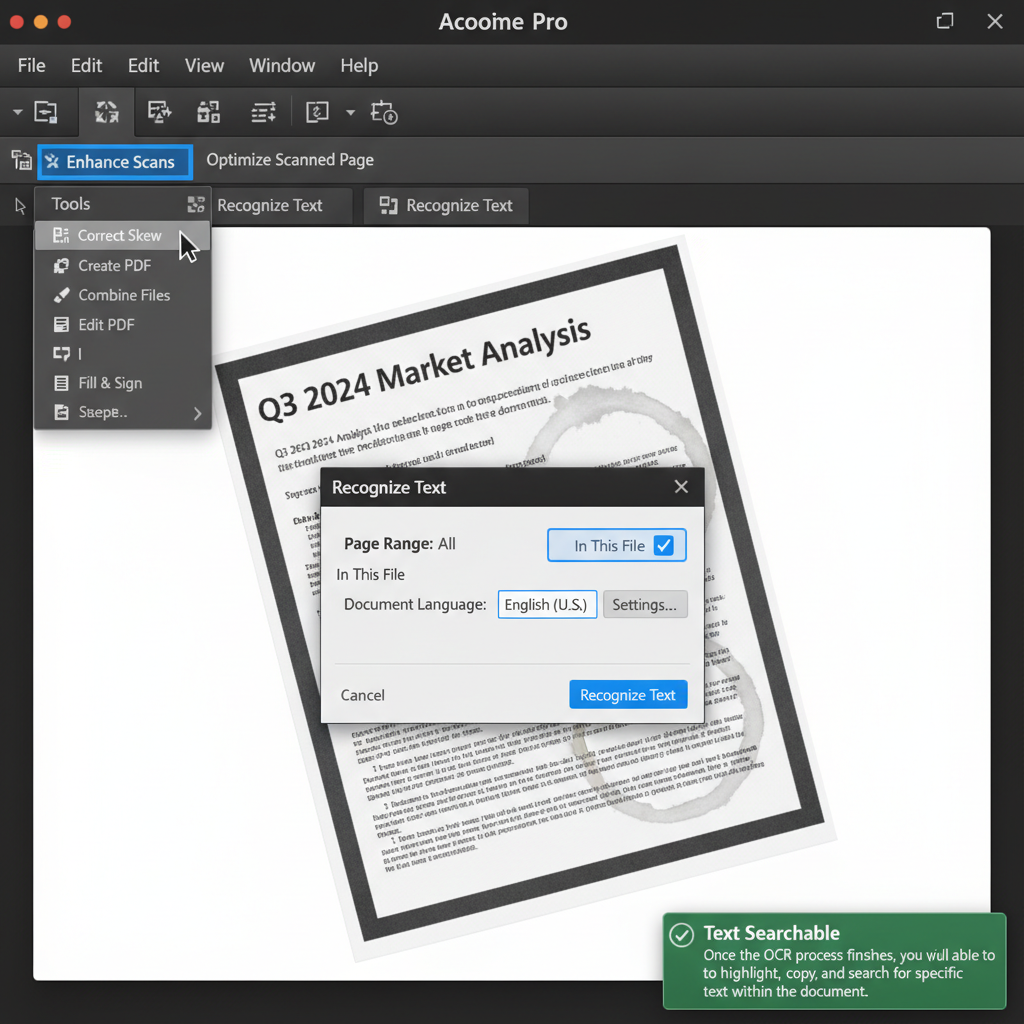
Open your scanned picture PDF. Go to the 'Tools' menu at the top of the window and click on 'Enhance Scans'.
In the secondary toolbar that appears, click on 'Recognize Text' and choose 'In This File' from the dropdown menu.
Click 'Settings' to ensure the correct document language is selected, then click the 'Recognize Text' button to process the image.
Adjust Scanner Settings to Run OCR During Scanning
Configure your scan profile to automatically run text recognition while the document is being scanned, avoiding the need to process it later.
Scan and Extract Text from Images with WPS Office
If you are struggling with complex scanner settings or missing text recognition features, WPS Office provides a powerful, built-in OCR tool that easily converts scanned pictures into editable, searchable PDF and Word documents.
- 1. Open WPS Office PDF: Launch WPS Office and open your scanned image or PDF file within the PDF editor.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Select extraction mode: Choose whether you want to extract the text to a plain text box or convert the entire document into an editable format.
- 4. Process and save: Confirm the document language and click 'Extract'. Save your newly searchable document to your device.
Frequently Asked Questions
Why does my scanner only scan as an image by default?
Many basic scanner drivers and default operating system scan profiles are configured to capture flat images (like JPEGs) for maximum performance and simplicity. To capture text, you must explicitly enable OCR (Optical Character Recognition) in your software settings or select a 'Document' profile instead of a 'Photo' profile.
Does Acrobat Standard 2017 include OCR features?
Yes. While Acrobat Standard lacks some of the advanced pre-flight and editing features of Acrobat Pro, it fully supports OCR capabilities. You can access these tools by navigating to the 'Enhance Scans' tool and selecting 'Recognize Text'.
What is the difference between TWAIN and WIA scanner drivers?
TWAIN drivers are provided by the scanner manufacturer and generally offer more advanced, customizable scanning controls. WIA (Windows Image Acquisition) is a basic driver provided by Microsoft. Using the TWAIN driver in your PDF software often unlocks better document scanning options.


