

Why You Cannot Copy Text from Some PDF Documents and How to Fix It

Question details
The user is unable to select or copy text from certain PDF files for searching, translation, or reuse.
- Product
- Device & OS
- not provided
- Scenario
- Attempting to copy text from a PDF document to paste into another application, translate it, or search for specific terms.
- Observed behavior
- The text selection tool does not highlight the words, or the copy function is grayed out and unavailable.
Ensure you are using a standard PDF reader and check if the document is visibly a scanned image rather than a digitally created text file.
Convert Scanned PDFs Using OCR
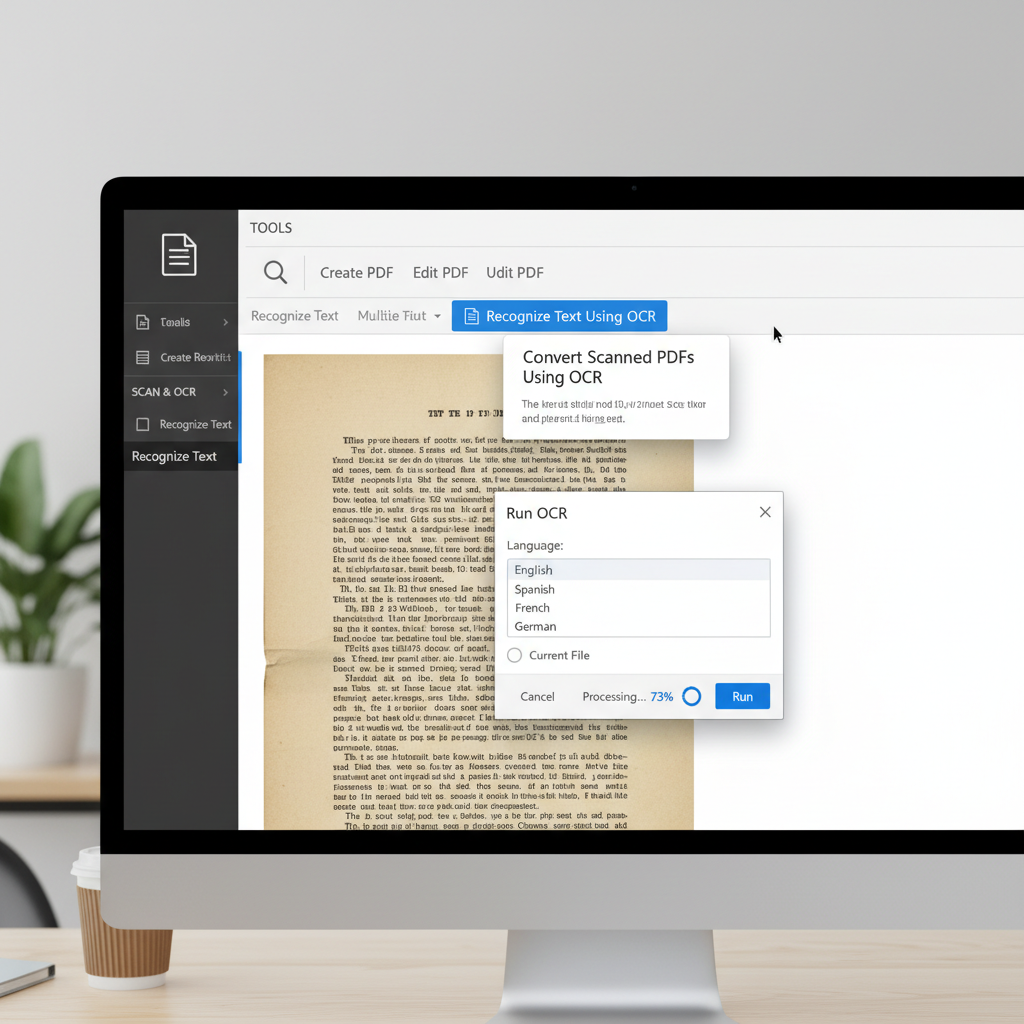
Use OCR (Optical Character Recognition) to convert image-based PDFs into selectable and copyable text.
Many PDFs are created by scanning physical documents. These files are essentially flat images, meaning standard text selection tools cannot recognize the characters without OCR processing.
Open the scanned PDF in your preferred PDF editor (such as Adobe Acrobat or WPS Office).
Find the 'OCR', 'Recognize Text', or 'Scan & OCR' tool in the main toolbar or tools menu.
Click to run the OCR process, selecting the appropriate language for the document to ensure accurate character recognition.
Once the OCR process is complete, use the standard selection tool to highlight and copy the newly recognized text.
Check and Address PDF Security Restrictions
Check if the document creator has restricted text copying and request permission if necessary.
Easily Extract and Copy Text from PDFs with WPS Office
WPS Office provides a powerful built-in OCR feature to quickly recognize text in scanned PDFs, as well as easy-to-use tools for managing PDF permissions and converting documents.
- 1. Open your PDF: Launch WPS Office and open your PDF file using WPS PDF.
- 2. Use the OCR tool: If it is a scanned document, click on the 'OCR' button located in the Home or Tools tab.
- 3. Extract text: Wait a few seconds for WPS to recognize the characters. You can extract the text directly or convert the file to a Word document.
- 4. Copy the content: Select the text you need and press Ctrl+C to copy it for reuse.

Frequently Asked Questions
How can I tell if a PDF is a scanned image or an actual text document?
Zoom in closely on the text. If the text edges look pixelated or blurry, it is likely a scanned image. Alternatively, try to highlight a single word; if the whole page is selected in a single large box instead, the document is an image.
Can I bypass PDF copying restrictions without a password?
Security restrictions are designed to protect the author's intellectual property and data. You should contact the author or owner for the password or an unrestricted copy rather than attempting to bypass the security settings with third-party unlocking tools.
Does converting a PDF to Word allow me to copy the text?
Yes, converting a standard PDF to Word makes the text editable and copyable. However, if the original PDF is a scanned image, you will still need a PDF converter that features OCR technology to accurately extract the text into the Word document.
Why does the copied text from my PDF look like random symbols or garbage characters?
This happens when the PDF has a corrupted or missing font encoding dictionary. The text appears normal on screen, but the underlying character map is broken. Using an OCR tool or taking a screenshot and extracting text from the image can work around this issue.


