



How to Use Positive and Negative Samples in Microsoft Purview Classifiers

Question details
Understanding the definitions and roles of positive and negative document samples when setting up trainable classifiers in Microsoft Purview.
- Product
- Microsoft Purview
- Device & OS
- not provided
- Scenario
- Configuring data protection rules and training a custom machine learning classifier to detect specific types of sensitive content.
- Observed behavior
- The user needs to know how to properly select and categorize training data to ensure the classifier accurately identifies target documents without false positives.
Before training your classifier in the compliance portal, ensure you have collected a sufficiently large and diverse set of sample documents organized into two distinct folders for positive and negative matches.
Categorize Your Training Documents
Effectively separate your data into positive and negative samples to train the Microsoft Purview classifier.
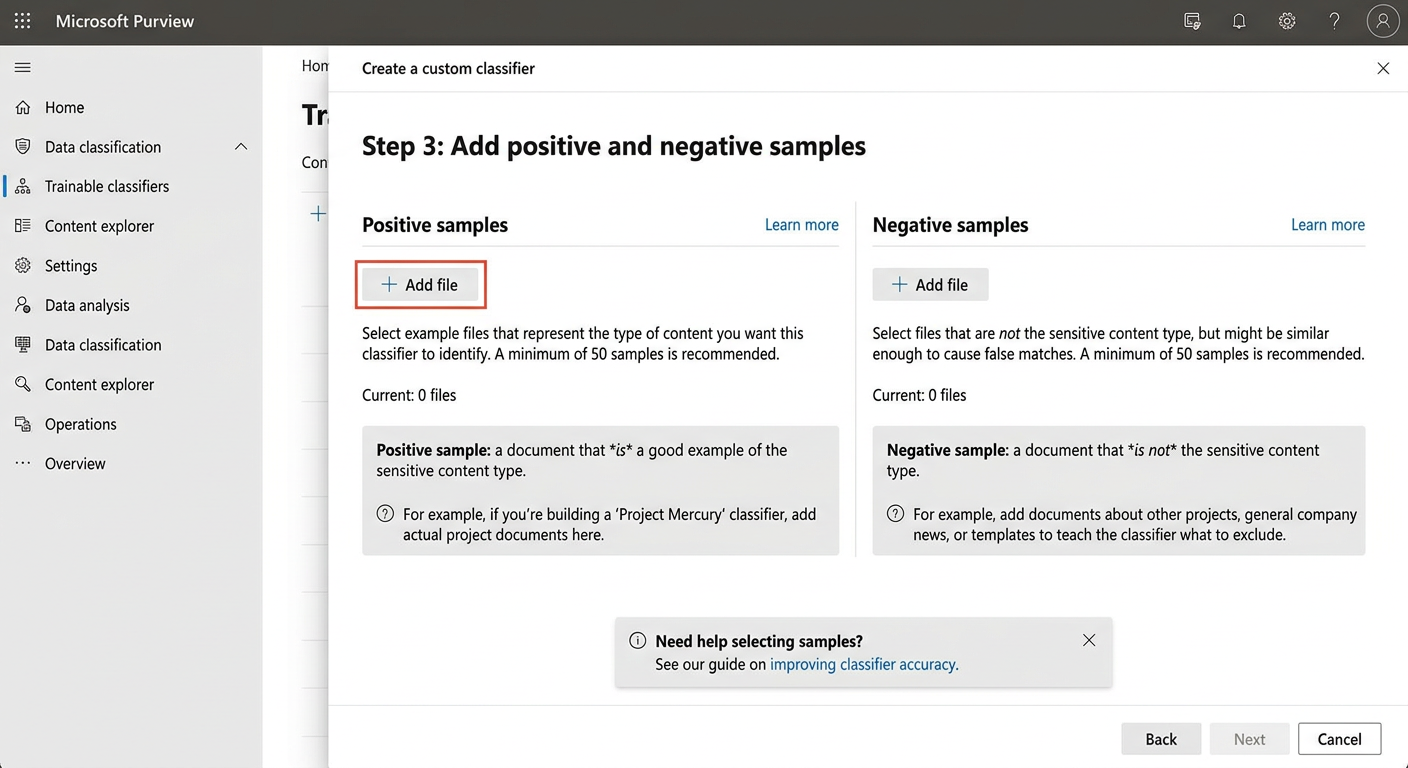
Trainable classifiers use machine learning to identify data types based on examples rather than exact text matches. To do this, the system needs clear examples of what you want to find (positive) and what you want it to ignore (negative).
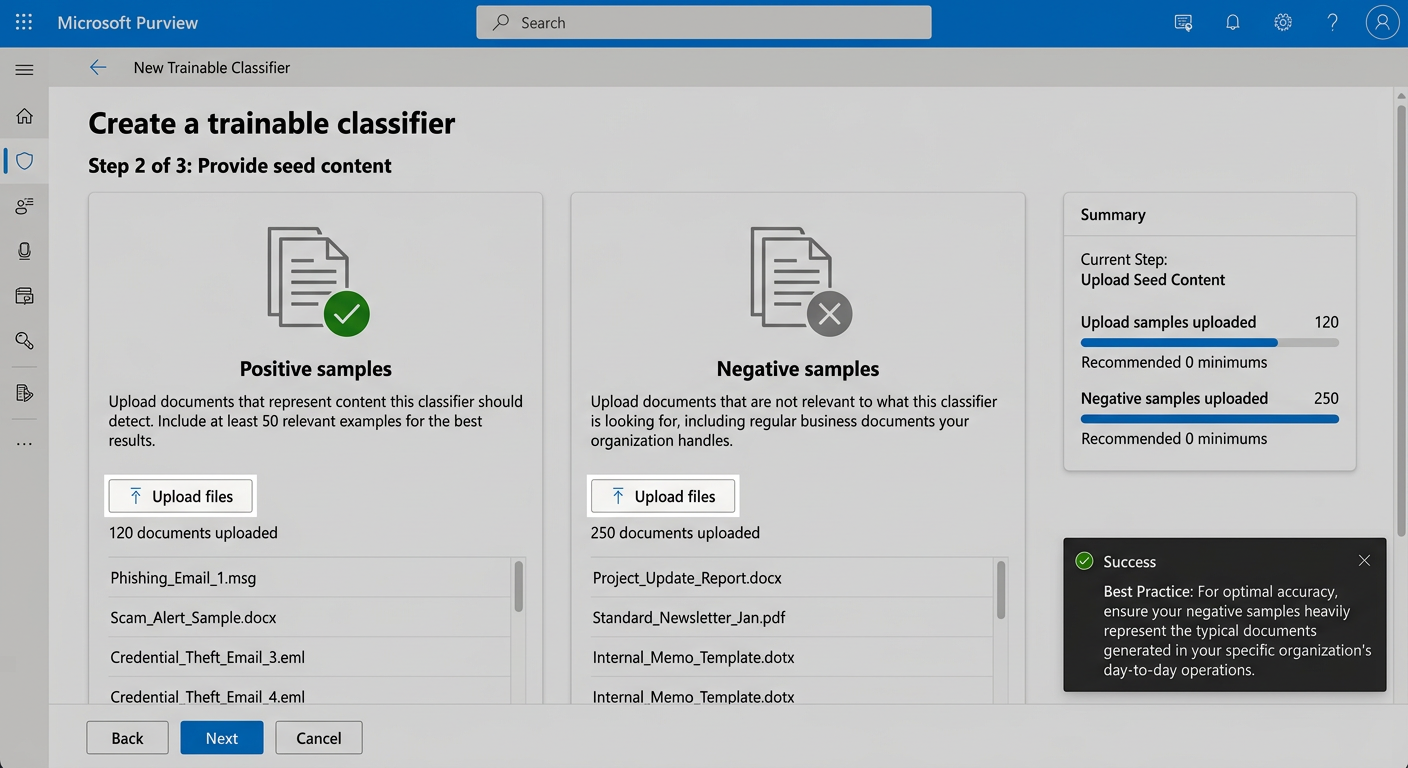
Gather documents that perfectly match the criteria you want the classifier to detect. For example, if you are building a classifier to detect personal information theft, include actual scam messages and phishing emails in this group.
Collect normal, everyday documents that should not trigger a match. Continuing the previous example, these would be legitimate business communications, standard newsletters, or benign internal memos.
Navigate to the Microsoft Purview compliance portal, go to Data classification > Trainable classifiers, create a new classifier, and upload your designated positive and negative folders as seed content.
Secure Your Daily Documents with WPS Office
While Microsoft Purview is an enterprise-level tool for organizational data governance, you can manage and protect your individual files seamlessly with WPS Office. It is a powerful, free alternative to Microsoft Office that includes built-in document encryption for local data security.
- 1. Download and Install: Visit the official WPS Office website to download the suite for your operating system.
- 2. Open Office Files: Launch WPS Office to easily open, edit, and save any existing Microsoft Office formats (.docx, .xlsx, .pptx) without losing formatting.
- 3. Encrypt Sensitive Files: To protect your data, go to Menu > Document Encryption > Encryption to set a secure password for your local files.
Frequently Asked Questions
How many samples do I need to train a custom classifier in Microsoft Purview?
Microsoft typically recommends starting with at least 50 to 500 positive samples, and up to 10,000 negative samples to establish a reliable baseline for the machine learning model.
Why is my trainable classifier returning too many false positives?
This usually happens when the negative samples provided during training are not diverse enough. Ensure you include a wide variety of normal, non-matching documents that reflect your organization's standard communications.
Can I use pre-trained classifiers instead of supplying my own samples?
Yes, Microsoft Purview offers several seeded (pre-trained) classifiers for common content types such as source code, resumes, and offensive language, which do not require you to provide positive or negative samples.


