

Fix Word Find and Replace Missing Text in OCR Documents

Question details
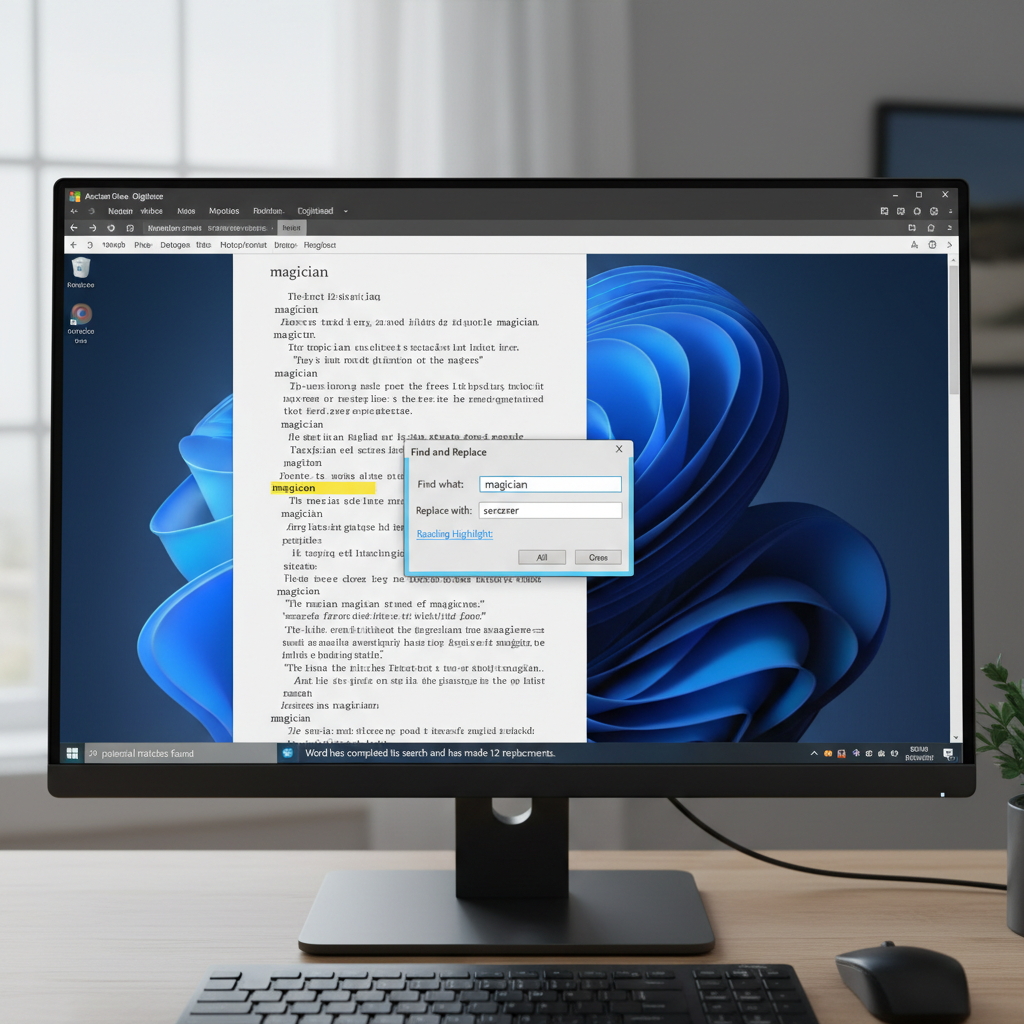
Find and Replace fails to identify all occurrences of specific text in a document generated from OCR scanning.
- Product
- Microsoft Word
- Device & OS
- not provided
- Scenario
- Searching for and replacing specific words or phrases inside a lengthy historical book digitized using OCR.
- Observed behavior
- Word skips multiple occurrences of the searched text because the document contains unrecognized characters, inconsistent fonts, italics, and hidden spacing artifacts generated by the OCR process.
Keep the original scanned images open on a secondary monitor or printed out, as you will need to manually reference them to correct misspelled or unrecognized text blocks.
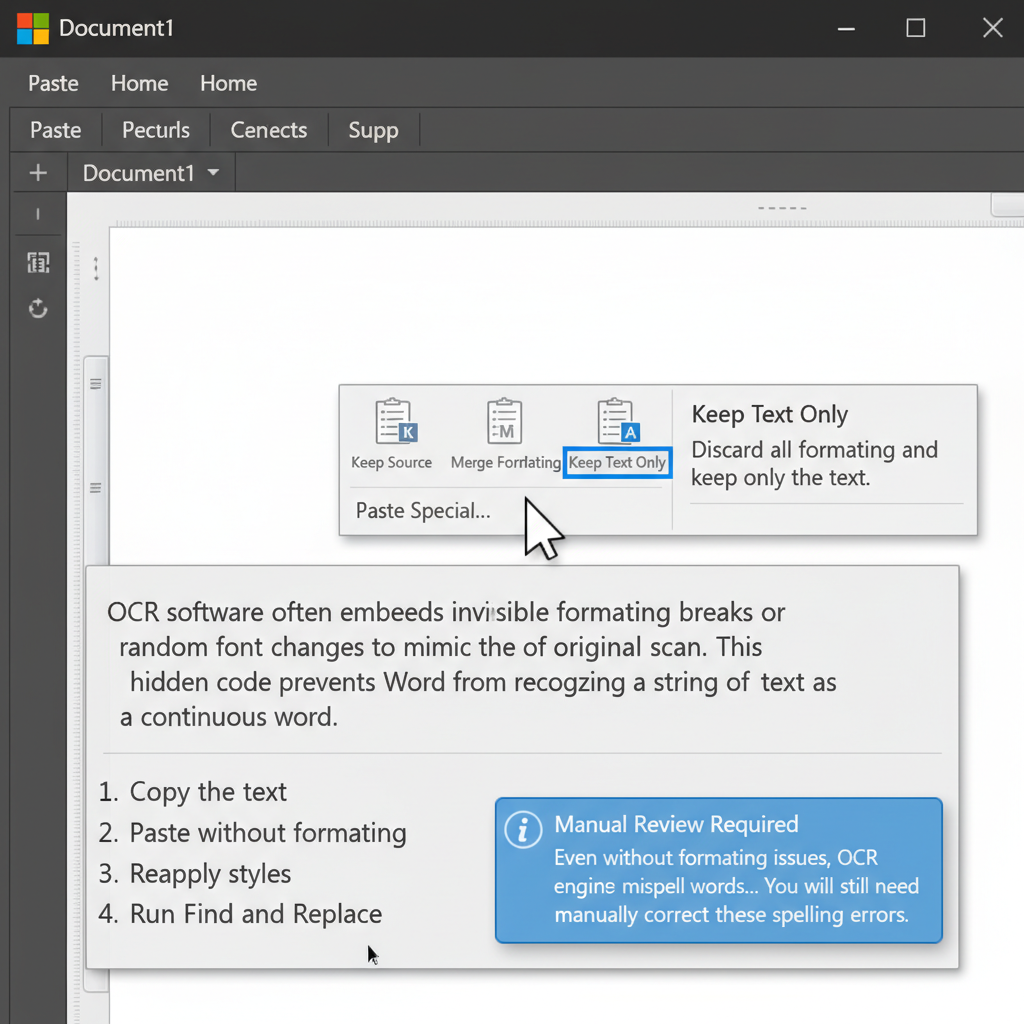
Paste OCR Content as Plain Text to Remove Formatting
Pasting the OCR output as unformatted text strips away hidden artifacts, inconsistent fonts, and weird spacing that confuse the Find tool.
OCR software often embeds invisible formatting breaks or random font changes to mimic the original scan. This hidden code prevents Word from recognizing a string of text as a continuous word.
Press Ctrl+A to select the entire document content, then press Ctrl+C to copy it.
Open a new, blank document. In the Home tab, click the arrow below 'Paste' and select 'Keep Text Only', or use Paste Special and choose 'Unformatted Text'.
Manually apply heading and paragraph styles to structure your document again.
Press Ctrl+H to open Find and Replace and search for your terms in the newly cleaned text.
Reprocess the Document Using Alternative OCR Software
Since Word can only find text that is correctly digitized, using a more accurate OCR engine can prevent missing text in the first place.
Extract Text Accurately with WPS Office OCR
Avoid Find and Replace errors caused by messy formatting. WPS Office features a highly accurate built-in OCR tool that extracts text clean from scanned images and PDFs, making editing and searching seamless.
- 1. Open WPS Office: Launch WPS Office and navigate to the Tools tab on the main dashboard.
- 2. Launch the OCR Tool: Click on 'OCR' or 'PDF to Word' to open the conversion utility.
- 3. Import and Extract: Import your original scanned PDF or images, select your target language, and click 'Extract Text'.
- 4. Edit the Document: Open the generated document in WPS Writer and use the Find and Replace feature (Ctrl+H) to easily modify your text.

Frequently Asked Questions
Why does Find and Replace ignore specific words in my scanned document?
OCR software sometimes misinterprets letters (like reading 'rn' as 'm', or '1' as 'l') or inserts invisible spacing characters between letters. Since the Find tool looks for exact character matches, it misses these misspelled or oddly spaced words.
Can I force Word to ignore formatting during a search?
Yes. Open the Find and Replace dialog (Ctrl+H), click 'More', and make sure 'No Formatting' is selected at the bottom. This ensures Word isn't inadvertently restricting your search to text with specific fonts, sizes, or italics.
How do I find hidden spaces or line breaks left by OCR?
In the Find and Replace dialog, click 'More', then use the 'Special' button to search for specific hidden elements like paragraph marks, manual line breaks, or white spaces that may be breaking up your paragraphs.


