

Why Acrobat Redaction Misses Text in Scanned PDFs & How to Fix It

Question details
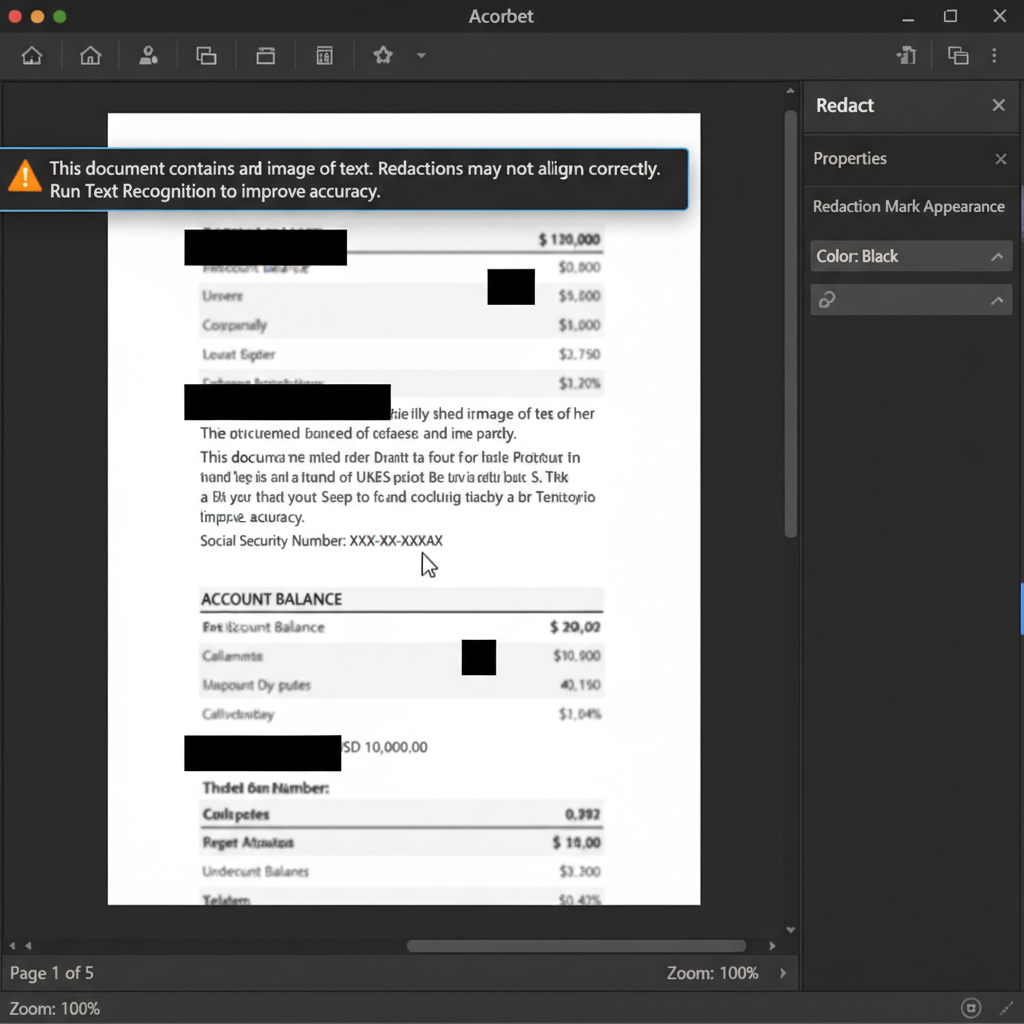
Users experience redaction marks missing the target text or being offset when attempting to redact sensitive information in scanned PDF documents.
- Product
- Adobe Acrobat Pro
- Device & OS
- not provided
- Scenario
- Applying security redactions to sensitive information within a scanned PDF document.
- Observed behavior
- Redaction marks do not align properly with the visual text or miss the text entirely because the document contains an image of text rather than an actual recognized text layer.
Before attempting to recognize text or apply permanent redactions, save a backup copy of your original scanned PDF to prevent accidental loss of data.
Run OCR Before Applying Redactions in Adobe Acrobat
Convert the scanned image into recognizable text using Optical Character Recognition (OCR) so Acrobat can accurately target and redact the text.
Scanned PDFs are essentially flat images. Without an embedded, recognized text layer, Acrobat attempts to guess text placement, which often results in offset or misplaced redaction marks. Running OCR creates a true, searchable text layer directly over the image, ensuring your redactions are applied precisely where intended.
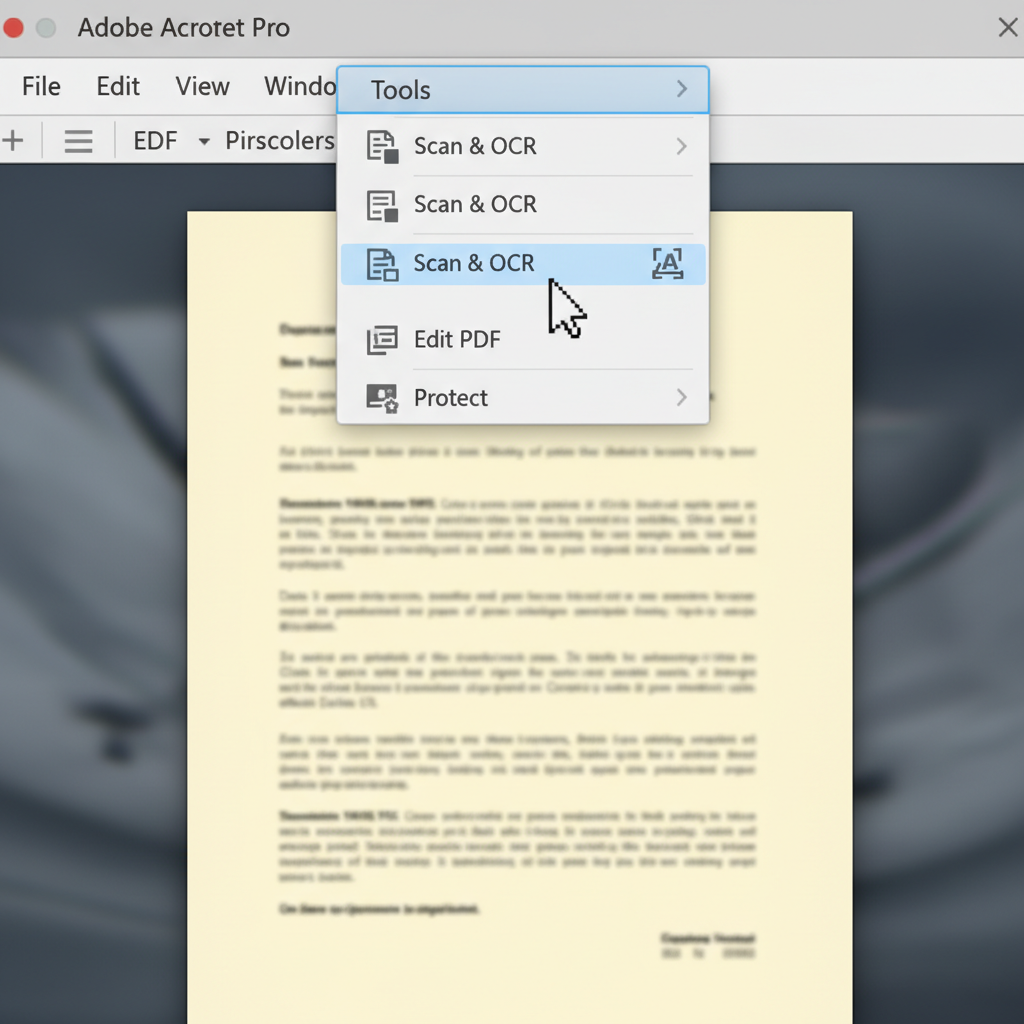
Open your scanned PDF in Adobe Acrobat Pro. Navigate to the 'Tools' menu at the top of the screen and select 'Scan & OCR'.
Click on 'Recognize Text' in the toolbar and choose 'In This File'. Click the 'Recognize Text' button to allow Acrobat to process the image and create a text layer.
Once the OCR process is complete, use your cursor to select some of the text. This helps confirm that the new text layer is correctly aligned with the visual layout of the document.
Go back to 'Tools' and select 'Redact'. Choose 'Mark for Redaction', highlight the sensitive text accurately, and click 'Apply'. Be sure to accept the prompt to sanitize hidden information.
Easily OCR and Redact PDFs with WPS Office
WPS Office features a powerful, built-in PDF editor that allows you to easily perform OCR on scanned documents and securely redact sensitive information without alignment issues.
- 1. Open Your Scanned PDF: Launch WPS Office and open your scanned PDF document in the WPS PDF workspace.
- 2. Run OCR to Extract Text: Navigate to the 'Tools' tab and select 'OCR'. Choose to convert the document so that a selectable text layer is generated.
- 3. Apply Permanent Redaction: Go to the 'Protect' tab, select 'Redact', highlight the exact text you wish to hide, and apply the redaction to permanently secure the document.

Frequently Asked Questions
Why do redaction marks shift when I save a PDF document?
This usually happens when the document is a scanned image without a proper text layer. The software attempts to guess the coordinates of the text based on the image. Running OCR creates an embedded text layer, anchoring the redaction marks to specific characters and preventing them from shifting.
Does drawing a black box over an image permanently hide the text?
No. Drawing a black box using basic markup or drawing tools only places a visual layer over the text. The underlying image or text can still be selected, copied, or uncovered. You must use a dedicated 'Redact' tool to permanently remove the underlying data.
How do I know if my PDF is a scanned image or has a real text layer?
Try selecting the text with your cursor. If you can highlight individual words and sentences and copy them into a text editor, the PDF has a true text layer. If clicking on the document highlights the entire page as a single block, it is a scanned image.
What is the purpose of the 'Sanitize Document' feature?
Sanitizing a document removes hidden information that isn't visible on the page. This includes metadata, author details, hidden text (like the text generated by OCR underneath a redaction), and previous file revisions, ensuring your sensitive data is completely stripped from the file.


