

Fix Invalid or Encoded PDF Data in Excel Power Query

Question details
The user needs to import readable, usable data from a PDF through Excel Power Query instead of receiving random, encoded, or unreadable characters.
- Product
- Microsoft Excel Power Query
- Device & OS
- not provided
- Scenario
- A PDF file is connected through the Power Query PDF connector for data extraction.
- Observed behavior
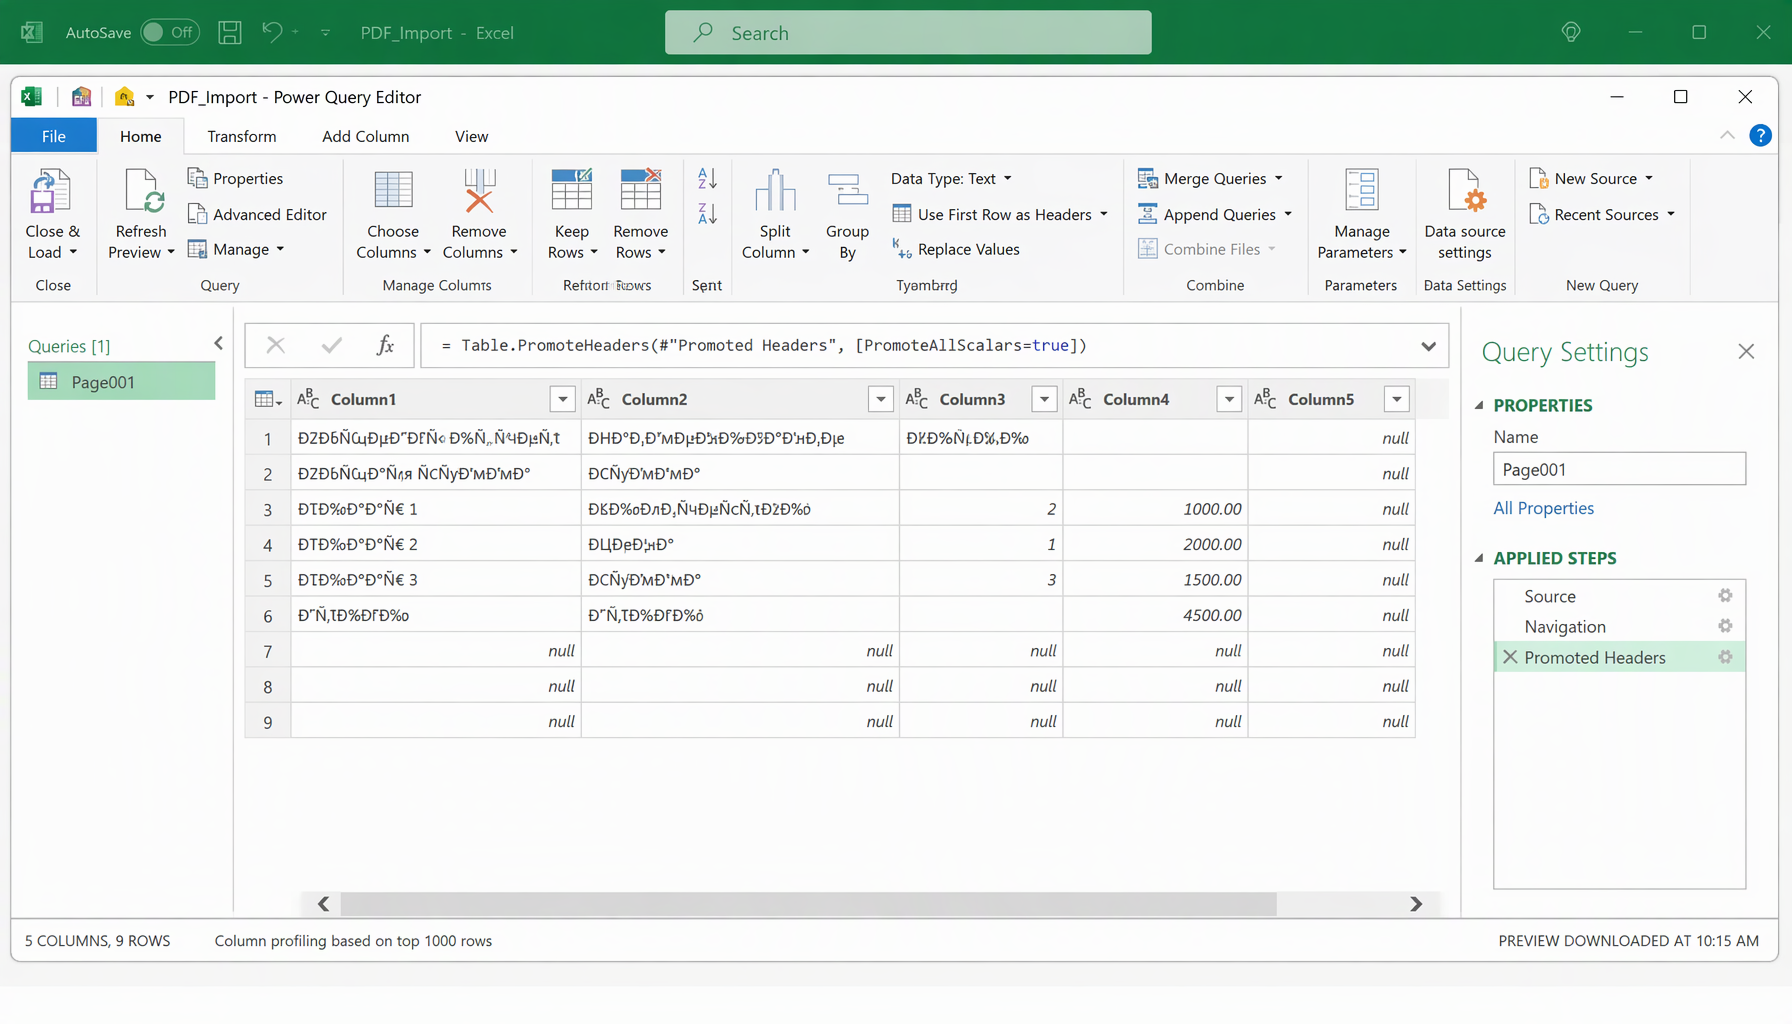
- Power Query connects to the PDF but displays corrupted-looking text, encoded characters, or data that does not match the original document.
Open the PDF in a PDF viewer and test whether you can select and copy its text correctly. If copied text is already unreadable or the document is an image-only scan, Power Query cannot reliably extract clean text without preprocessing.
Check whether the PDF contains selectable text or requires OCR
Use this first when Power Query returns unreadable characters, especially with scanned PDFs or documents created from images.
Power Query can extract embedded text and table structures, but it cannot accurately interpret a PDF that contains only scanned page images. Optical character recognition (OCR) creates a searchable text layer that can be imported more reliably.
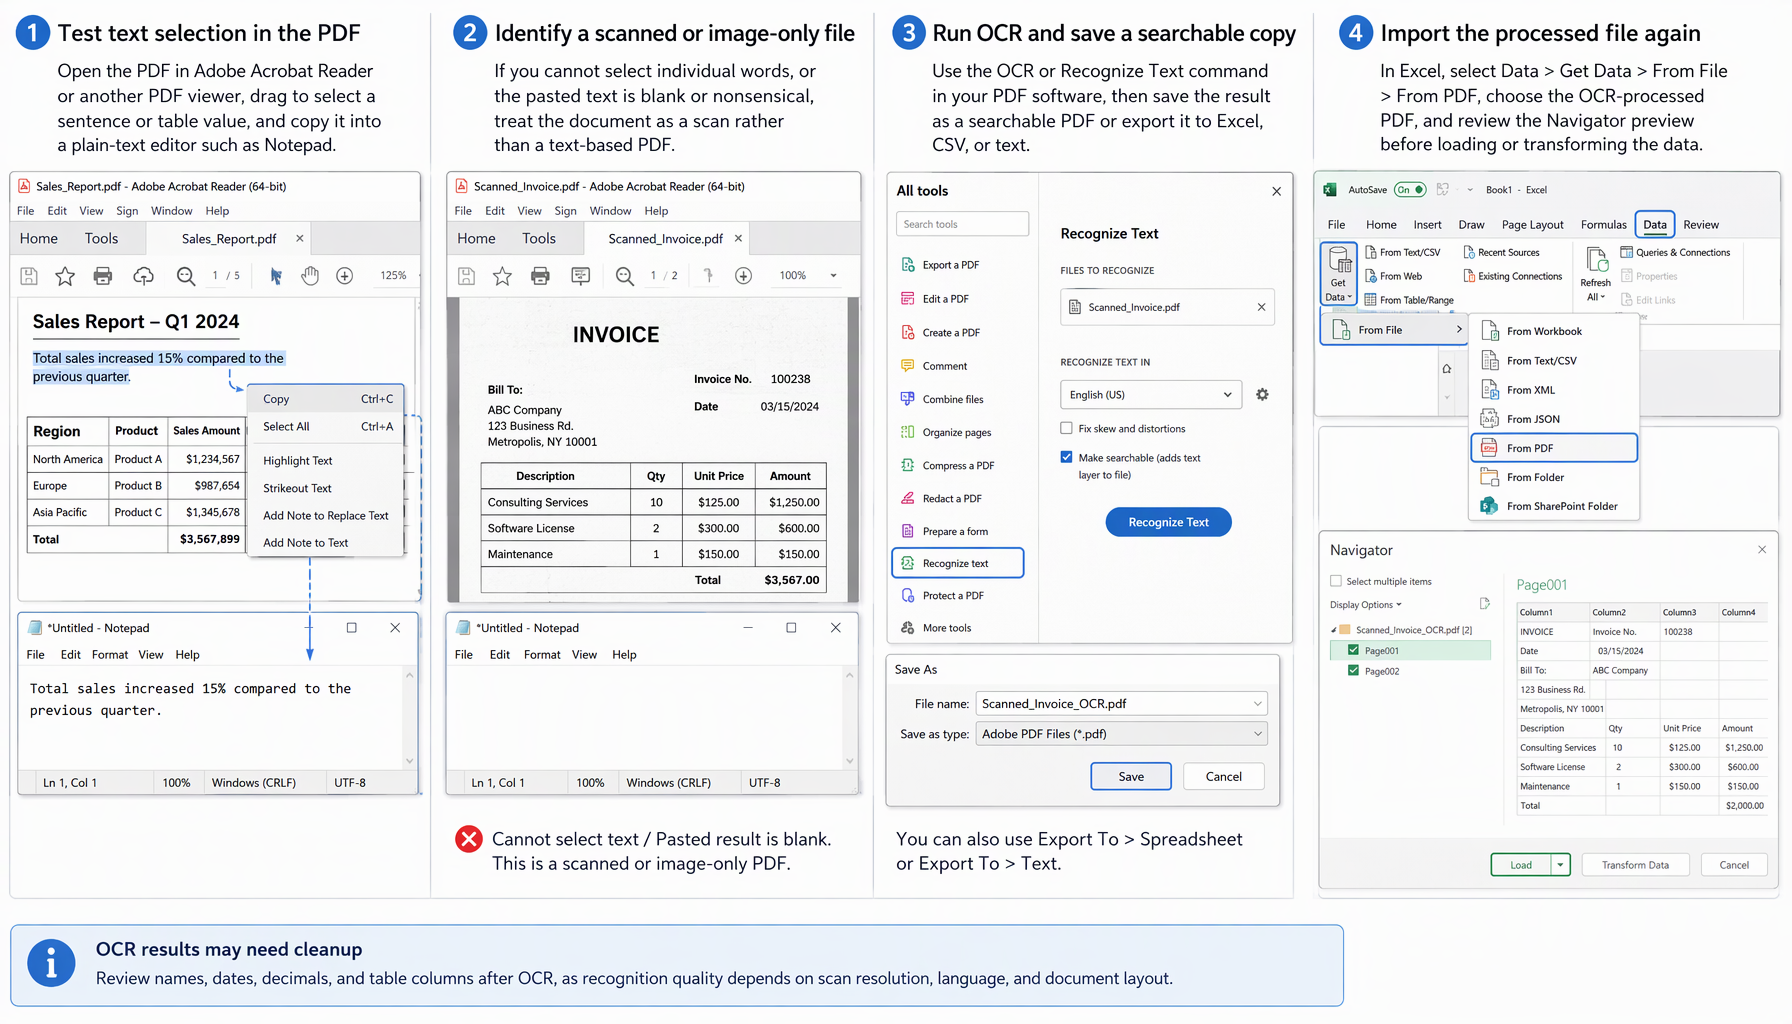
Open the PDF in Adobe Acrobat Reader or another PDF viewer, drag to select a sentence or table value, and copy it into a plain-text editor such as Notepad.
If you cannot select individual words, or the pasted text is blank or nonsensical, treat the document as a scan rather than a text-based PDF.
Use the OCR or Recognize Text command in your PDF software, then save the result as a searchable PDF or export it to Excel, CSV, or text.
In Excel, select Data > Get Data > From File > From PDF, choose the OCR-processed PDF, and review the Navigator preview before loading or transforming the data.
Convert or resave the PDF before importing it into Power Query
Use this option for text-based PDFs with unusual fonts, damaged encoding, or complex layouts that Power Query does not parse correctly.
Review PDF permissions and use a dedicated extraction tool for difficult files
Use this method when the PDF has extraction restrictions, protected content, multi-column pages, or tables that remain unusable after conversion.
Open Cleaned PDF Exports in WPS Office Spreadsheets
If Excel Power Query cannot interpret a complex PDF correctly, first export or clean the document as an Excel workbook or CSV file. WPS Office is a free, lightweight alternative for opening, reviewing, and editing the cleaned spreadsheet with a familiar spreadsheet interface and smooth migration from Microsoft Office files.

Frequently Asked Questions
Why does Power Query show random characters when importing a PDF?
The PDF may use unsupported text encoding, embedded fonts, a complex layout, or image-only scanned pages. Test copied text in a plain-text editor to determine whether the issue is already present in the PDF.
Can Excel Power Query extract tables from scanned PDFs?
Not reliably without OCR. Convert the scan into a searchable PDF or export recognized text and tables to XLSX or CSV first, then import that processed file through Data > Get Data.
How can I tell whether a PDF is scanned or text-based?
Open the document in a PDF viewer and try selecting one word. A text-based PDF lets you select individual words and paste readable text; a scanned PDF generally selects only an image area or pastes no usable text.
Do PDF security settings affect Power Query imports?
Yes. Restrictions on copying or content extraction can limit access to the PDF text. Check File > Properties > Security in your PDF viewer and remove restrictions only if you are authorized to do so.
What file format should I use instead of PDF for Power Query?
Use the original XLSX or CSV file whenever possible. If only a PDF is available, export it to XLSX, CSV, or TXT with a PDF conversion tool and inspect the result before loading it into Power Query.


