

How to Fix Dataverse Flow Errors When Document Tables Contain Blanks

Question details
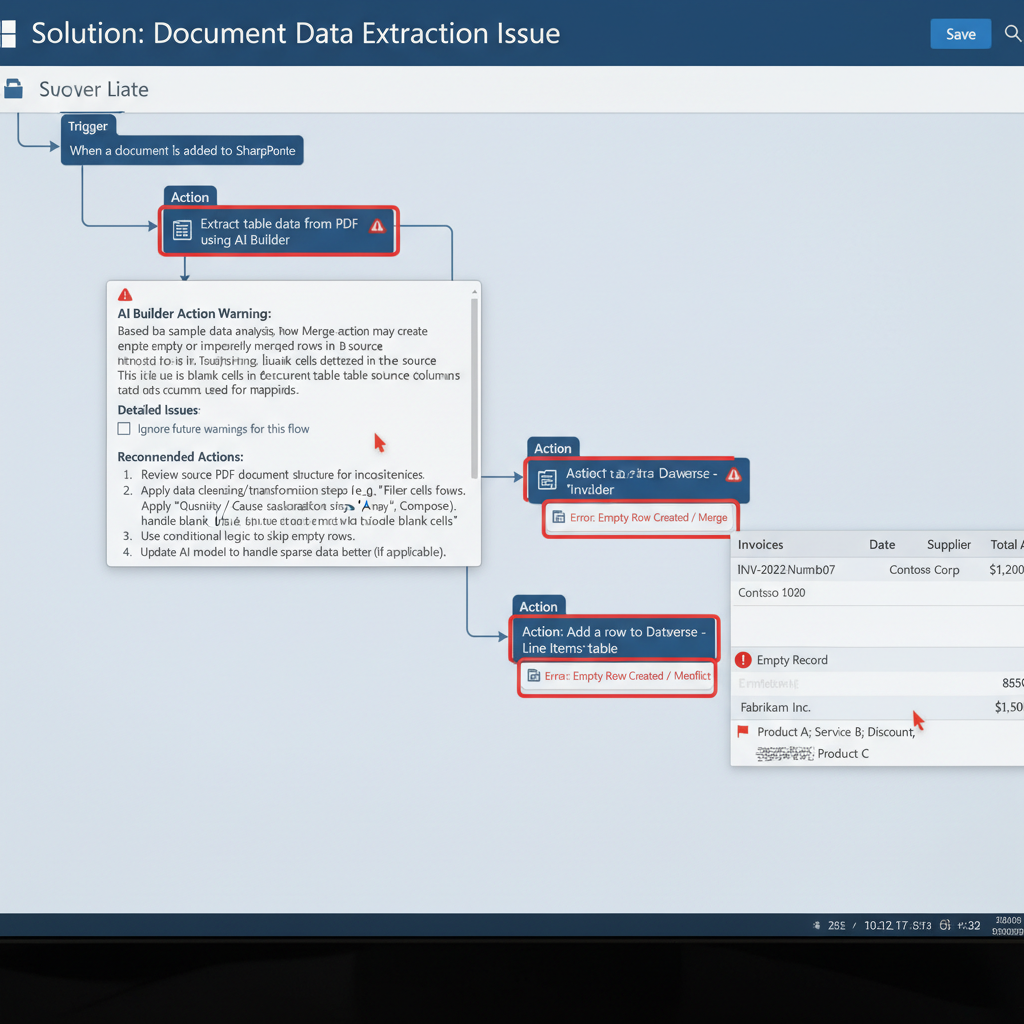
The user needs to resolve an issue where a document data extraction flow creates empty rows or improperly merges multiple rows in Dataverse due to blank source cells.
- Product
- Power Automate / Dataverse
- Device & OS
- not provided
- Scenario
- Extracting table data from source documents (such as PDFs) into Dataverse using a workflow automation AI action.
- Observed behavior
- The automation flow creates empty Dataverse records or incorrectly combines multiple sample rows into a single record whenever the source document tables contain blank cells.
Ensure you have access to your workflow run history and the source documents (like PDFs) to review the raw extracted table data and identify where the blank cells are occurring.
Add a Condition to Filter Out Blank Rows
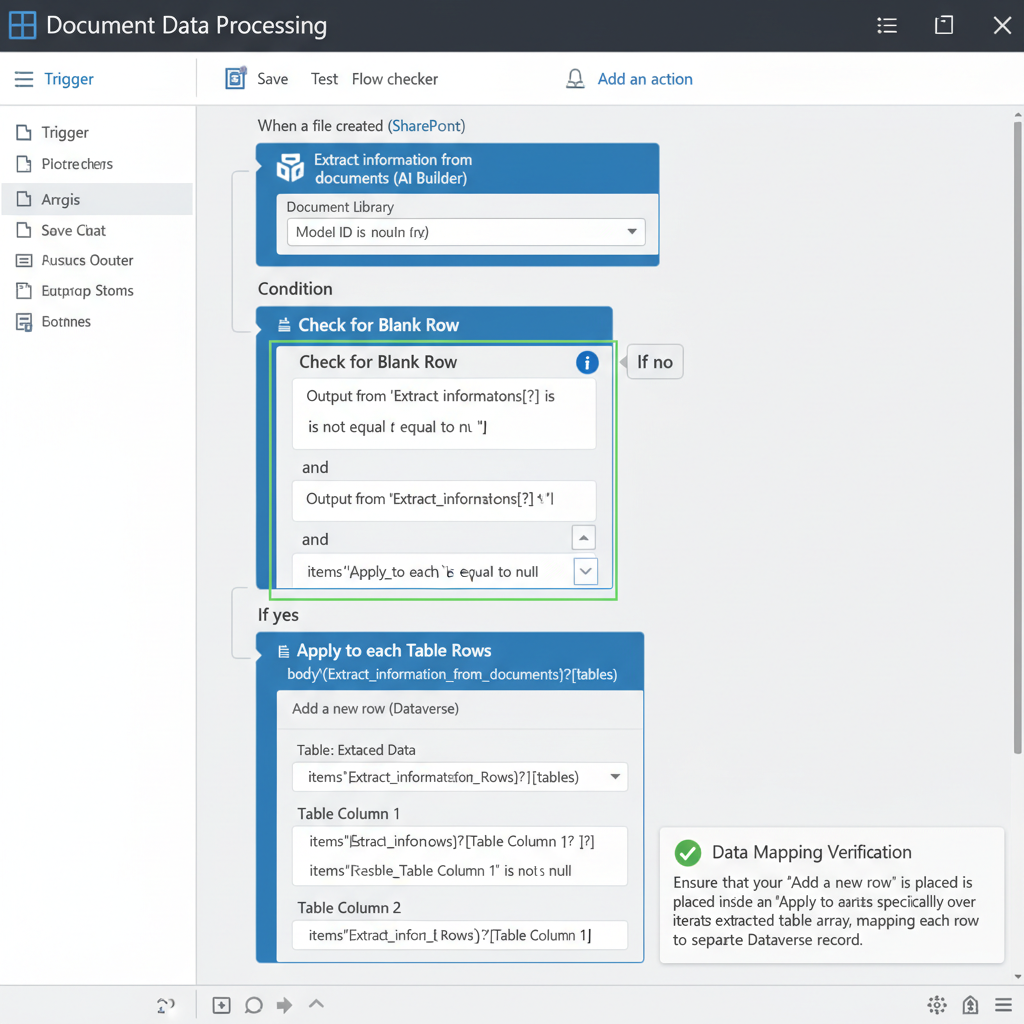
Prevent empty rows from being written to Dataverse by adding a flow condition that checks if the required table fields are blank before creating a new record.
When the document extraction AI processes a table, it may capture empty rows at the end of the document or blank cells within the layout. Setting up a strict condition ensures only valid data is passed to Dataverse.
Run a test flow and review the output from the 'Extract information from documents' AI action to understand the JSON structure of the extracted table array.
In your flow editor, insert a 'Condition' control immediately before the 'Add a new row' Dataverse action.
Set the condition to check if the required fields from the extracted table are equal to 'null' or an empty string.
Drag the Dataverse 'Add a new row' action inside the 'If yes' (or 'If no', depending on your logic) branch so that the system only processes rows that contain valid data.
Verify Document Type and Table Formatting
Check the source file type and structure to ensure the AI model can properly detect table boundaries without merging rows.
Prepare Clean Document Tables Easily with WPS Office
While WPS Office does not run Dataverse automation flows, preparing your source documents with well-formatted, clean tables is critical for accurate AI extraction. WPS Office is a lightweight, free alternative to Microsoft Office that offers powerful PDF and spreadsheet editing tools to prevent blank cell issues before they reach your workflow.

Frequently Asked Questions
Why is my automation flow creating blank rows in Dataverse?
This typically happens when the document extraction AI reads empty cells, invisible characters, or extra grid lines at the end of a document table. Without a conditional check to filter these out, the flow processes them as valid records and writes blank rows to Dataverse.
How can I check the exact output of my document extraction action?
You can view the exact output by running a manual test on your flow. Navigate to the flow run history, click on the document extraction action, and look at the raw outputs (usually in JSON format) to see exactly what table data and blank cells were captured.
How do I prevent multiple table rows from merging into one record?
To prevent rows from merging, ensure your 'Add a new row' action is placed inside an 'Apply to each' loop. This loop must be configured to iterate over the specific table array extracted from the document, processing one row at a time.
Does the source document format affect table extraction accuracy?
Yes. Complex, poorly scanned, or heavily styled PDFs might cause the AI model to misinterpret table boundaries. Using clean documents with standard tables and clear borders helps improve extraction accuracy and prevents data overlap.


