

Automatically Split and Rename PDF Files Based on Page Content in Adobe Acrobat

Question details
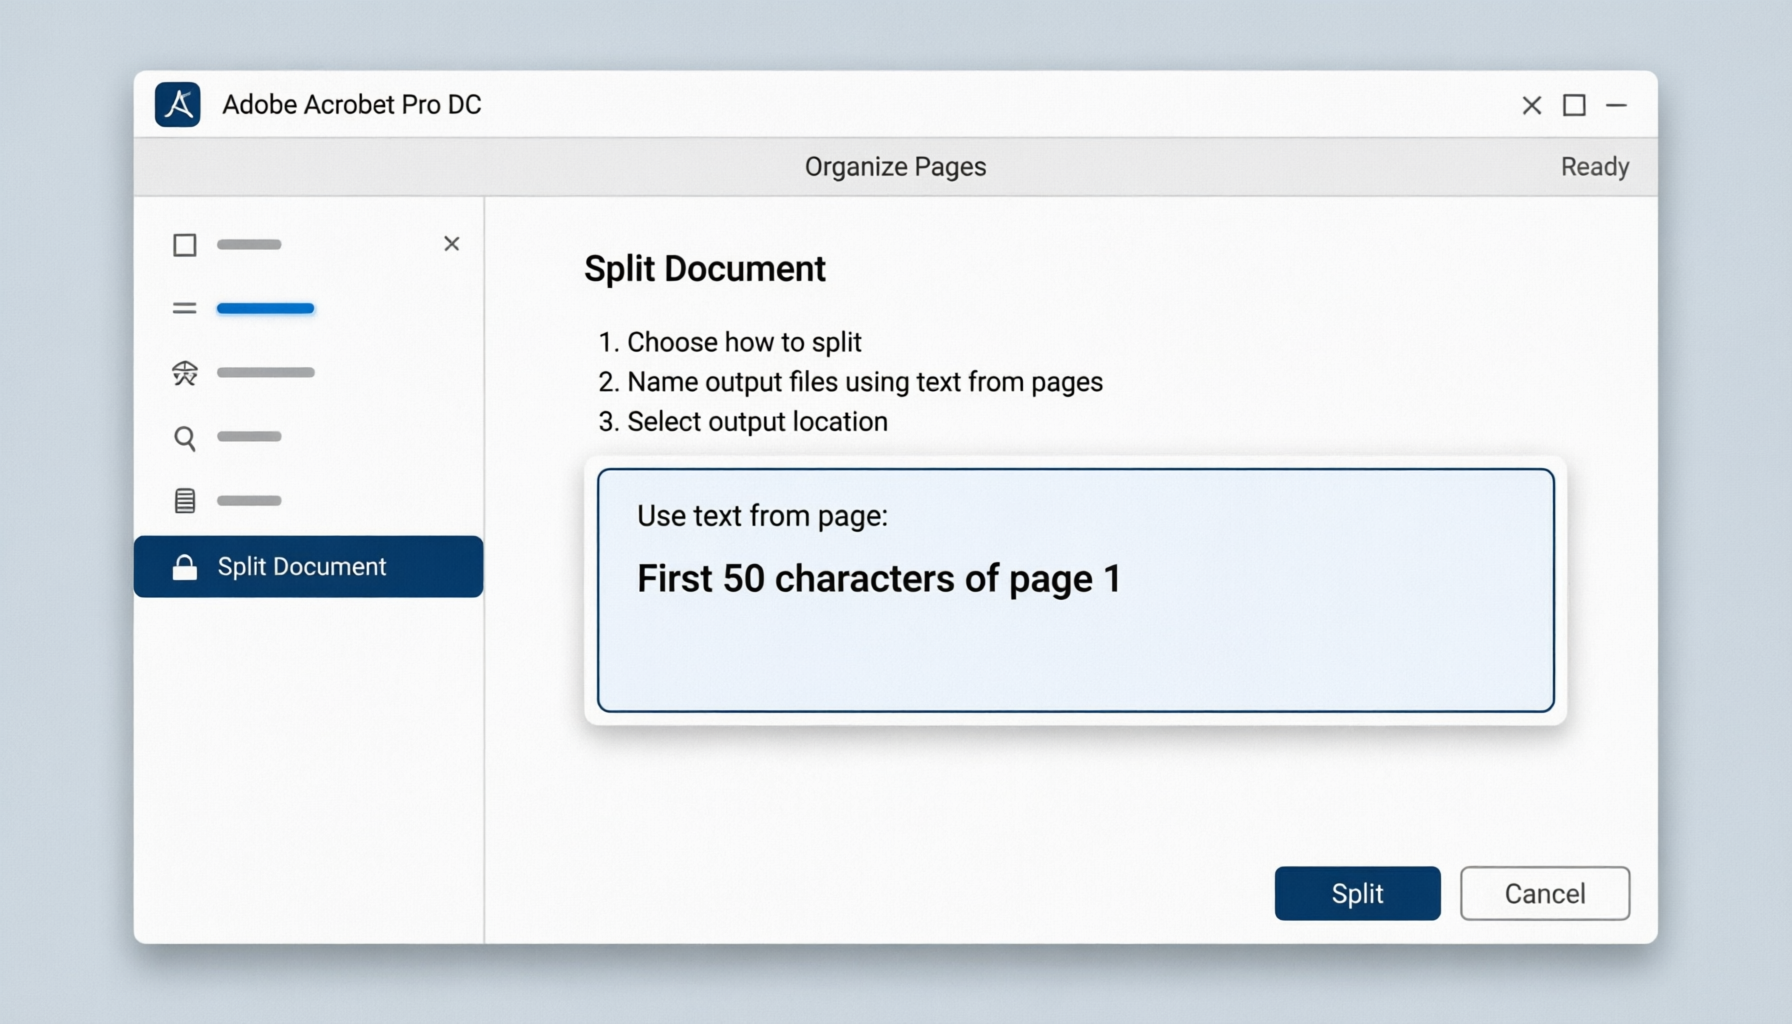
Split a large PDF into individual documents and name each output file using text from its pages.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- A user wants to process a large PDF containing multiple documents and use names, titles, or other page text as filenames.
- Observed behavior
- The desired output is a set of separate PDFs with filenames derived automatically from their content.
Check whether the PDF text can be selected and whether each document has a consistent marker and naming field. If the pages are scans, run OCR first and verify that the extracted text is accurate.
Automate PDF Splitting and Naming with Custom Acrobat JavaScript
Use this approach when document boundaries and filename text follow consistent, recognizable patterns.
This is a custom scripting project rather than a standard one-click Acrobat command. A developer must account for variations in page text, missing fields, duplicate names, and filename restrictions.
Open the PDF in Acrobat and inspect several document starts. Record the text that identifies each boundary and the field that should supply the filename.
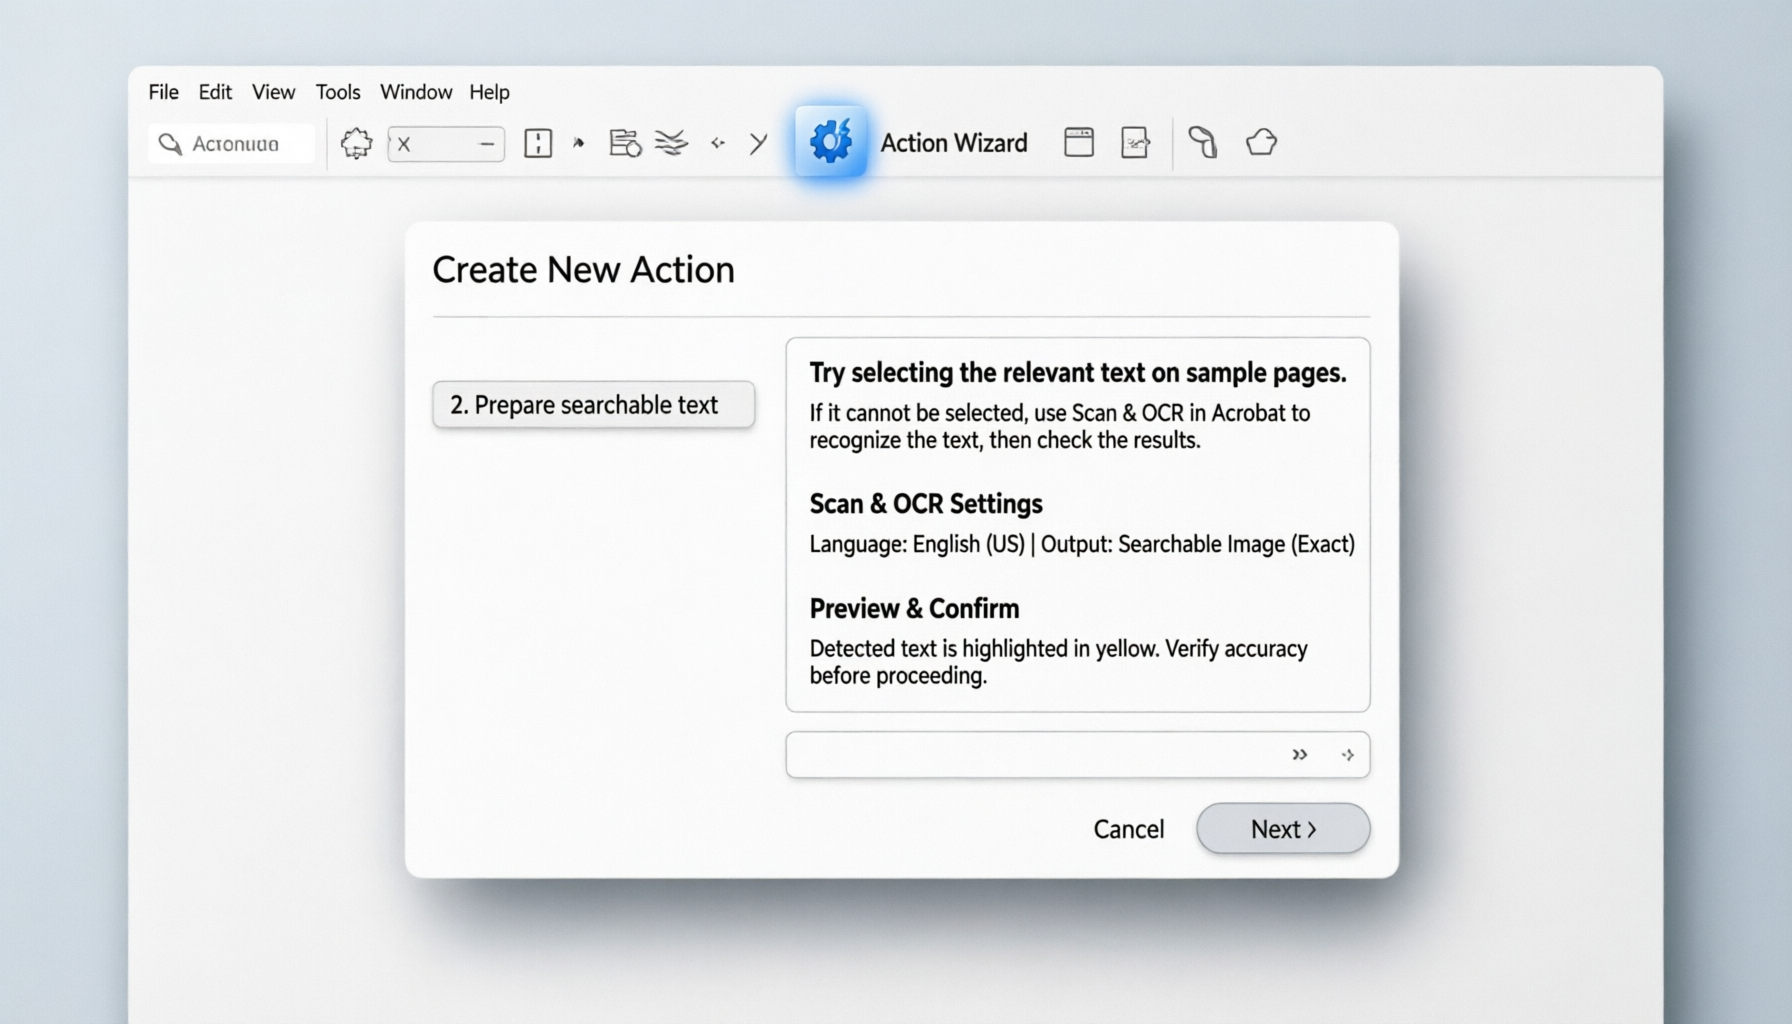
Try selecting the relevant text on sample pages. If it cannot be selected, use Scan & OCR in Acrobat to recognize the text, then check the results.
Ask an Acrobat JavaScript developer to read page text, detect document boundaries, extract each page range, and generate sanitized, unique filenames from the identified fields.
In Acrobat Pro, use Action Wizard to set up an action with Execute JavaScript, or follow the developer's instructions for a trusted script. Test it on a small sample and check every output file and name.
Split the PDF and Rename the Output Files Manually
Use this method for a smaller job or when the page content is too inconsistent for reliable automation.
Use WPS Office for Everyday PDF and Document Work
WPS Office is a free, lightweight Office alternative with a familiar interface and support for common Microsoft Office formats. It can help with everyday PDF work, but it does not replace the custom automation needed to split and name files from page content.

Frequently Asked Questions
Can Acrobat name split PDFs automatically using text on their pages?
Not as a simple standard split setting. A custom Acrobat JavaScript solution can identify page text and generate names if the source documents follow consistent patterns.
What if the PDF consists of scanned pages?
Use Scan & OCR in Acrobat to recognize the text first. Check sample pages carefully, because recognition errors can affect both boundary detection and filenames.
How can I split documents with different page counts?
For manual processing, use Organize Pages to select and extract each page range. For automation, a script must detect a reliable marker that identifies where each document begins or ends.
What happens if two documents produce the same filename?
A custom script should check for duplicate names and add a unique suffix, such as a sequence number, before saving. It should also remove characters that the operating system does not allow in filenames.


