

Can Adobe Acrobat OCR Recognize Two Languages in One PDF?

Question details
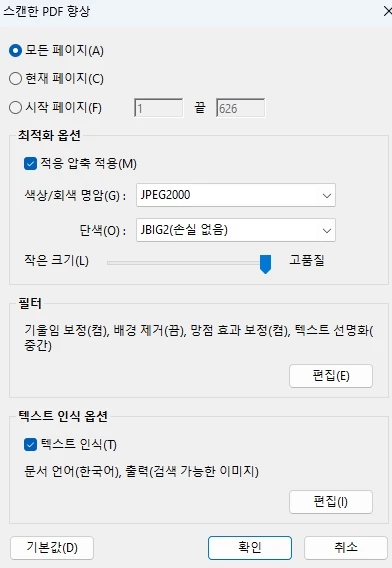
The user needs to perform OCR on a scanned PDF document containing two different languages, but Adobe Acrobat only permits the selection of a single language.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to accurately extract text from a scanned PDF that features bilingual content or mixes two different languages.
- Observed behavior
- Adobe Acrobat restricts the OCR language setting to one language at a time, making it unable to correctly recognize the text written in the secondary language.
Review your scanned PDF to identify the primary language that makes up the majority of the text, as this will serve as your main OCR setting.
Process with Primary Language and Correct Manually
Use Adobe Acrobat's OCR for the document's main language, then manually edit the incorrectly recognized secondary language.
Currently, Adobe Acrobat's OCR engine is designed to process one primary document language at a time. To get the best possible result natively, you must select the language that dominates the document and fix the remaining text by hand.
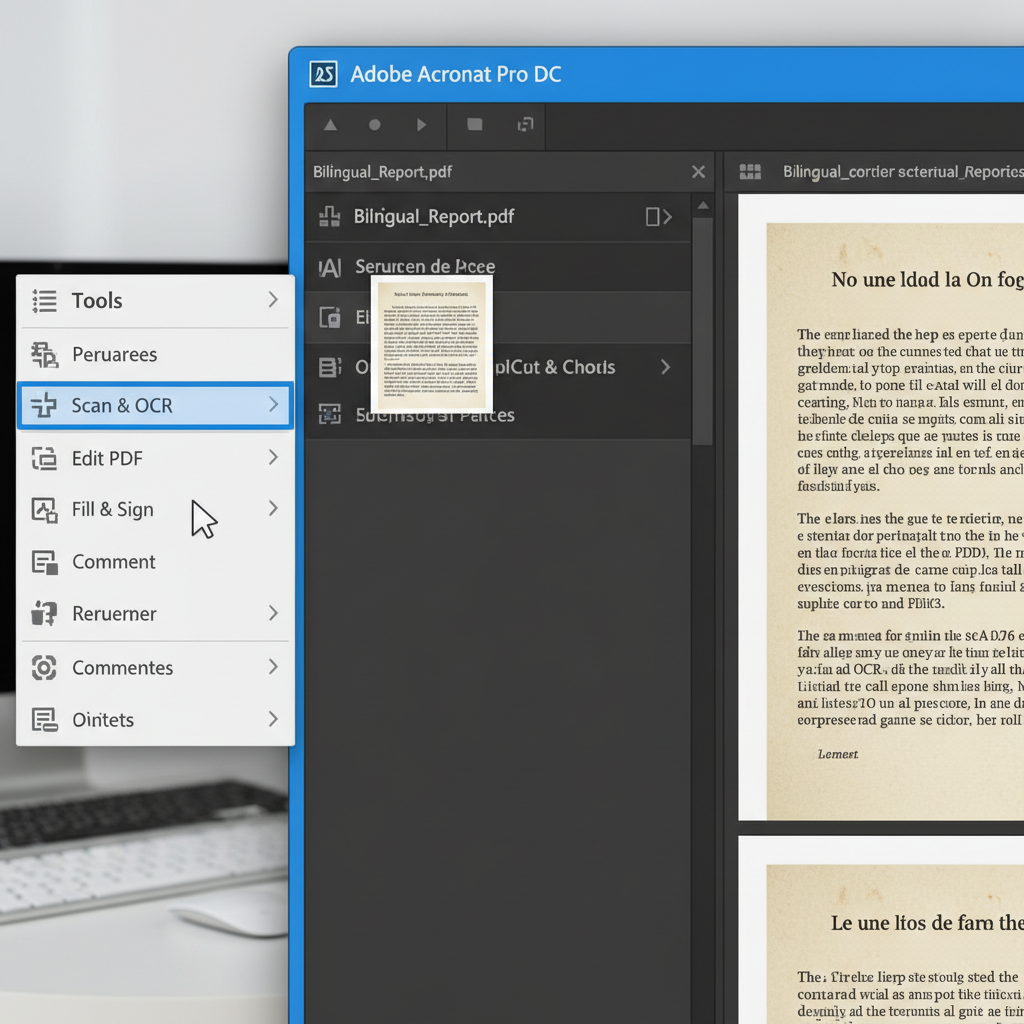
Open your bilingual PDF in Adobe Acrobat. Navigate to the 'Tools' menu and select the 'Scan & OCR' option.
Click on 'Recognize Text' and choose 'In this File'. In the settings, select the language that represents most of the document's content.
Click 'Recognize Text' to begin the process. The engine will accurately parse the primary language.
Select the 'Edit PDF' tool to review the document. Manually retype or correct the text sections belonging to the secondary language that the OCR engine misidentified.
Submit a Feature Request to Adobe
Request multi-language OCR support directly from the Adobe Acrobat product team.
Extract Text from Scanned PDFs with WPS Office
If you frequently work with scanned documents and need a highly accurate text extraction tool, WPS Office offers a robust PDF OCR feature that simplifies converting images into editable text.
- 1. Open Your PDF: Launch WPS Office and open your scanned or image-based PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and select the 'OCR' button to initialize the text recognition tool.
- 3. Extract and Save: Choose whether you want to extract the text directly into a new Word document or save it as plain text, allowing you to easily edit bilingual content.

Frequently Asked Questions
Why does OCR struggle with multiple languages in Adobe Acrobat?
OCR engines rely on specific language dictionaries to recognize character shapes and context. When Acrobat is restricted to one language dictionary, it attempts to match the characters of the secondary language to the primary dictionary, resulting in garbled or incorrect text.
Are there third-party tools that handle bilingual OCR better?
Yes, specialized OCR software and some cloud-based document processors are built to recognize multiple languages simultaneously by referencing combined dictionaries during the scanning process.
Can I process the document twice in Acrobat to get both languages?
Generally, no. Running the 'Recognize Text' tool a second time on the same document with a different language setting will overwrite or conflict with the hidden text layer created during the first pass.


