

Can Adobe Acrobat Detect a Language in an OCR-Processed PDF?

Question details
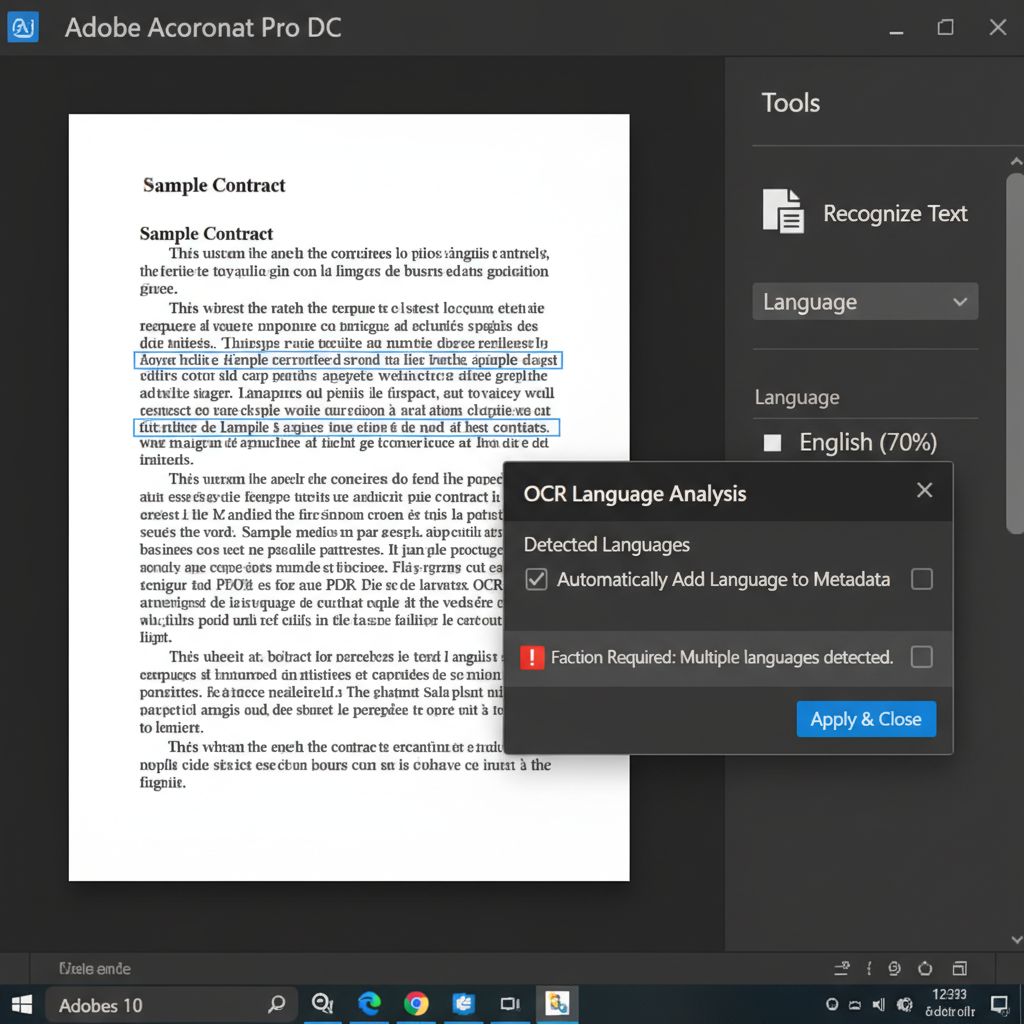
The user wants to know if Adobe Acrobat can automatically identify and flag a PDF document when its OCR engine detects text written in a specific language.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Processing a scanned PDF with OCR and needing to automatically identify the language of the recognized text.
- Observed behavior
- Acrobat performs OCR but does not automatically flag or output the specific language detected in the document's properties or metadata.
Check your Adobe Acrobat version to ensure you have the latest OCR updates installed, and verify the primary language of your scanned document before processing.
Understand Acrobat's Current OCR Language Capabilities
Adobe Acrobat currently lacks a built-in feature to automatically identify and flag the detected language in an OCR-processed file.
While Adobe Acrobat's OCR engine can recognize text in multiple languages, it does not output a metadata flag or notification specifying which language was detected during the scan. You must manually select the recognition language before running OCR for optimal accuracy.
Acknowledge that Acrobat will extract the text based on the language settings you provide in the 'Recognize Text' dialog, but will not auto-detect and tag the document with a language identifier.
If automatic language flagging is critical for your workflow, visit the Adobe Feature Request or Bug Report form online and submit a request for automatic OCR language tagging to be added in future updates.
Extract Text Accurately with WPS PDF OCR
While automatic language flagging isn't standard in most desktop PDF editors, WPS Office provides a robust OCR tool that allows you to easily extract, edit, and convert scanned documents. By manually selecting your target language before processing, you ensure maximum accuracy for multilingual documents.
- 1. Open your PDF in WPS Office: Launch WPS Office and open your scanned PDF document using the WPS PDF tool.
- 2. Access the OCR Feature: Navigate to the 'Tools' tab and click on the 'OCR' button to open the text recognition panel.
- 3. Select Document Language: Choose the primary language of your document from the OCR settings menu to ensure accurate recognition.
- 4. Extract and Save: Click 'Extract Text' to convert the scanned image into editable text, which you can then copy or save as a new document.

Frequently Asked Questions
Can I make Acrobat automatically recognize multiple languages in one PDF?
Acrobat's OCR engine can recognize multiple languages if they share the same script (like English and French), but you generally need to select the primary language in the 'Recognize Text' settings for the best accuracy.
Does any PDF editor auto-detect the language during OCR?
Most standard consumer PDF editors require you to set the OCR language manually. Advanced enterprise data extraction tools may offer language auto-detection, but desktop PDF editors typically do not include this as a standard feature.
How do I change the OCR language in Adobe Acrobat?
Open the 'Scan & OCR' tool, click 'Recognize Text' > 'In this File', then click 'Settings' to choose your desired Document Language from the dropdown menu before running the OCR process.


