

Can You Import ALTO XML OCR Text into Image-Only PDFs in Adobe Acrobat?

Question details
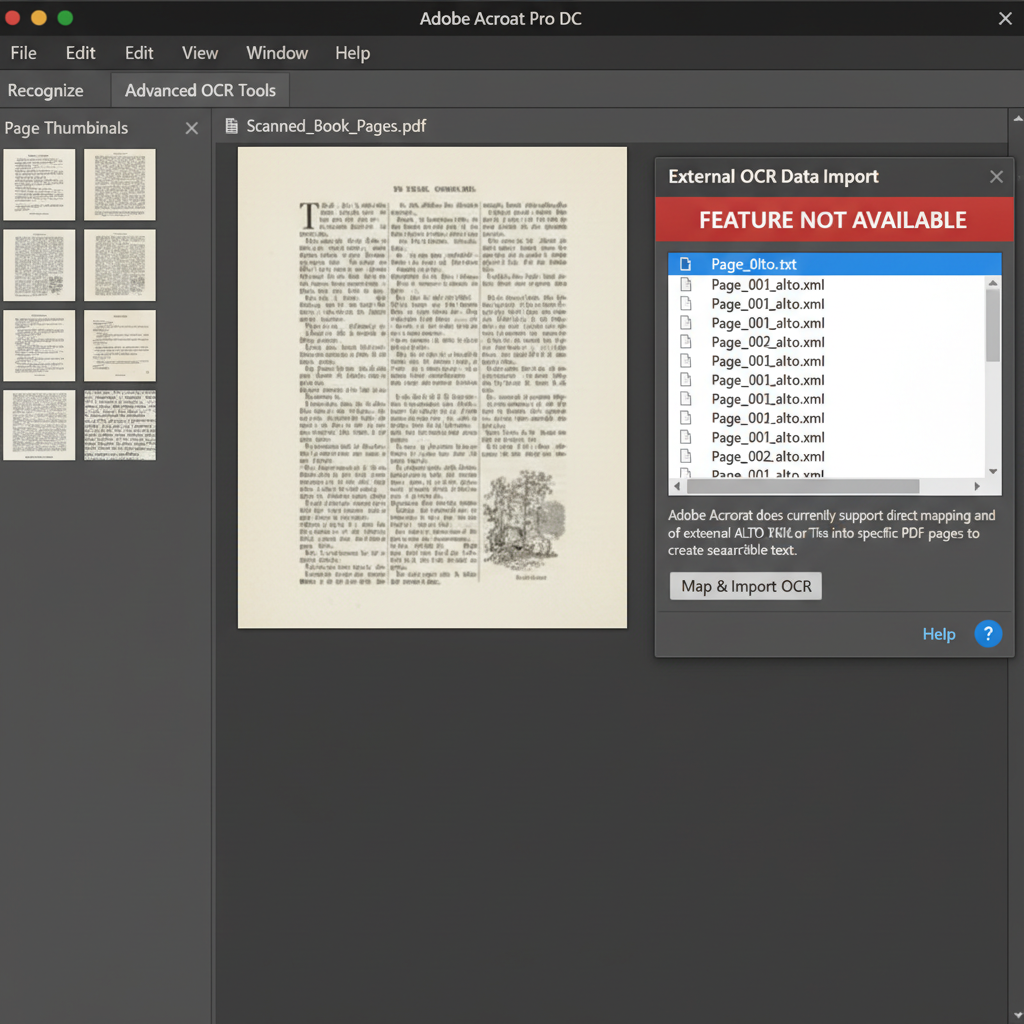
The user needs to import hundreds of ALTO XML or external TXT OCR text files into matching pages of a scanned, image-only PDF to create a searchable document.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to merge external ALTO XML/TXT OCR data with a scanned PDF document to create a fully searchable file.
- Observed behavior
- Adobe Acrobat lacks a built-in feature to map and import external OCR text files directly into specific PDF pages.
Before exploring workarounds, verify that your ALTO XML or TXT files perfectly match the page order and layout of your image-only PDF to prevent text misalignment.
Use Built-In OCR for Scanned PDFs
Since Acrobat cannot import external ALTO XML files, the best native alternative is to run its built-in OCR engine directly on the image-only PDF.
Acrobat's built-in OCR feature analyzes scanned text and converts it into a searchable hidden text layer. This is generally the most straightforward workaround for standard volumes of scanned documents that avoids the need for external XML mapping.
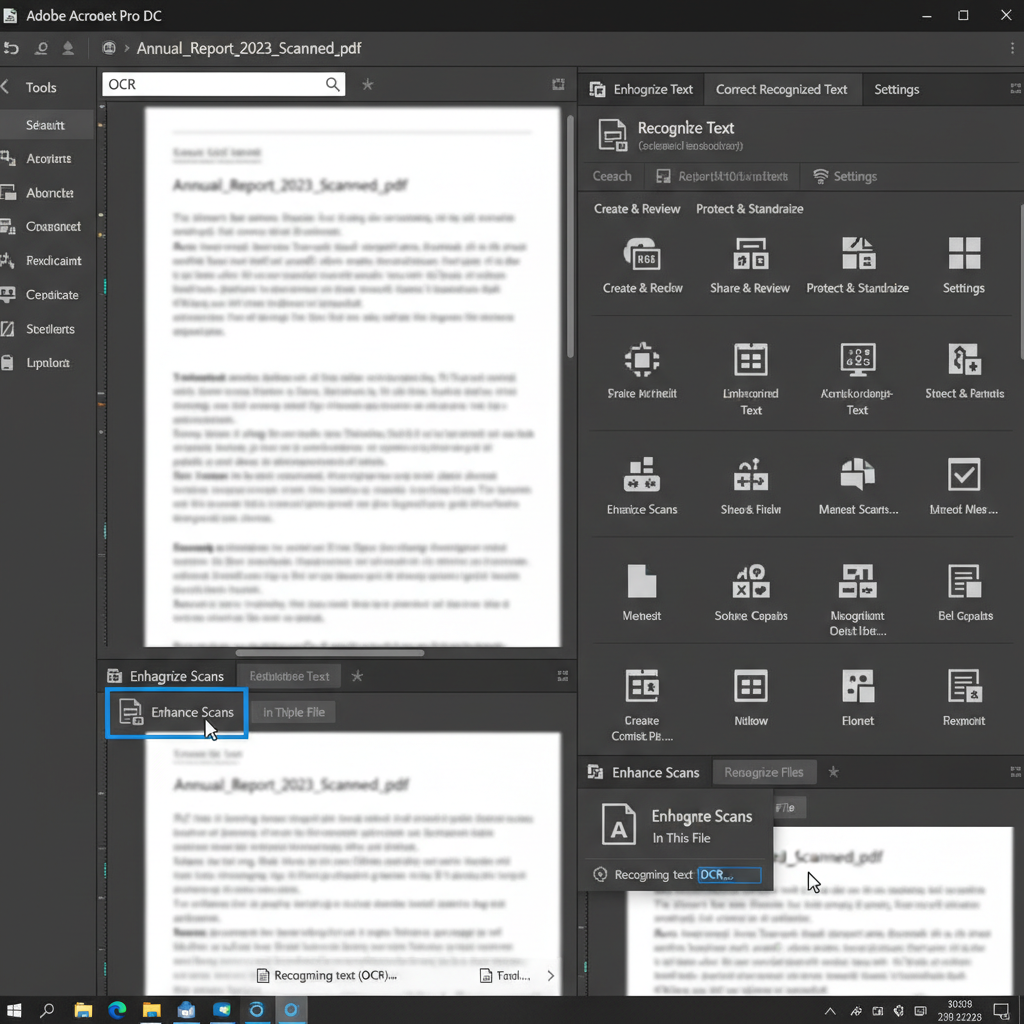
Launch Adobe Acrobat and open your image-only PDF file.
Go to the 'Tools' menu and select 'Scan & OCR' (labeled 'Enhance Scans' in some older versions).
Click 'Recognize Text' in the top toolbar and choose 'In This File'.
Click the 'Recognize Text' button to let the software analyze the document and create a searchable text layer natively.
Submit a Feature Request to Adobe
If native ALTO XML support is crucial for your workflow, submitting a request to the developers can help prioritize future integration.
Easily Make Image-Only PDFs Searchable with WPS Office
While importing external ALTO XML files is complex and not natively supported by most basic PDF readers, you can quickly convert scanned, image-only PDFs into fully searchable or editable documents using the highly accurate built-in OCR tool in WPS Office.
- 1. Open your scanned document: Launch WPS Office and open your image-only PDF file.
- 2. Access the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Choose your output format: Select whether you want to extract the text to a Word document or save it as a Searchable PDF file.
- 4. Process the file: Click 'Start OCR' to analyze the document. WPS Office will quickly generate a new searchable file for you.

Frequently Asked Questions
What is an ALTO XML file?
ALTO (Analyzed Layout and Text Object) XML is an open XML schema commonly used by libraries and archives to describe the layout and text OCR information of digitized physical materials.
Does WPS Office support importing ALTO XML files?
WPS Office does not currently support direct mapping of ALTO XML files into PDFs. However, it features a powerful built-in OCR engine that can generate highly accurate searchable text directly from scanned pages, often eliminating the need for external XML files entirely.
How can I extract text from an image-only PDF for free?
You can use the built-in OCR feature in WPS Office to analyze the image-only PDF and extract the text directly. Simply open the file in WPS Office, go to the Tools tab, and select OCR to extract or convert the document seamlessly.


