

How to Automatically Detect if a PDF Needs OCR in Adobe Acrobat

Question details
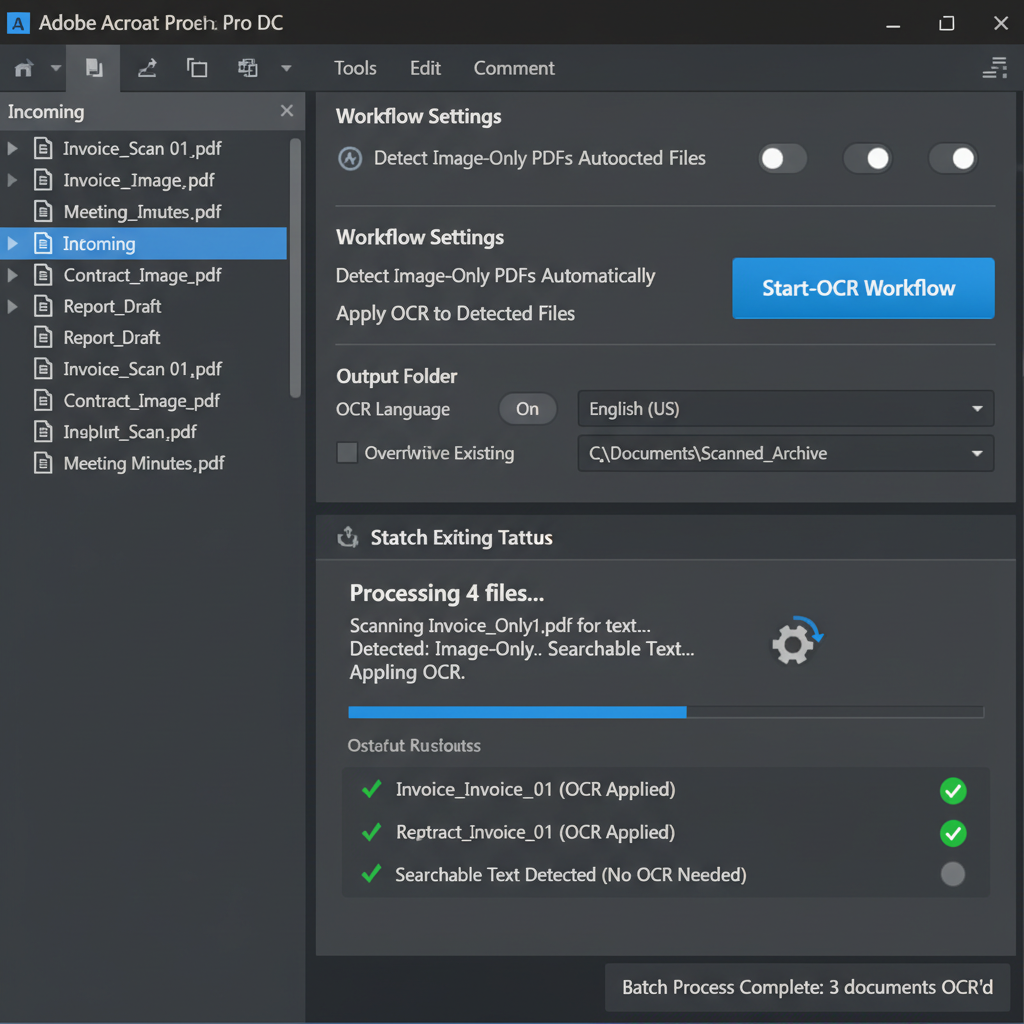
Organizations need a reliable method to automatically identify and apply OCR to image-only or scanned PDFs received from various sources.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Receiving a large volume of PDFs from different sources and needing to ensure all documents have searchable text before archiving or processing them.
- Observed behavior
- Users currently have to manually check documents to see if they lack selectable text before applying OCR, and are seeking an automated workflow or batch action to handle this detection.
Ensure you are using Adobe Acrobat Pro, as the Action Wizard and advanced Preflight profiles required for automated batch processing are not available in the Standard version.
Automate OCR Processing Using Action Wizard
Create an automated batch action that applies OCR to multiple files simultaneously. Acrobat will automatically skip pages that already contain rendered text.
While Acrobat does not have a simple 'if/else' button to sort PDFs by text presence, you can safely run the 'Recognize Text' command across a batch of files. The software's engine is designed to recognize and skip pages or elements that already contain searchable text, ensuring only the image-based sections are processed.
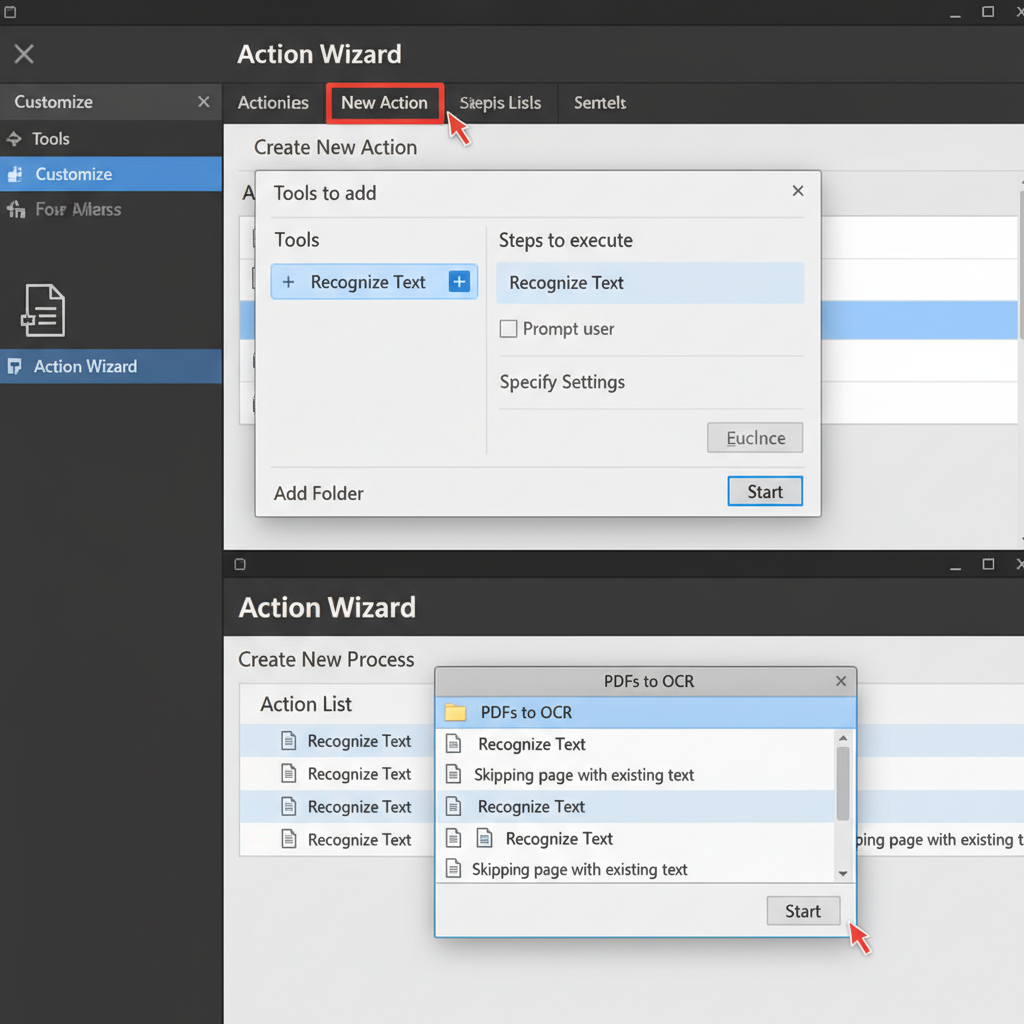
Launch Adobe Acrobat Pro, navigate to the 'Tools' tab, and select 'Action Wizard' under the Customize section.
Click on 'New Action' in the toolbar. In the left pane, expand the 'Recognize Text' category and click the '+' button to add 'Recognize Text' to your action steps.
Uncheck the 'Prompt user' box so the process runs without interruption. Click 'Specify Settings' to define your OCR language and output style (e.g., Searchable Image).
Save the action with a descriptive name. Click on your newly created action from the Action List, add the folder containing your PDFs, and click 'Start' to process them all automatically.
Identify Image-Only PDFs Using Preflight
Use Acrobat's Preflight tool to strictly analyze documents and flag pages that completely lack rendered text.
Easily Convert Scanned PDFs to Searchable Documents with WPS Office
If setting up complex Acrobat workflows feels overwhelming, WPS Office provides an intuitive built-in OCR feature to quickly recognize text in scanned PDFs, making them fully searchable and editable in just a few clicks.
- 1. Open your PDF: Launch WPS Office and open your scanned or image-only PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Configure and Extract: Select the pages you want to process, choose your desired output format (such as searchable PDF or plain text), and click 'Extract' to complete the conversion.

Frequently Asked Questions
Does running batch OCR in Acrobat duplicate existing text?
No, Acrobat's Recognize Text feature automatically detects if a page already contains editable text. It will skip processing existing text elements and only perform OCR on image-based sections.
Can I use Acrobat Standard to automate OCR workflows?
Action Wizard and advanced batch processing features are only available in Adobe Acrobat Pro. Users with Acrobat Standard will need to open and process files manually.
What should I do if the OCR output contains errors?
You can use the 'Correct Recognized Text' tool in Acrobat to review and fix any suspect words or formatting errors that occurred during the automatic OCR process.


