

Can Adobe Acrobat Run OCR on a Selected Area of Every PDF Page?

Question details
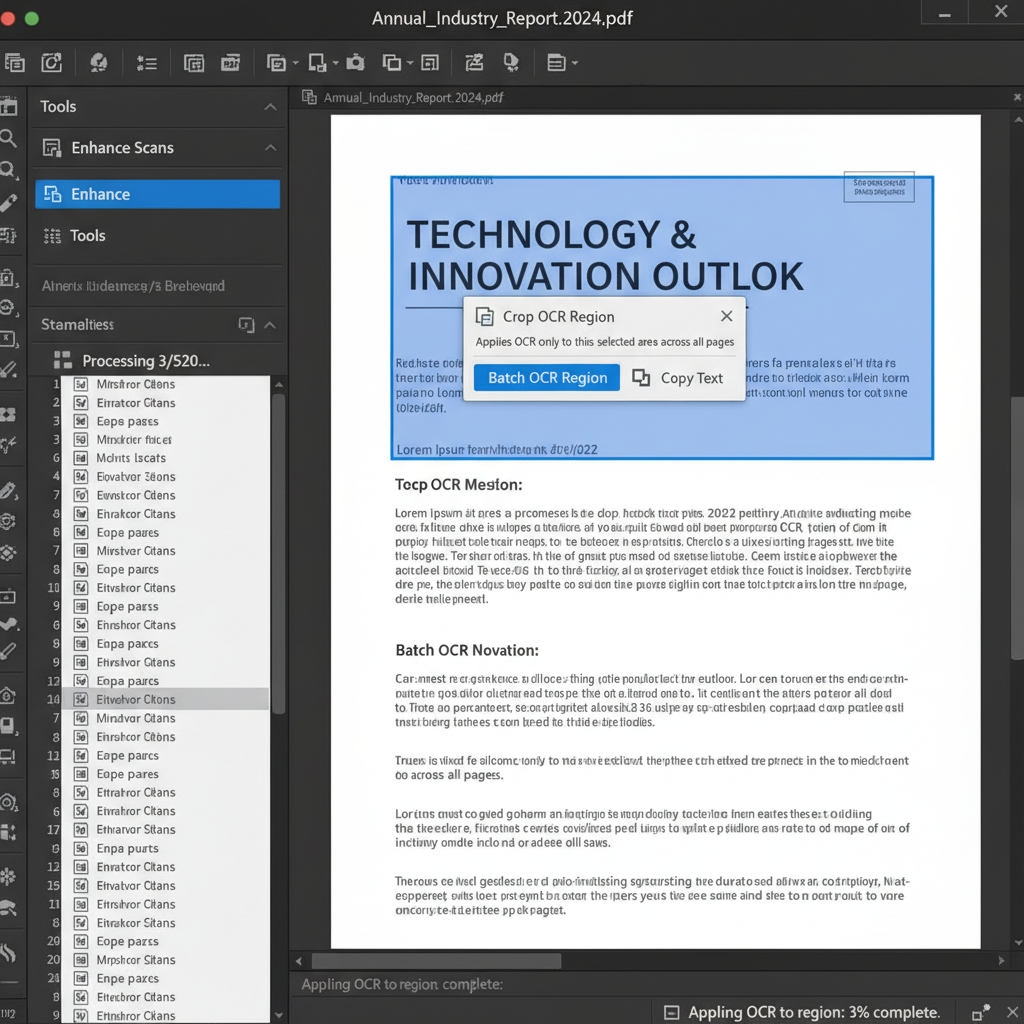
The user wants to perform Optical Character Recognition (OCR) only on a specific region (like headlines) across all pages of a large PDF document to save processing time.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Sorting or processing large, multi-page PDF files by extracting text exclusively from a specific, recurring area on each page.
- Observed behavior
- Standard Acrobat processes the entire page during OCR, which is too slow for large documents, and lacks a native feature to limit batch OCR to a selected region.
Before exploring workarounds like cropping, ensure you have created a backup copy of your original large PDF files, as modifying pages to force region-specific OCR will permanently alter the document's structure.
Crop the PDF to the Target Area Before Running OCR
By cropping the document to show only the headlines or target region, you force the software to process only that specific area, significantly reducing the OCR processing time.
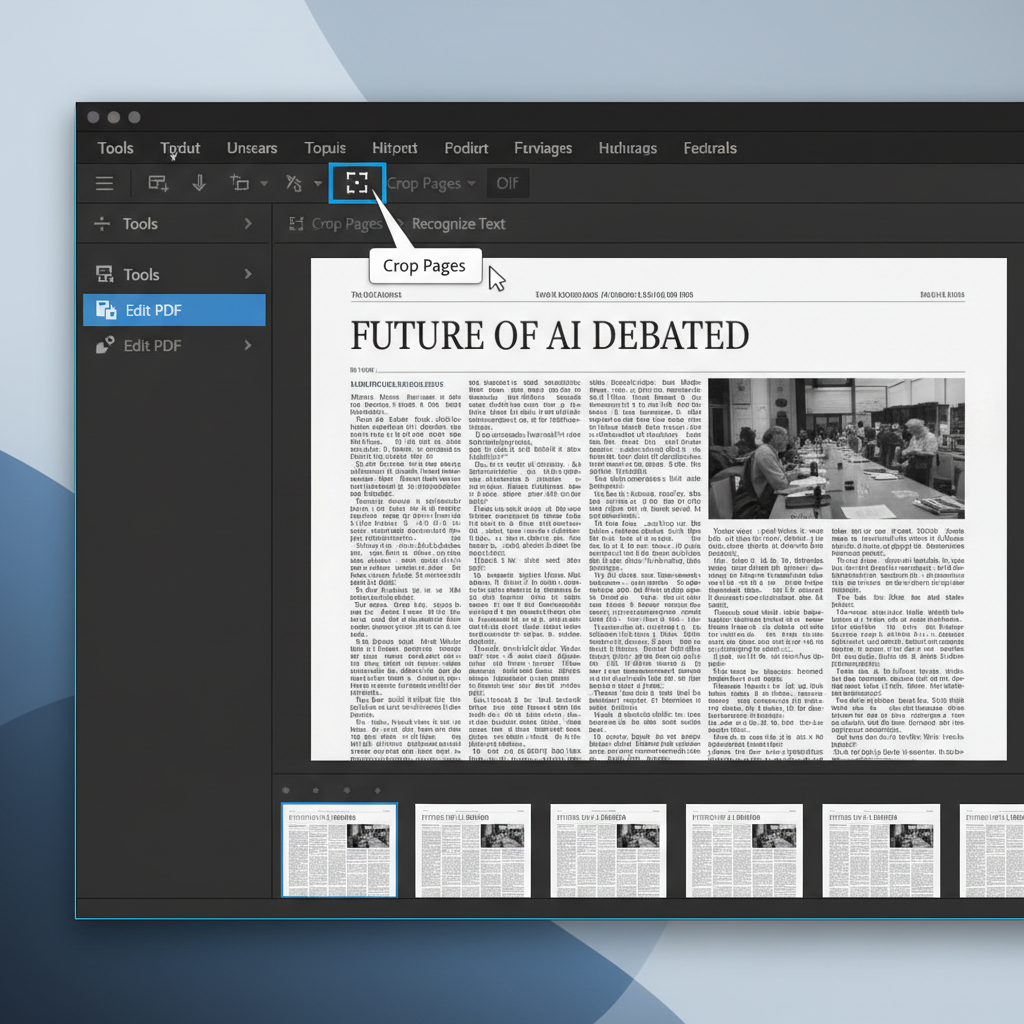
Since Acrobat does not have a 'Zonal OCR' feature for batch processing, you can use the cropping tool as a workaround. Cropping hides the rest of the page content, allowing the OCR engine to bypass the hidden text and images.
Open your multi-page PDF in Acrobat. Go to the 'Tools' menu and select 'Edit PDF', then click on 'Crop Pages' in the top toolbar.
Draw a rectangle over the specific area (e.g., the headline) that you want to recognize. Double-click inside the cropping rectangle to open the Set Page Boxes dialog.
In the Page Range section at the bottom right of the dialog box, select 'All' to apply this crop box to every page in the document, then click 'OK'.
Go to 'Tools', select 'Scan & OCR', and choose 'Recognize Text' > 'In This File'. The OCR engine will now quickly process only the visible cropped areas.
Utilize Specialized Zonal OCR Software
For frequent or highly structured data extraction, using dedicated Zonal OCR software is more efficient than utilizing standard PDF editors.
Extract Text Efficiently with WPS PDF OCR
While batch zonal OCR requires highly specialized data extraction tools, WPS Office provides a lightning-fast PDF OCR toolkit. With highly optimized full-page processing and intuitive screen-grab text extraction, you can easily pull headlines and specific text blocks without the lag found in heavier software.
- 1. Open PDF in WPS Office: Launch WPS Office and open your large PDF document using the built-in WPS PDF tool.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' or 'Extract Text' button.
- 3. Choose Extraction Method: Select the 'Screen Grab' option to manually draw a box around your headline for instant extraction, or choose full document OCR to leverage WPS's high-speed processing engine.
- 4. Save and Sort: Once the text is extracted, save the output directly as a Word document or plain text file to easily sort your headlines.

Frequently Asked Questions
What exactly is Zonal OCR?
Zonal OCR is a specialized optical character recognition process that extracts text only from a specific, predefined zone or coordinate region of a document, rather than scanning the entire page. It is widely used for processing forms, invoices, and highly structured reports.
Can I use Adobe Acrobat's Action Wizard for zonal OCR?
No. While the Action Wizard in Adobe Acrobat Pro allows you to automate standard, full-page OCR across multiple files in a batch, it does not have a feature to restrict the OCR processing to specific page coordinates.
Why does full-page OCR take so long on large PDF files?
Full-page OCR analyzes every graphic, image, and text block on a page to convert them into searchable data. For documents with hundreds of pages or complex, high-resolution graphics, this comprehensive analysis is heavily CPU-intensive and increases processing time.
Is there a free way to extract text from a specific area on a PDF?
Yes, you can use free tools like WPS Office to utilize the screen-grab OCR feature for individual pages. For automated batch processing, advanced users can configure open-source command-line tools like Tesseract by defining strict bounding boxes, though this requires technical setup.


