

Extract Text and Remove Duplicate PDF Pages Using Acrobat JavaScript

Question details
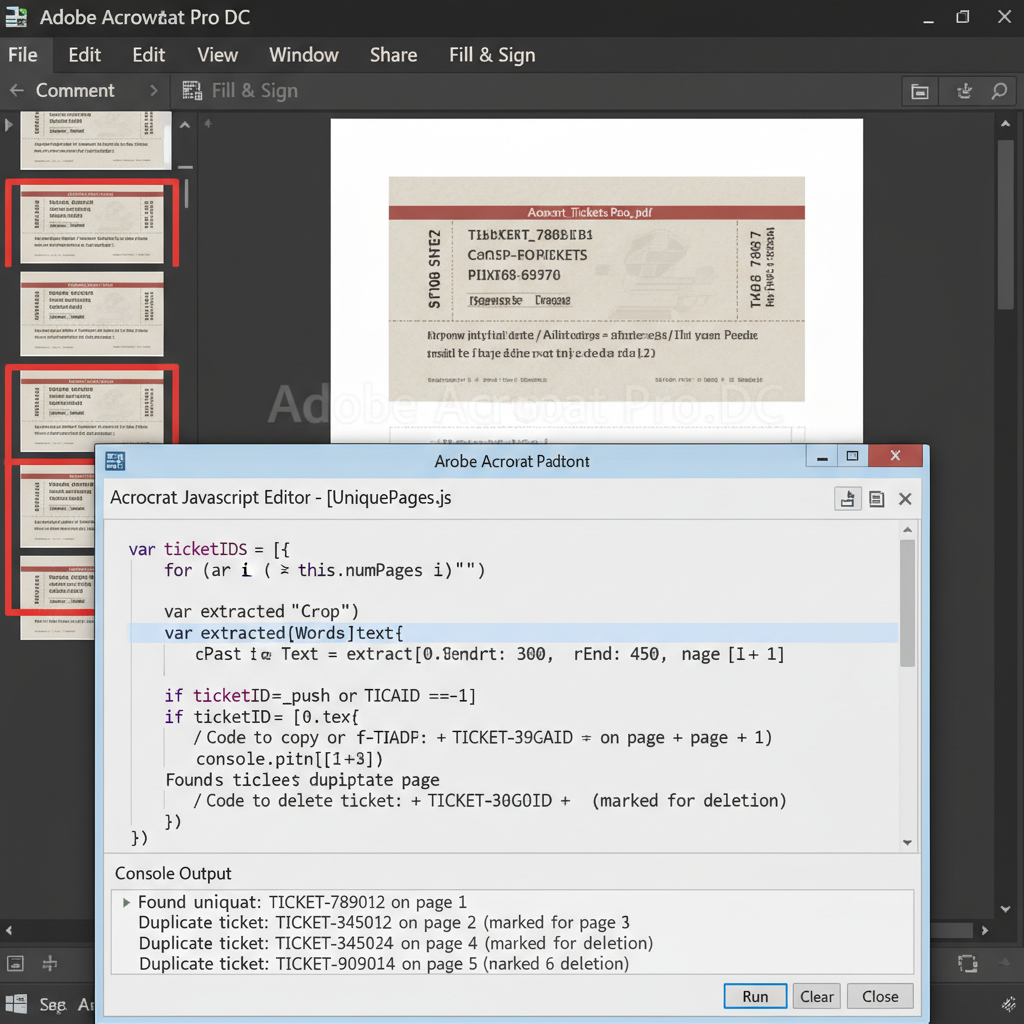
The user needs to use Acrobat JavaScript to read specific text (ticket IDs) from a defined area on each PDF page and delete duplicate pages to keep only the unique ones.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Managing large PDF files containing ticket IDs where duplicate pages need to be identified and removed programmatically.
- Observed behavior
- The user is looking for a scripting method to inspect specific word coordinates, track processed ticket IDs, and copy or extract only unique pages.
Ensure you have Adobe Acrobat Pro installed, as Adobe Reader does not support running advanced page extraction and deletion scripts. Back up your original PDF before running any JavaScript to prevent accidental data loss.
Use Acrobat JavaScript to Identify and Remove Duplicates
Utilize the getPageNthWordQuads and getPageNthWord functions to identify specific ticket IDs based on coordinates and filter out duplicate pages.
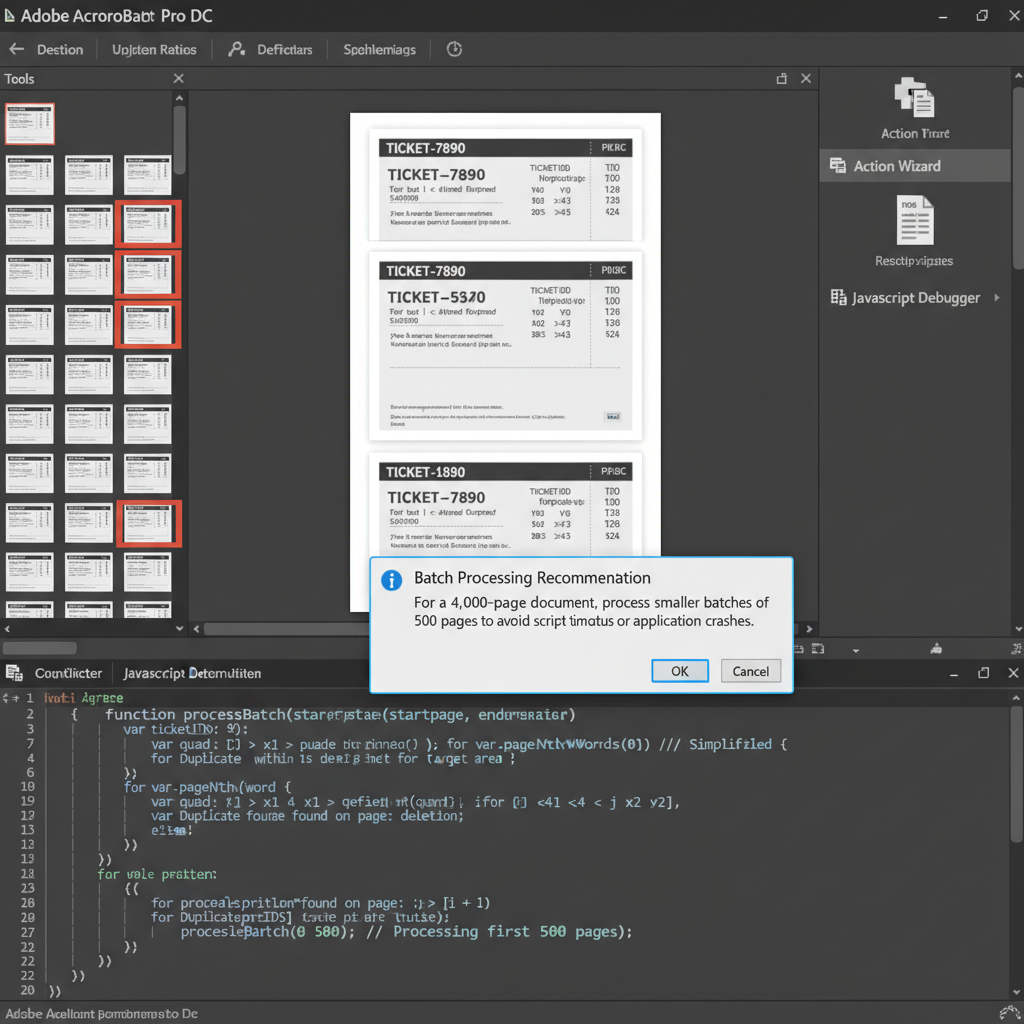
When dealing with large PDFs (e.g., 4,000 pages), Acrobat may become unresponsive or unreliable if the script tries to process everything at once. It is highly recommended to process the document in smaller batches to ensure stability.
Determine the exact coordinates of the area where the ticket ID appears on your PDF pages.
Use the getPageNthWordQuads JavaScript function to get the positional coordinates of the words on each page.
Compare the retrieved coordinates with your defined target area. If a word falls within this area, use the getPageNthWord function to extract the text, which represents your ticket ID.
Maintain an array or object to keep track of processed ticket IDs. If an ID has already been recorded, mark that page for deletion or skip it when extracting unique pages to a new document.
Extract and Manage PDF Pages Visually with WPS Office
While running complex JavaScripts requires programming knowledge, WPS Office provides an intuitive, visual PDF editor. You can easily view all pages, select the ones you want to extract, and delete unwanted duplicates with just a few clicks.
- 1. Open your PDF in WPS: Launch WPS Office and open your PDF document using the built-in PDF editor.
- 2. Access Page Management: Navigate to the 'Page' tab on the top toolbar to view thumbnails of all document pages.
- 3. Select and Delete Pages: Manually select any duplicate or unwanted pages, then click the 'Delete' icon to remove them from your document.
- 4. Extract Unique Pages: Select the unique pages you wish to keep, click 'Extract Pages', and save them as a completely new PDF document.

Frequently Asked Questions
Why does Acrobat crash when running JavaScript on large PDF files?
Acrobat may become unreliable or run out of memory when executing heavy scripts on large documents. It is recommended to process large files, such as a 4,000-page document, in smaller batches of around 500 pages.
What is getPageNthWordQuads used for in Acrobat JavaScript?
The getPageNthWordQuads function is used to retrieve the exact coordinates (bounding box) of specific words on a PDF page, which is essential for identifying text located in defined visual areas.
Can I remove duplicate PDF pages automatically without scripting?
Most standard PDF software requires manual review to delete duplicate pages. However, you can use built-in visual page management tools in editors like WPS PDF or Acrobat to identify and delete duplicates without needing to write code.


