

Fix Acrobat Converting Existing PDF to Scanned Image When Editing

Question details
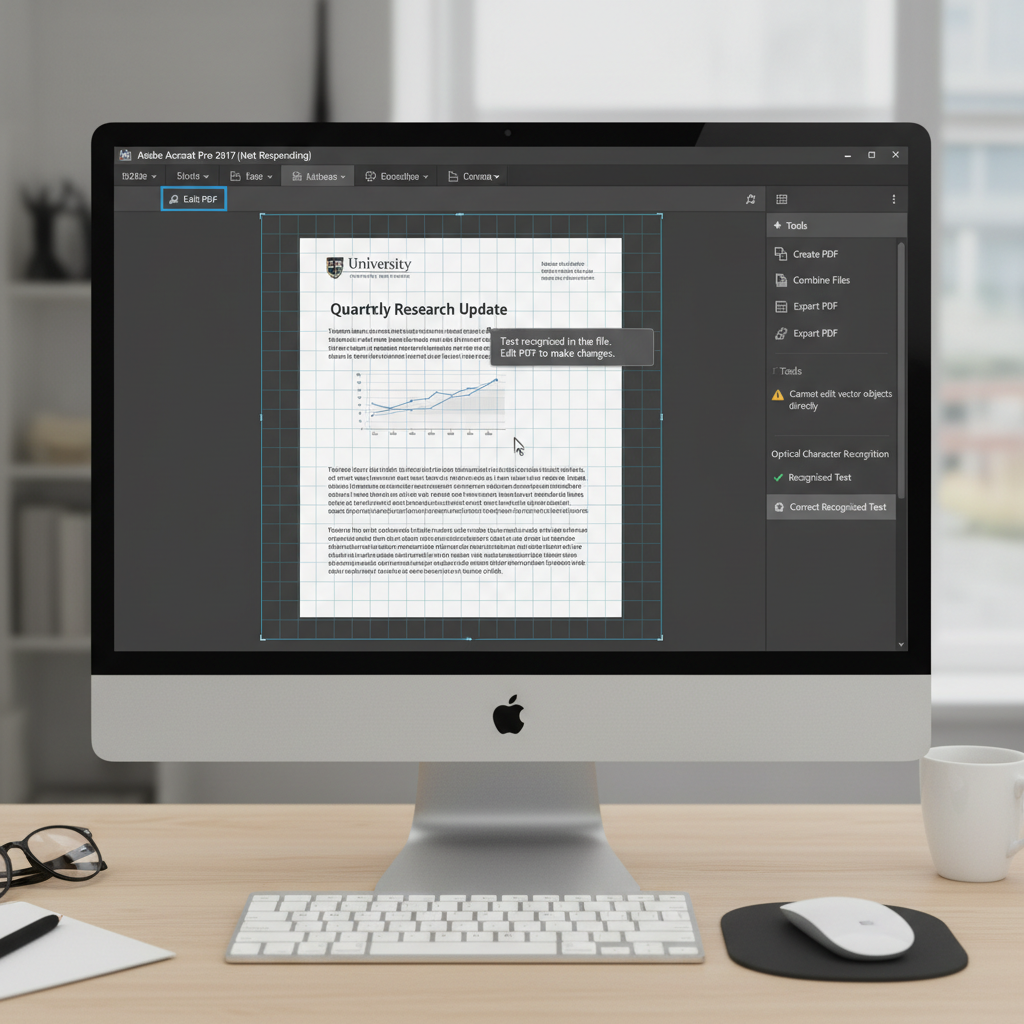
The user is unable to edit individual text and image elements in a PDF using Acrobat Pro 2017, as the document behaves like a scanned image when editing tools are selected.
- Product
- Adobe Acrobat Pro 2017
- Device & OS
- not provided
- Scenario
- Attempting to edit an existing PDF document using standard PDF editing tools.
- Observed behavior
- The PDF converts to or behaves like a scanned image upon selecting editing tools, preventing the editing of individual text and image elements, despite accurate text recognition.
Ensure you have a backup copy of your original PDF file before applying Optical Character Recognition (OCR) or altering document properties, as flattening or text recognition can permanently change the file structure.
Configure OCR and Recognize Text Settings in Acrobat
Adjusting the automatic OCR settings and manually running text recognition can convert the scanned image back into editable text and graphics.
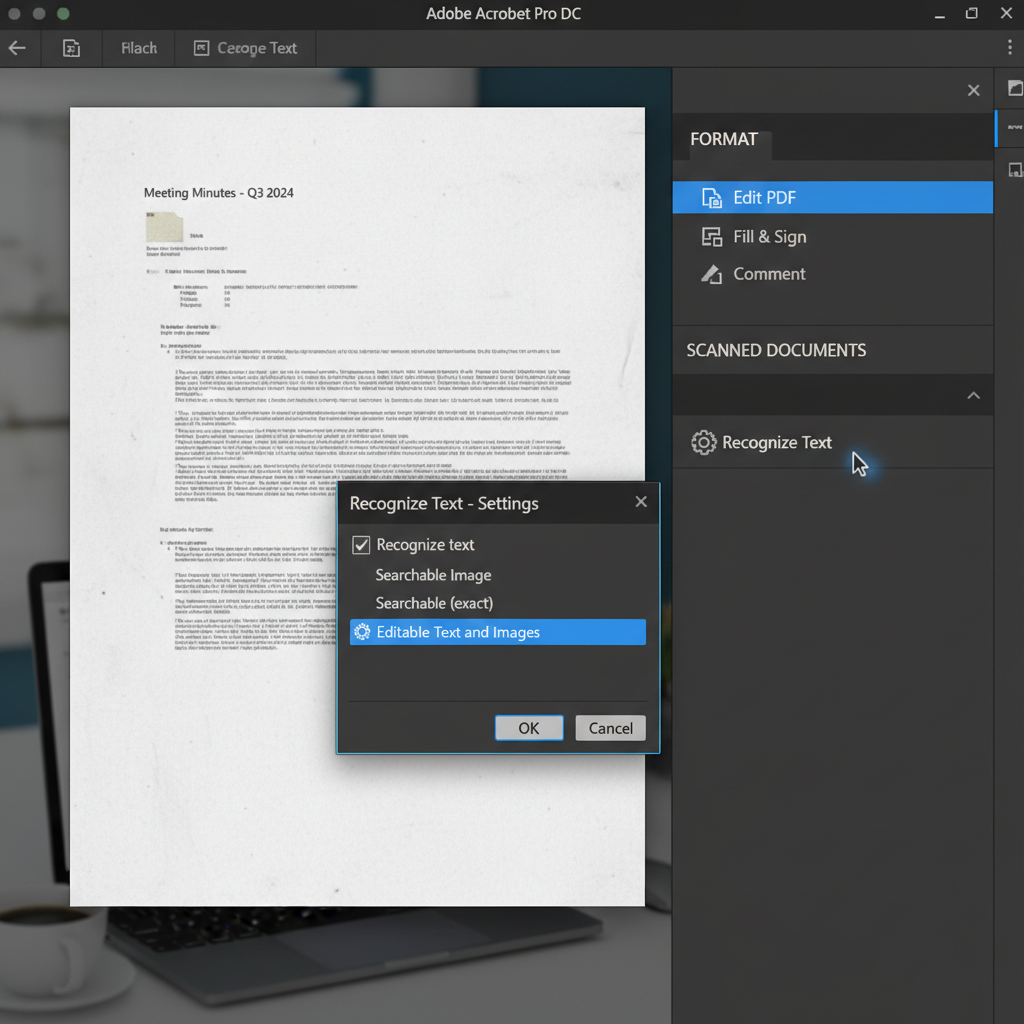
When Acrobat detects an image-based or scanned PDF, it may default to rendering the page as a single image. Adjusting the Recognize Text settings ensures the software outputs independently editable elements instead of a searchable image.
Open the problematic PDF in Adobe Acrobat and click on the 'Edit PDF' tool located in the right-hand pane.
In the right-hand formatting pane, scroll down to find the 'Scanned Documents' section.
Click on 'Settings' under the Scanned Documents section. Change the Output style from 'Searchable Image' to 'Editable Text and Images'.
If automatic text recognition is interfering with existing text layers, try unchecking the 'Recognize text' box to prevent Acrobat from converting the page into an image-based layout.
Verify if the PDF is Flattened or Image-Based
Determine if the file was exported or saved as a flattened image, which natively removes editable text layers.
Edit Scanned PDFs Seamlessly with WPS Office
WPS Office provides a robust, built-in PDF editor equipped with highly accurate OCR technology. It allows you to easily convert scanned documents and image-based PDFs into fully editable text and graphics without the hassle of complex settings.
- 1. Open the PDF: Launch WPS Office and click on the 'PDF' tab to open your image-based or scanned document.
- 2. Access the OCR Tool: Navigate to the 'Tools' or 'Edit' menu on the top toolbar and click on the 'OCR' button.
- 3. Convert to Editable Document: Select 'Convert to Editable PDF' or 'Extract Text' depending on whether you want to retain the layout or just copy the text.
- 4. Edit Text and Images: Wait a few seconds for the conversion to finish, then click on any text or image to start editing directly.

Frequently Asked Questions
Why does my PDF turn into an image when I try to edit it?
This typically occurs if the PDF was originally created as a scanned document or flattened image, and your PDF editor's automatic OCR (Optical Character Recognition) feature processes the entire page as a single graphic before attempting to overlay editable text.
How do I stop Adobe Acrobat from automatically running OCR?
In Adobe Acrobat, select the 'Edit PDF' tool, look at the right-hand formatting pane, find the 'Scanned Documents' section, and uncheck the 'Recognize text' option to prevent the automatic conversion.
Can I recover the original editable text if a PDF was flattened?
Once a PDF is flattened into an image, the original, independent text layers are permanently merged. To edit it, you must use an OCR tool to recognize and recreate the text, though you may need to manually adjust formatting and fonts.
Does WPS Office support editing scanned PDFs?
Yes, WPS Office includes a powerful OCR feature that can scan image-based PDFs and convert them into fully editable documents, allowing you to modify text, images, and layouts easily.


